

@zonderlabs, generative 3d @Stanford, @CarnegieMellon, @UMich
Bay Area | NYC
Joined September 2021
- Tweets182
- Following892
- Followers1K
- Likes2.6K




Pinned Tweet
Why is AI slop so frustrating to read?
AI writing often obscures main ideas and invents awkward phrases, making sentences more complex than necessary.
Many of these slop patterns violate writing principles established in English writing books.
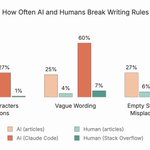
In our benchmark, AI writing breaks these principles far more often than human writing, with Claude Code replies by far the worst offenders.
We show examples of the most common slop patterns in this thread

ALT How often AI and humans break writing rules
Fable 5.2 is not better at writing
A perfect example of why we need to align AI writing for humans!


Why is AI slop so frustrating to read?
AI writing often obscures main ideas and invents awkward phrases, making sentences more complex than necessary.
Many of these slop patterns violate writing principles established in English writing books.
In our benchmark, AI writing breaks these principles far more often than human writing, with Claude Code replies by far the worst offenders.
We show examples of the most common slop patterns in this thread
ALT How often AI and humans break writing rules
Finally, AI writing often has no prioritization of the points it wants to make. This results in sentences that are devoid of meaning or sentences that have multiple distracting points. 4/5

This writing stuff matters because the majority of the internet we consume is AI generated. And as work, research, and technical communication become increasingly AI generated, we must make sure that AI communicates clearly in a way that us, humans, can understand.
Read more about slop and explore interactive demos on our web page zonderlabs.com/slop
And if you vibe with our mission, please reach out!

Zhizhuo (Z) Zhou retweeted

As humans, we easily infer object articulations from a couple of examples, or even none.
For vision models, figuring that out is a completely different story.
Our new paper "FAMOS: Feed-Forward 3D Articulation Modeling from Sparse Observations" (WACV 2027) takes a stab at it!

ALT https://kevinqu7.github.io/famos/
Zhizhuo (Z) Zhou retweeted
simply including "write in ASD-STE100" in your prompt makes a huge difference in ai readability
we benchmarked before / after "write in ASD-STE100" with Opus 5.5, and sentences became easier to read


We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.

simply including "write in ASD-STE100" in your prompt makes a huge difference in ai readability
we benchmarked before / after "write in ASD-STE100" with Opus 5.5, and sentences became easier to read
We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.
Zhizhuo (Z) Zhou retweeted

In 12 weeks, we built a research facility that is run entirely by AI.
AI designs, executes, and observes experiments end-to-end across biology, chemistry, and materials science.
We’re introducing SciUniverse: a benchmark that measures AI’s ability to do real-world scientific research.
Zhizhuo (Z) Zhou retweeted

Introducing OM-1, our first robot foundation model: zero-shot generalizing across table-top arms, industrial arms, and humanoids.
- Learned directly from human manipulation data
- No teleop or robot data
- Near human-level dexterity and efficiency
- Multi-robot collaboration


at @BuzzSearchAI we also believe in "what-if" questions.
and we believe a huge part of "what-if" simulation is understanding user behavior.
and we are ingesting social media comments from users at a scaling-law scale

Most big decisions are some version of a “what-if” question.
What if we launched this? What if we raised the price? What if we didn’t?
At Simile, we’re building a What-If Machine to simulate those decisions before making them for real. But getting the answer right requires understanding both what people do and why they do it.
@msbernst explains what it takes to build one.
simile.com/blog/what-if-mach…

10
1,572
Claude Code and Fable 5.1 removed em-dashes!
but does it actually read better with clarity?
we took a look at the changes behind Fable 5.1's perceived writing improvements, and the secret is a new system prompt

1
4
766
Claude Code added a new rule for writing turned on by default for Fable models that specifically removes em-dashes, parentheticals, and arrows--as well as semicolon joined phrases

1
1
336
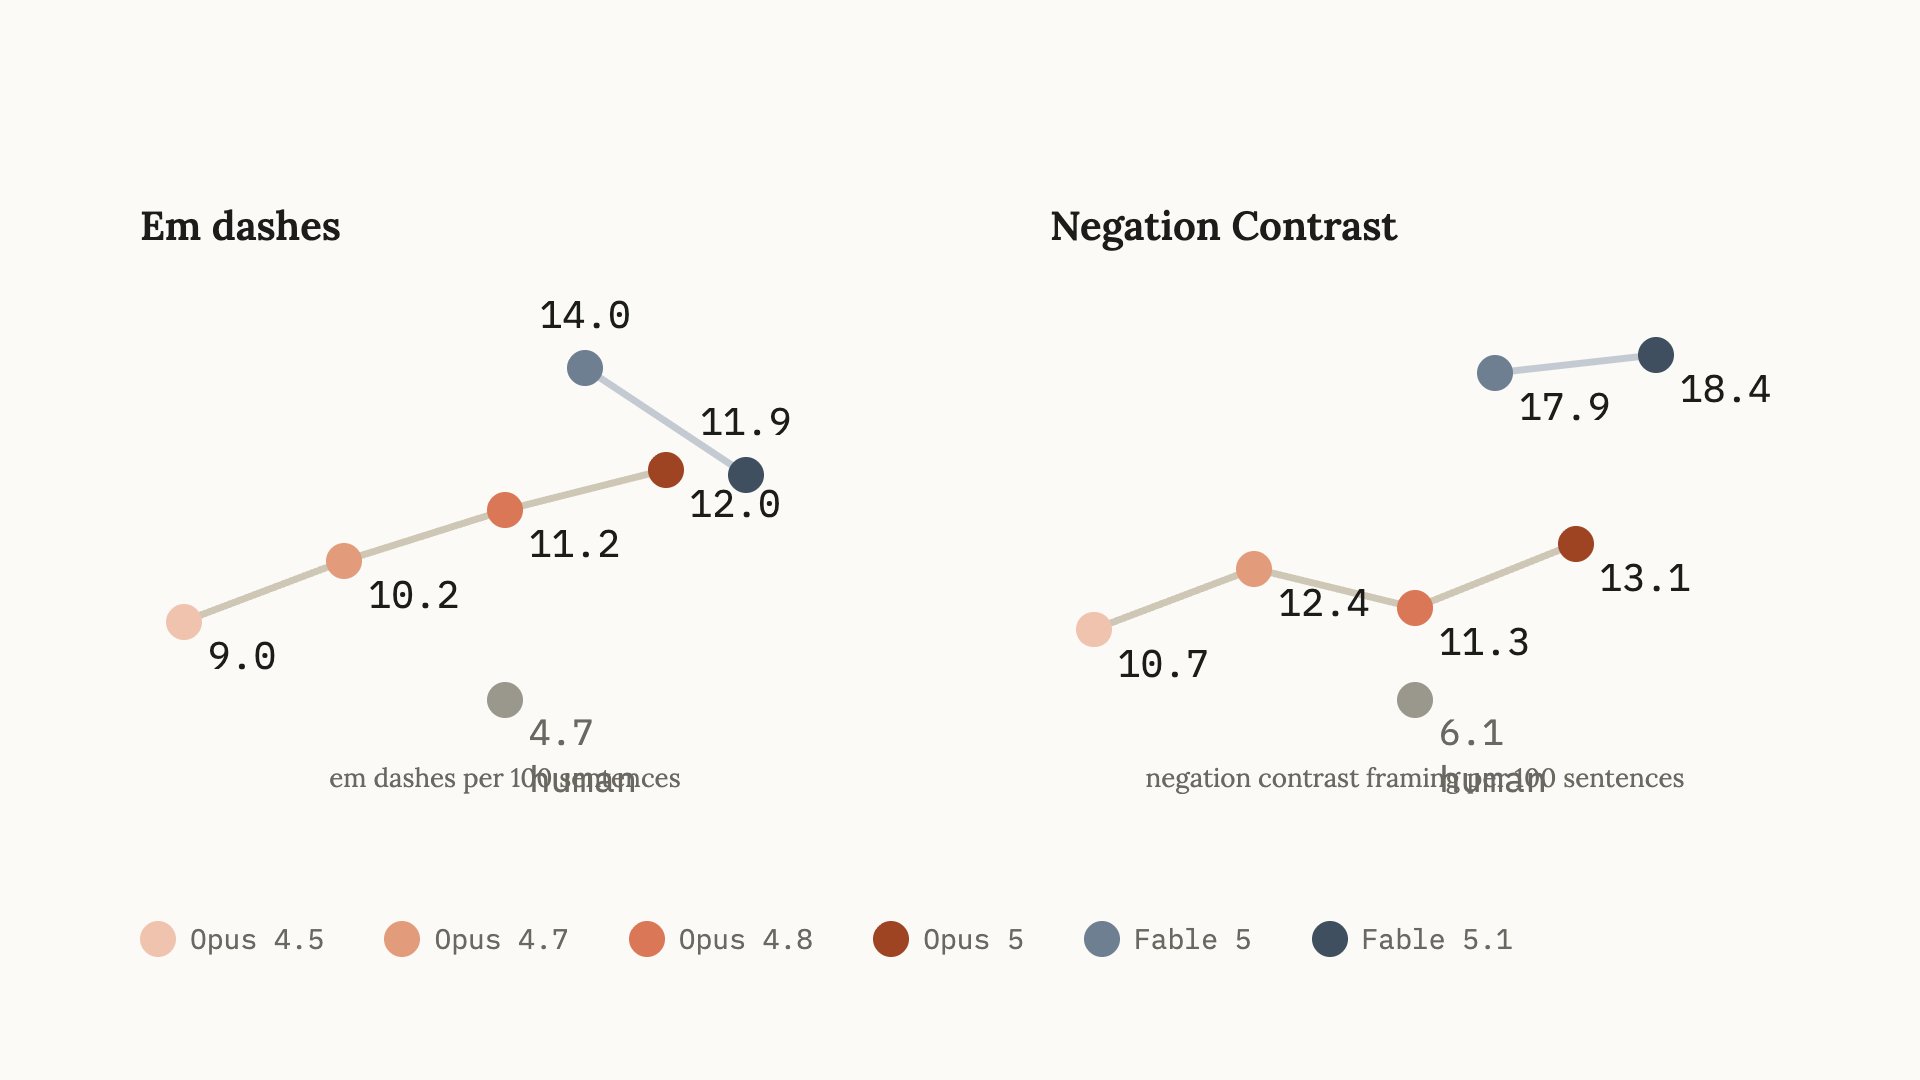
I started seeing more and more slop comments from claude code, so I plotted the two most annoying slop artifacts across Opus versions
More than just these slop artifacts, AI writing has also become more circuitous and hard to understand.
I will be looking into quantifying AI slop, more soon!

Zhizhuo (Z) Zhou retweeted

LoRA, low-rank adaptation, is arguably the most popular parameter-efficient fine-tuning method for LLMs.
But how does it actually work?
Check out the video to learn LoRA and friends (LoRA+, QLoRA, VeRA, and DoRA)!
youtu.be/U80tjcThl9Q
