

Making efficiency-first LLMs & Applications.
Joined February 2025
- Tweets202
- Following5
- Followers3.8K
- Likes139


Pinned Tweet
🚨ThinkingCap: Gemma-4-26B-A4B is out!
The most token-efficient Gemma-4-26B-A4B available.
🚀Up to 69% fewer thinking tokens, 38.9% on average
🎯Negligible accuracy loss 0.15pp
🏢ThinkingCap PRO: up to 87.6% fewer thinking tokens, 62% on average - Contact our enterprise[at]bottlecapai[dot]com
📄Blogpost: bottlecapai.com/post/thinkin…
🤗Hugging Face: huggingface.co/bottlecapai/T…
🔗GGUF: huggingface.co/bottlecapai/T…

BottleCapAI retweeted

One of the most interesting AI labs in Europe is being built out of Prague
The team believe that frontier models drastically overthink, and therefore burn tokens unnecessarily
So @BottleCapAI (named after Europe's greatest innovation) takes an existing open model and trains it to think less while staying just as accurate.
Last week the lab released 3 models:
>> Nvidia’s Nemotron: up to 31% and on average 23% less thinking, with comparable benchmark accuracy
>> Alibaba’s Qwen3.8-Flash-Next: spending 39% fewer thinking tokens on average for about a point of accuracy loss
>> Google’s Gemma 4: their first ThinkingCap on a Google model, with 39% fewer thinking tokens on average for just 0.15pp of accuracy
The impact of what they're building is less token spend and less hardware is required.
VERY COOL
@JaroslavBeck @itsdavidherel

🚨ThinkingCap: Gemma-4-26B-A4B is out!
The most token-efficient Gemma-4-26B-A4B available.
🚀Up to 69% fewer thinking tokens, 38.9% on average
🎯Negligible accuracy loss 0.15pp
🏢ThinkingCap PRO: up to 87.6% fewer thinking tokens, 62% on average - Contact our enterprise[at]bottlecapai[dot]com
📄Blogpost: bottlecapai.com/post/thinkin…
🤗Hugging Face: huggingface.co/bottlecapai/T…
🔗GGUF: huggingface.co/bottlecapai/T…
The ThinkingCap series keeps growing.
Last week we released:
→ Nemotron 3.5 Lightning: up to 2.3x more requests served at once
→ Qwen3.8-Flash-Next: up to 51% fewer thinking tokens
→ Gemma 4 26B: up to 69% fewer thinking tokens
Have fun!
bottlecapai.com/#products

PRO versions also available: enterprise[at]bottlecapai.com

📷 Same prompt. Same hardware. Who gets there first?
ThinkingCap: Gemma-4-26B-A4B vs. the original, head to head on:
🌟Astrophysics: multiple-choice science
🐍Python: coding
📐Geometry: competition maths
🧬Biology: multiple-choice science
Release hat-trick 🚀🚀🚀 3 releases in 3 days!
ThinkingCap isn't just for Qwen. It works across model families, from Alibaba's Qwen to NVIDIA and Google:
Day 1 → NVIDIA Nemotron-3.5-Lightning-30B-A3B
x.com/BottleCapAI/status/211…
Day 2 → Qwen3.8-Flash-Next
x.com/BottleCapAI/status/211…
Day 3 → Google Gemma-4-26B-A4B (you're here)
Need even fewer thinking tokens? ThinkingCap PRO goes further, tuned to your workload. 📧 enterprise[at]bottlecapai[dot]com
🚨ThinkingCap: Qwen3.8-Flash-Next is out!
The most token-efficient Qwen3.8-Flash-Next available.
🚀Up to 51% fewer thinking tokens, 38.5% on average
🎯Negligible accuracy loss 1.03pp
🏢ThinkingCap PRO: 60% fewer thinking tokens on average - Contact our enterprise[at]bottlecapai [dot]com
📄Blogpost: bottlecapai.com/post/thinkin…
🤗Hugging Face: huggingface.co/bottlecapai/T…
🔗GGUF: huggingface.co/bottlecapai/T…

BottleCapAI retweeted
🚨ThinkingCap: Qwen3.8-Flash-Next is out!
The most token-efficient Qwen3.8-Flash-Next available.
🚀Up to 51% fewer thinking tokens, 38.5% on average
🎯Negligible accuracy loss 1.03pp
🏢ThinkingCap PRO: 60% fewer thinking tokens on average - Contact our enterprise[at]bottlecapai [dot]com
📄Blogpost: bottlecapai.com/post/thinkin…
🤗Hugging Face: huggingface.co/bottlecapai/T…
🔗GGUF: huggingface.co/bottlecapai/T…
BottleCapAI retweeted
🚨ThinkingCap: NVIDIA Nemotron3.5 Lightning30B A3B is out!
⚡️Up to 2.3x more requests for multi user use compared to original Nemotron version.
🚀 Up to 31%, on average 23% fewer thinking tokens
🎯 Minimal accuracy loss - 0.88pp
📄 Blogpost: bottlecapai.com/post/thinkin…
🤗 Hugging Face: huggingface.co/bottlecapai/T…
🔗 GGUF: huggingface.co/bottlecapai/T…
🏢 Want a variant tuned for your own workload, proven on your own evals, or access to our better internal model?
Contact us at enterprise [at] bottlecapai.com
We made for all interested researchers new open task, the ThinkingCap Test 👉 github.com/BottleCapAI/Think…
Details: bottlecapai.com/careers/natu…

BottleCapAI retweeted
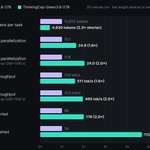
🚨 Same model size. Same GPU. ~4.7x more work done!
ThinkingCap: Qwen 3.8 reaches answers with about half the reasoning. On a shared server, that means 2x more users fit in memory at once, and each finishes 2x faster.
Running it solo? ~2x faster answers.
Serving a team? ~4.7x throughput. 🚀
🤗 Hugging Face: huggingface.co/bottlecapai/T…

