

Making efficiency-first LLMs & Applications.
Joined February 2025
- Tweets202
- Following5
- Followers3.8K
- Likes139


BottleCapAI retweeted

One of the most interesting AI labs in Europe is being built out of Prague
The team believe that frontier models drastically overthink, and therefore burn tokens unnecessarily
So @BottleCapAI (named after Europe's greatest innovation) takes an existing open model and trains it to think less while staying just as accurate.
Last week the lab released 3 models:
>> Nvidia’s Nemotron: up to 31% and on average 23% less thinking, with comparable benchmark accuracy
>> Alibaba’s Qwen3.8-Flash-Next: spending 39% fewer thinking tokens on average for about a point of accuracy loss
>> Google’s Gemma 4: their first ThinkingCap on a Google model, with 39% fewer thinking tokens on average for just 0.15pp of accuracy
The impact of what they're building is less token spend and less hardware is required.
VERY COOL
@JaroslavBeck @itsdavidherel

🚨ThinkingCap: Gemma-4-26B-A4B is out!
The most token-efficient Gemma-4-26B-A4B available.
🚀Up to 69% fewer thinking tokens, 38.9% on average
🎯Negligible accuracy loss 0.15pp
🏢ThinkingCap PRO: up to 87.6% fewer thinking tokens, 62% on average - Contact our enterprise[at]bottlecapai[dot]com
📄Blogpost: bottlecapai.com/post/thinkin…
🤗Hugging Face: huggingface.co/bottlecapai/T…
🔗GGUF: huggingface.co/bottlecapai/T…

BottleCapAI retweeted
🚨ThinkingCap: Qwen3.8-Flash-Next is out!
The most token-efficient Qwen3.8-Flash-Next available.
🚀Up to 51% fewer thinking tokens, 38.5% on average
🎯Negligible accuracy loss 1.03pp
🏢ThinkingCap PRO: 60% fewer thinking tokens on average - Contact our enterprise[at]bottlecapai [dot]com
📄Blogpost: bottlecapai.com/post/thinkin…
🤗Hugging Face: huggingface.co/bottlecapai/T…
🔗GGUF: huggingface.co/bottlecapai/T…

BottleCapAI retweeted
🚨ThinkingCap: NVIDIA Nemotron3.5 Lightning30B A3B is out!
⚡️Up to 2.3x more requests for multi user use compared to original Nemotron version.
🚀 Up to 31%, on average 23% fewer thinking tokens
🎯 Minimal accuracy loss - 0.88pp
📄 Blogpost: bottlecapai.com/post/thinkin…
🤗 Hugging Face: huggingface.co/bottlecapai/T…
🔗 GGUF: huggingface.co/bottlecapai/T…

BottleCapAI retweeted
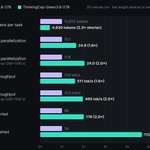
🚨 Same model size. Same GPU. ~4.7x more work done!
ThinkingCap: Qwen 3.8 reaches answers with about half the reasoning. On a shared server, that means 2x more users fit in memory at once, and each finishes 2x faster.
Running it solo? ~2x faster answers.
Serving a team? ~4.7x throughput. 🚀
🤗 Hugging Face: huggingface.co/bottlecapai/T…

BottleCapAI retweeted
Actually we were very busy with another big project in works, but I am glad we finally got some time to polish Qwen 3.8 27b with our ThinkingCap. A lot positive feedback so far!🙏
🚨ThinkingCap: Qwen3.8-27B is out!
The most token-efficient Qwen3.8 27B available, this time optimized for agentic use.
🚀 Up to 65% fewer thinking tokens, 37% on average
🎯 Minimal accuracy loss
📈 Long-context retrieval actually went up 2.3pp
📄 Blogpost: bottlecapai.com/post/thinkin…
🤗 Hugging Face: huggingface.co/bottlecapai/T…
🔗 GGUF: huggingface.co/bottlecapai/T…

BottleCapAI retweeted
🚨ThinkingCap: Qwen3.8-27B is out!
The most token-efficient Qwen3.8 27B available, this time optimized for agentic use.
🚀 Up to 65% fewer thinking tokens, 37% on average
🎯 Minimal accuracy loss
📈 Long-context retrieval actually went up 2.3pp
📄 Blogpost: bottlecapai.com/post/thinkin…
🤗 Hugging Face: huggingface.co/bottlecapai/T…
🔗 GGUF: huggingface.co/bottlecapai/T…
BottleCapAI retweeted
Official NVFP4 W4A16 version is out!
W4A4 variant is still under consideration, and we’d welcome your feedback. huggingface.co/bottlecapai/T…

BottleCapAI retweeted
ThinkingCap + FP8 quantization + MTP decoding runs 5–7× faster than the original Qwen 3.6 27B on the same tasks! 🚀
For comparison, FP8 + MTP without ThinkingCap gets you less than half that gain.
BottleCapAI retweeted

@BottleCapAI's first model is no Top 4 trending on @huggingface 🤯 — behind only GLM-5.2, Hy3 and a Mythos distill. ~350k downloads of the quants in 4 days.
The 50% speedup isn't just a claim anymore: verified by multiple community evals (huggingface.co/bottlecapai/T… and youtu.be/ZTHVEsIEyas).
Try it via API on @RequestyAI app.requesty.ai/model-librar…

BottleCapAI retweeted

BottlecAIよりThinkingCap-Qwen3.6-27B-FP8がリリースされた。リリース即300KダウンロードされたThinking長さを半減以下しつつ賢さ維持という特徴を持つモデルの8ビット版だ
vLLMで動かすことができるというので、これは是非試したい。さらに明瞭簡潔かもしれないぞ!
huggingface.co/bottlecapai/T…

BottleCapAI retweeted

Ever wished your AI could think ahead and save tokens? Meet ThinkingCap-Qwen3.6-27B, a GGUF model that uses Multi-Token Prediction (MTP) and speculative decoding to generate faster and smarter. It's a game changer for token efficiency.

BottleCapAI retweeted

Best version of Qwen 3.6 27B yet, imho... Huihui-ThinkingCap-Qwen3.6-27B-abliterated-NVFP4. So what makes it different from other 27B quants?
* ThinkingCap finetune cuts thinking tokens ~46% with no accuracy loss. Less rambling, same answers.
It's abliterated (uncensored) so there is no refusal filter.
* NVFP4 W4A4 quantization so it's a mere 20.6 GB, fits on a single 24 GB card. vLLM 0.21+ auto-detects it.
* Vision tower kept in bf16 so it is still multimodal!
* MTP speculative decoding head kept in bf16. It allows vLLM to draft 3 tokens ahead for faster generation.
* Full 128K context at TP=2 (hybrid attention KV is lighter).
Many other 27B quants are just the base model compressed. This one stacks shorter reasoning + uncensored + 4-bit + spec decode + vision into one download. Incredible work @support_huihui and @Tono_Ken3

公開からわずか2日間で30万ダウンロードされたQwen3.6-27bを賢いままで最大90%Thinkingを切り詰めるThinkingCapにHuihuiさんが無検閲化加工を施した!
これは最強タッグなので早速NVFP4にて焼きました。私はメインで使います
モデルファイルは20GB強です
huggingface.co/sakamakismile…

BottleCapAI retweeted

ThinkingCap-Qwen3.6-27B is really good.
Much faster than the original Qwen3.6-27B thanks to shorter thinking, while preserving accuracy.
Also one of the best evaluation I have seen for a custom Qwen3.6 27B: lot of benchmarks, sigtest, token count, etc. That's all very convincing.
I'll publish my own evaluations for this model soon.
BottleCapAI retweeted

💥 Qwen3.6-27B just got a THINKING CAP
⚡ same weights, same accuracy, way less thinking
🔹Finetuned by bottlecapai for token-efficient reasoning, no architecture changes
🔹Cuts thinking tokens by up to 36% on hard multi-join SQL optimization tests
🔹Matched base Qwen3.6-27B's answer quality on every test, riddles to correlated subqueries
🔹Runs fully local on llama.cpp, tested live side-by-side on an RTX A6000
Watch the full breakdown below:👇
youtu.be/ZTHVEsIEyas

BottleCapAI retweeted
I like a model that's Hermes Agent tested 🫡🫡

Qwen3.6-27B with 50% less thinking tokens on average, and over 90% less in best cases with ThinkingCap!
I made an INT4 AutoRound quant tuned for a single RTX 5090: 2x262k ctx in vLLM, TQ4 KV cache, MTP on, Hermes Agent-tested. v2 w/ heavier calibration is next.
Shoutout to @bottlecapai and @jaroslavbeck, my friends and neighbors across the river in Prague!
Also: @UnslothAI, would love to see your quants too 👀
huggingface.co/josefprusa/Th…

BottleCapAI retweeted
Check, our new efficient ThinkingCap model series. Up to 10x token reduction. 2x on average. xitter.cf/jaroslavbeck/status/20…

BottleCapAI retweeted

This ThinkingCap-Qwen3.6-27B must be tested!
The only drawback of Qwen36-27B is that it thinks TOO MUCH, if this solves the problem it can become my main driver in local AI!

BottleCapAI retweeted

bottlecapai/ThinkingCap-Qwen3.6-27B
Capability of Qwen3.6-27B with 50% less thinking tokens on average, and over 90% less in best cases. Achieved via finetuning Qwen3.6-27B (Qwen Team, 2026) with state-of-the-art finetuning algorithms on a curated set of problems of various domains and difficulty