

Local AI. Building water cooled high end inference machines. Developing harnesses/agents for healthcare providers.
The Netherlands
Joined August 2025
- Tweets799
- Following274
- Followers786
- Likes5K




Pinned Tweet
I've been comparing two setups running Qwen3.5-397B-A17B at full 262K context:
🖥 Mac Studio M3 Ultra (512GB) — €14,500
⚙️ Custom workstation, 4× RTX PRO 6000 (384GB VRAM) — €45,000
Results:
• Workstation: 46.9 tok/s, 1,100W, 51 dBA
• Mac Studio: 35 tok/s, 120W, ~15 dBA
The Mac is 6.7× more energy-efficient per token. Over 3 years, the TCO gap is nearly €40K.
I have never been a Mac guy, but I have to admit that the Mac Studio is currently the most attractive hardware for running local AI agents.


Clément Pillette retweeted

Chairman @RepMoolenaar released the following statement in the wake of Jensen Huang's resignation from @NVIDIA:

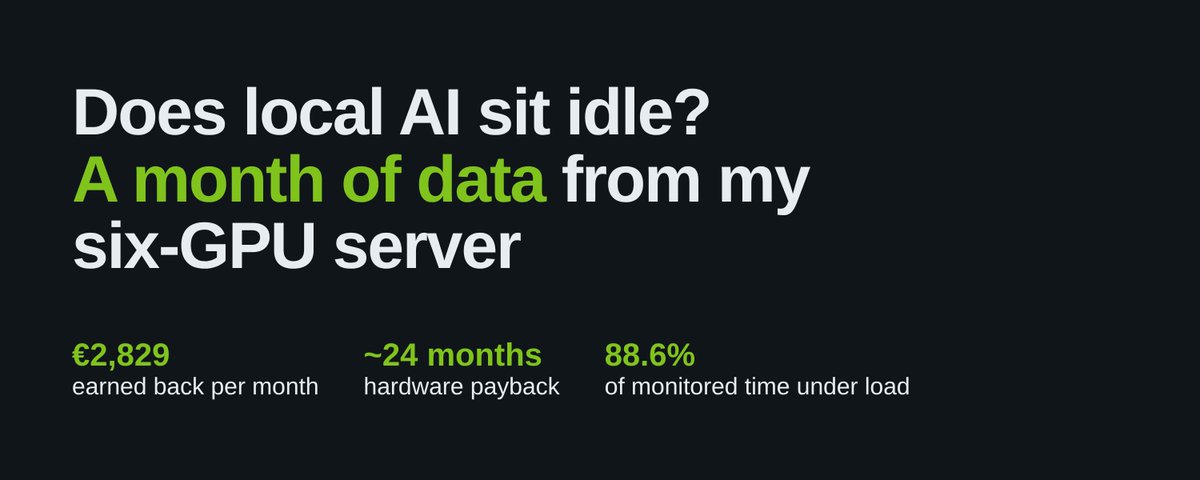
Does local AI sit idle? A month of data from my six-GPU server.
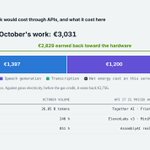
October, water-cooled: 26.85B tokens, 851 h transcribed, 248 h of speech generated.
Net energy cost: €202.
Same work through APIs matched for speed and quality: €3,031.
🧵

7/ Privacy: prompts, documents and transcripts never leave the building. No processor agreement, no transfer outside the EU, nothing that can end up in someone's training data.
For medical, legal and other confidential work, that often decides.
1
1
21

With the colder days coming, the 2 radiators are now inside and really effective to heat a whole house. I have converted the PWM cables into LAPP cables with M12 connectors: robust and not limited by the length


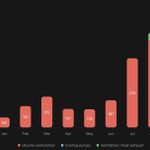
With 6 RTX6000 Pro, my WS consumed 757 kWh in September. Water cooling with an external heat exchanger is what unlocked 24/7 workloads because it kept the heat and noise away from my workspace. And that's also what enabled to plug them on the MB without exotic cables

I benchmarked a few agent harnesses on a job far from coding: the workflow a dental assistant runs during a consultation. 160 test consultations each, same model, same tools. @pidotdev came out best: the most accurate (99.6% of review criteria met) with the fewest tokens.

1
3
259
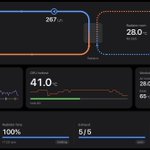
My cooling recipe is now optimum. I can run the 6 * RTX6000 Max-Q at full power (325W) continuously and I still have room to further cool the system if I want to. Max temp for GPU is 41°C, 70°C for the GPU. Already 3 months running this way, never had an issue.

Quantization can lead to some accuracy loss, but even a couple of points, can have a big impact. Here I benchmarked GLM5.3 Flash FP8 vs GLM5.3 TR3 4.0bpw. If someone could help me find out how to improve my recipe, it would be super appreciated @MiaAI_lab perhaps ?


Running 100% local with great results thanks to @Zai_org models and incredible agents from @FactoryAI . No need to wait for a reset from Tibo. 42dB despite being 1m away from my machine, temperature in the office is 22C.