

Articles that hit. Systems that work. I build AI tools, bots & lead gen weapons for individuals & small businesses. Code from the Shadows. 👻
Joined May 2015
- Tweets99.5K
- Following910
- Followers18.8K
- Likes40.6K





Your agent pays per byte.
Droid 1.0: model writes JS, sandbox, only stdout. 151 Linear issues: 2 requests, 61k tokens.
Same model both ways. Why shop for a new one?
Weights rented. Harness yours. articles.phantom-byte.com/pr…

The model was never the product. It was the marketing.
The real moat is the infrastructure around it: orchestration, memory, tools, permissions, state, and verification.
Models attract attention. Agent runtimes create value.
I agree. If people want to make this cost-effective, the best place to start is to figure out what you want to do with AI, then figure out what you need to pull it off.
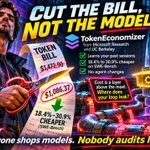
Cut the bill, not the model.
TokenEconomizer, from Microsoft Research and UC Berkeley, learns your past sessions. 18.4% to 30.9% cheaper on SWE-Bench, no agent changes.
Cost is a layer above the model. Where does your loop leak?
Everyone shops models. Nobody audits loops.

I love my Hermes agents. Between them and my Pi coding agents, I honestly couldn’t imagine going back to life without them.
They’ve become an essential part of how I work.
Specialist beat frontier by 11x.
Samaya's Sterling: 3B active params, 58.9% on FrontierFinance at $0.61 a question. Claude Fable 5.1: 55.9% at $6.89.
The right model beats the biggest. What would you scope a 3B model to?
Rented intelligence is a bill. Scoped is an asset.
Factories as a service.
Foundry Robotics raised $100M and runs a 130,000 sq ft autonomous assembly plant in Emeryville, shipping production in weeks, not months.
Retooling used to eat a year. What would you build if setup stopped being the gate?
Own the plant, own the clock.
The GPU was not slow.
Fused MoE kernel: Qwen3-30B-A3B 12.0 to 3.9 ms (3.11x). 235B backward 1.24x.
Overlap is not a constant. What is your idle fraction?
You did not buy compute. You bought waiting.
articles.phantom-byte.com/pr…

Distillation is a subsidy.
The information says DeepSeek V4.1-Flash 1017 and Kimi K3.1 Pro leaned on GPT-6 Astra output. OpenAI tied a July campaign to Moonshot.
Every answer trains the rival. If capability leaks at output, what is a moat worth?
You cannot distill a roadmap.

Google stopped sending the click. Reddit lost 1M+ referrals a week.
Shares fell 25% on strong earnings.
Alphabet ate $500B on the same mechanism.
The citation is not the visit. If AI Mode answered this for you, would the business survive? articles.phantom-byte.com/re…

Going “all in” on AI without proper architecture is a fool’s errand.
Without orchestration, context engineering, validation, and governance, you’re just scaling hallucinations and technical debt.
Architecture first. Scale last.
He wants your RAM.
Sam Altman called personal DRAM idle 95 percent of the time quite terrible, and wants maximum utilization in the cloud.
A business model, not physics. Where does your inference run?
They sell the meter. Builders keep the machine.
The open gap is three points.
Moonshot shipped Kimi K3.1 Pro: 1M context, 55 on Artificial Analysis, 65.7 percent on Terminal-Bench 4.0. Weights November 4.
Open weights sit 3 points from Claude, not 12. What do you run local first?
Rent the frontier. Own the floor.
A frozen-prompt test swapped one fact for an obsolete one. Qwen2.5 fell 100%->44.6%.
Retrieval worked. More context worsened: 45%->32%.
Date field?
More context = more attack surface. articles.phantom-byte.com/st…

Yep, I agree. AI can get work done at lightning speed, but it can cause damage just as quickly. That’s why a kill switch is essential.