


Pruna AI retweeted

A single photo can become a video of a talking avatar, complete with natural expressions and lip-syncing.
P-Video-2-Pro-Avatar also supports audio alone or speech from text, up to 3 minutes. It's interesting to create content without needing to re-record it.
The 50% launch discount is valid until November 5.
@PrunaAI

Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Pruna AI retweeted

I can't believe what they say on this talk show 👀
By P-Video-2-Pro-Avatar
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Pruna AI retweeted

You can now animate all pieces of art in seconds 🎭
We are super happy to release P-Video-2-Pro-Avatar, creating the highest-quality avatars at the highest speed.
Try it on the Pruna API here: dashboard.pruna.ai/login
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Pruna AI retweeted

P-Video-2-Pro-Avatar is live 🚀
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Pruna AI retweeted

One image. Two ways to bring it to life.
P-Video-2-Pro-Avatar is here!
Powered by MiniMax H3, delivering realistic expressions, natural motion, and accurate lip-sync from a single portrait.
Your image. Your voice. Your story.
This is where AI avatars get REAL.
@PrunaAI
🤖 Made with AI
Introducing P-Video-2-Pro-Avatar, based on @MiniMax_AI H3 !
Turn a single portrait into a realistic talking video with natural expressions and accurate lip sync.
And for launch, it's 50% off for the first two weeks, until November 5 at 18:00 CET!
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.02/s at 480p · $0.04/s at 768p
• 𝗦𝗽𝗲𝗲𝗱: ~0.97 s at 480p · ~2.2 s at 768p per second of output video
• 𝗜𝗻𝗽𝘂𝘁: One portrait with a text script or uploaded audio
• 𝗩𝗼𝗶𝗰𝗲𝘀: 30 voices across 10 languages
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 1s–3min at 24 fps, in 480p or 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: Voice delivery, scene motion, seed, and prompt upsampling
One image, two ways to bring it to life. Use your own audio or generate speech directly from text.
Available via our inference partners @replicate, @eachlabs, @Cloudflare, @scenario_gg, @wavespeed_ai, @WiroAI, Sociaro, @TellersAI, and @togethercompute.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 Try the model through the API or Playground: dashboard.pruna.ai/login
Pruna AI retweeted

One portrait and a voice is all it takes 🗣️
P-Video-2-Pro Avatar by @PrunaAI is now on each::labs, turning one photo into a talking video up to 3 minutes.
→ Your recording stays the voice and the lips follow it.
→ No audio? Send a script and pick from 30 voices.
Try it now ⤵
Pruna AI retweeted

Tough on the outside, sweet to the pit on the inside. 💀➡️💜
Created with @PrunaAI P-Video-2-Pro in @wavespeed_ai
@WaveSpeedCPP #WaveSpeedCPP
Prompt in comments 👇

Trying out the brand new @PrunaAI P-Video-2-Pro on @wavespeed_ai
"Pruna" means "plum" in Romanian, so I thought it would be funny to see what a plum-eating contest in a Japanese gameshow would look like 😅
@HiWscreator #WaveSpeedCPP
Prompt in the comments 👇
Pruna AI retweeted

We've been cooking 🍜 here's a preview of some of the new effects and features on @TellersAI featuring the just released p-video2-avatar-pro from @PrunaAI !

Pruna AI retweeted

p-video-2-pro-reference by @PrunaAI is now available on Design Arena!
Built on @MiniMax_AI H3, p-video-2-pro-reference combines image, video, and audio references to give creators greater control over video generation. It supports consistent characters, motion transfer, and multimodal inputs, with adjustable duration, aspect ratio, and first and last frames.
Congrats to the @PrunaAI team on the launch!

Introducing P-Video-2-Pro-Reference based on @MiniMax_AI H3! 🎬
Combine images, videos, and audio references to guide how your video looks, moves, and sounds. Keep characters consistent, transfer motion, and bring different visual elements together in a single generation.
• 𝗜𝗻𝗽𝘂𝘁: Text prompt with image and/or video references, plus optional audio
• 𝗥𝗲𝗳𝗲𝗿𝗲𝗻𝗰𝗲𝘀: Up to 9 images, 3 videos, and 3 audio files
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 5–15s at 480p or 768p
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: Output starting at $0.015/s in Cost mode, with reference inputs billed separately
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: First and last frames, seed, aspect ratio, and prompt upsampling
Two modes: Speed and Cost. Choose the trade-off that fits your workflow.
Available via our inference partners @Cloudflare, @scenario_gg, @replicate, @WiroAI, @TellersAI, @eachlabs, @wavespeed_ai, @inference_sh, @_segmind, @togethercompute, @EdenAIco, and @runware
Validated by our benchmark partners @datapointai, @RapidataAI, and @DesignArena
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 API: dashboard.pruna.ai/login
Pruna AI retweeted

@PrunaAI's P-Video-2 Pro now takes image, video, and audio references 📷
The same model, integration, now accepting references alongside your prompt to condition the generation.
- referenceImages, referenceVideos, referenceAudios
- Works alongside first and last frame control
- First audio input on P-Video-2 Pro
- 5-15s clips, up to 768p, with native audio
From $0.01/s with a 50% launch discount through October 29, on Runware.
Introducing P-Video-2-Pro-Reference based on @MiniMax_AI H3! 🎬
Combine images, videos, and audio references to guide how your video looks, moves, and sounds. Keep characters consistent, transfer motion, and bring different visual elements together in a single generation.
• 𝗜𝗻𝗽𝘂𝘁: Text prompt with image and/or video references, plus optional audio
• 𝗥𝗲𝗳𝗲𝗿𝗲𝗻𝗰𝗲𝘀: Up to 9 images, 3 videos, and 3 audio files
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 5–15s at 480p or 768p
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: Output starting at $0.015/s in Cost mode, with reference inputs billed separately
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: First and last frames, seed, aspect ratio, and prompt upsampling
Two modes: Speed and Cost. Choose the trade-off that fits your workflow.
Available via our inference partners @Cloudflare, @scenario_gg, @replicate, @WiroAI, @TellersAI, @eachlabs, @wavespeed_ai, @inference_sh, @_segmind, @togethercompute, @EdenAIco, and @runware
Validated by our benchmark partners @datapointai, @RapidataAI, and @DesignArena
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 API: dashboard.pruna.ai/login
Pruna AI retweeted
P-Video-2-Pro Reference by @PrunaAI is live on each::labs.
Lock a product, character or voice from your references and build a scene around it.
→ Use up to 9 images, 3 videos and 3 audio clips.
→ Get 5-15s clips with sound.
→ Keep your audio as the soundtrack.
Try it now ⤵
Pruna AI retweeted

Affordable, fast, and this time also with high control. Benchmark will be shared soon!
Introducing P-Video-2-Pro-Reference based on @MiniMax_AI H3! 🎬
Combine images, videos, and audio references to guide how your video looks, moves, and sounds. Keep characters consistent, transfer motion, and bring different visual elements together in a single generation.
• 𝗜𝗻𝗽𝘂𝘁: Text prompt with image and/or video references, plus optional audio
• 𝗥𝗲𝗳𝗲𝗿𝗲𝗻𝗰𝗲𝘀: Up to 9 images, 3 videos, and 3 audio files
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 5–15s at 480p or 768p
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: Output starting at $0.015/s in Cost mode, with reference inputs billed separately
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: First and last frames, seed, aspect ratio, and prompt upsampling
Two modes: Speed and Cost. Choose the trade-off that fits your workflow.
Available via our inference partners @Cloudflare, @scenario_gg, @replicate, @WiroAI, @TellersAI, @eachlabs, @wavespeed_ai, @inference_sh, @_segmind, @togethercompute, @EdenAIco, and @runware
Validated by our benchmark partners @datapointai, @RapidataAI, and @DesignArena
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 API: dashboard.pruna.ai/login
Pruna AI retweeted

P-Video-2 Pro Reference-to-Video is now LIVE on WaveSpeed AI!
Up to 9 images.
Up to 3 reference videos.
Up to 3 audio references.
Control the look, motion, and direction of every scene, all from your references.
Built with @PrunaAI 's P-Video-2 Pro.
Pruna AI retweeted

@PrunaAI 's image and video models are now on @EdenAIco : one key, one bill. All models here: edenai.co/providers/pruna

We’re excited to announce our partnership with @EdenAIco.
Pruna’s performance image and video models are now available through Eden AI. Together, we’re giving teams a simpler way to use fast, cost-efficient image and video generation in production.
Read the blog: pruna.ai/blog/pruna-ai-image…
Pruna AI retweeted
@PrunaAI just priced a second of AI video at $0.01/s
Cost mode on P-Video-2-Pro: same output quality as Speed mode, you trade generation time instead.
3 modes now: Cost, Speed and Quality, so the tradeoff is yours.
50% off until October 13.
→ app.edenai.run/playground

P-Video-2-Pro now has a Cost mode!
Get the same output quality as Speed mode, now starting from just $0.01/s. Optimised for cost when generation time matters less.
And for launch, it’s 50% off until October 13!
• 𝗜𝗻𝗽𝘂𝘁: Text or first-frame image, with optional last-frame conditioning
• 𝗗𝘂𝗿𝗮𝘁𝗶𝗼𝗻: 5–15s with generated audio
• 𝗣𝗿𝗶𝗰𝗶𝗻𝗴: $0.01/s at 480p · $0.025/s at 768p
• 𝗖𝗼𝗻𝘁𝗿𝗼𝗹: First + last frame, seed, aspect ratio, and prompt upsampling
Three modes: Cost, Speed, Quality. Pick the tradeoff that fits your workflow.
Available via our inference partners @Cloudflare, @Scenario_gg, @replicate, @wiroai, @TellersAI, @eachlabs, @edenaico, @runware, @wavespeed_ai, @inference_sh, @togethercompute, and @prodialabs.
Validated by our benchmark partners @datapointai, @RapidataAI, and @DesignArena.
📚 Model docs: docs.api.pruna.ai/guides/mod…
🧩 API: dashboard.pruna.ai/login
Pruna AI retweeted
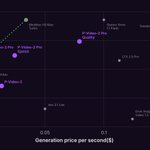
According to @datapointai, P-Video-2-Pro is really up there on the cost-quality Pareto frontier with the new cost mode!


