

Director, Research Unit for Precision Regenerative Medicine @HelmholtzMunich; Professor @LMU_Muenchen
München, Bayern
Joined September 2014
- Tweets2.9K
- Following1.6K
- Followers1.8K
- Likes4.3K




Herbert B Schiller retweeted
We believe voice is the most natural way to interact with intelligence, so we created Dessa, the most authentic full-duplex speech model ever built. Talking with it feels like talking with a person…full of emotion, nuance, pauses, and a natural cadence.
block.xyz/dessa

Herbert B Schiller retweeted
New from @arcinstitute: using the latent space representation of genomes from single-cell life to find new candidate functional RNAs.
I think this is cool because: (1) it uses deep learning and model interpretability to productive ends on a totally different kind of "knowledge"; (2) it shows how agents may be able to accelerate discovery in vast combinatoric spaces; and (3) it's an example of the synergy we'll hopefully see in the coming years between computational techniques and wet lab biology.

Delighted to share a landmark preprint from our lab, using genome language models and AI agents for biological discovery and genome mining!
The stretches of DNA between protein-coding genes are often called the genome’s “dark matter,” but they are far from empty. They encode RNA molecules that sense metabolites, regulate genes, and control some of molecular biology's most important tools (such as programmable genome editors e.g. CRISPR/bridge)
Much of this biology is unexplored. One reason is that RNAs can retain similar structures and functions even as their DNA sequences change dramatically, making their relationships difficult to recognize with conventional computational tools
Herbert B Schiller retweeted

We’re thrilled to share that Lamin is now generally available! With just a few clicks, anyone can create a database on lamin.ai
In 2022, we set out to build an open-source data management tool that’d make it easier to scale AI workflows in the life sciences. Over the past few years, we’ve served research labs and enterprises of all sizes with what used to take a dozen tools:
- Data lineage
- Format-agnostic lakehouse
- Notes, ELN, LIMS, ontologies
- Versioning, branching
- Data lake, catalog
- Agents, workflows, notebooks
- Feature store, MLOps
With Lamin, it’s just Postgres and storage in a Python package, plus an optional GitHub-like web platform.
Give it a try: pip install lamindb
Thanks to @_DimensionCap and @ycombinator and many others who made this possible
Herbert B Schiller retweeted

Discovery often comes from putting familiar pieces in unexpected ways: but bio space is too vast to do that effectively?
🤖 1000s of AI agents helped connect our whole-brain Perturb-seq atlas w literature. w @OpenAI @joyjiao12: more coming! See preprint biorxiv.org/content/10.64898…

GPT-Rosalind surfaced a new lead for drug discovery: could restoring cholesterol transport protect neurons from degeneration?
DCTN1 is a gene linked to Perry syndrome, a rare neurodegenerative disorder. In mouse-brain data, disrupting it increased expression of genes involved in making cholesterol. GPT-Rosalind suggested a possible explanation: cholesterol may not be reaching where neurons need it.
That gives scientists a specific mechanism to test and, if confirmed, a direction for developing new treatments for neurodegenerative disorders.
With @perturbai_tx and @scrippsresearch, a team of thousands of GPT-Rosalind agents worked in parallel, connecting gene-expression results from millions of mouse brain cells with scientific literature in just 32 minutes. We’re now expanding this collaboration to identify new drug targets.
openai.com/index/scaling-ai-…

Herbert B Schiller retweeted
Introducing Flint, @Recursive_SI’s first model: a fast local coding model built with our automated research system, the Eureka Machine.
• Best-in-class fast local coding
• Up to 2x faster than comparable models: 125+ tokens/sec on a MacBook Pro, 150+ on RTX Spark
• Built from scratch in under 4 months
Private, unmetered intelligence on your own machine. Open weights available now on @huggingface, run it locally on your favorite framework or try it for free on @opencode or @pidotdev.
Herbert B Schiller retweeted

summer @newlimit: we found our best age reprogramming payloads yet, hit more drug dev milestones than ever before, & welcomed new leaders to the team.
it's the most exciting time in our history & we hope you consider joining us.
highlights
- >2X increase in regenerative restoration in old hepatocytes
- +8 payloads restore endothelial function, +5 in hepatocytes
- >300X scale up of therapeutic manufacturing, 13X quality improvement
- 5X increase in sample efficiency for reprogramming AI


Herbert B Schiller retweeted

What does AI actually change for cancer research? 🤔
My personal answer in the opening keynote of the Nature Conference "Cancer Immunology in the AI Era" in Chongqing: science is a search. We search through an enormous space of possible interventions, mostly by hand and one experiment at a time. AI lets us search that space far more systematically.
Immunotherapy shows why this matters. It can cure cancer, yet only about 1 in 8 patients responds to checkpoint inhibitors. Finding the right intervention for each patient is exactly such a search problem. In my talk, "From cell atlases to AI-designed interventions," I showed how we approach it: map cell states eg the tumor immune ecosystem, predict how cells respond to perturbations, and steer cells toward the states we want.
I presented recent work from our lab and collaborators, from tumor atlases and a human cytokine dictionary to open benchmarks for perturbation models.
Many thanks to Zemin Zhang and the organizing team for a great program, and to Rong Li of Nature Biotechnology for chairing the session. And Chongqing at night, with its skyline above two rivers, is quite a sight. 🌃
#SingleCell #CancerImmunology #AI


Herbert B Schiller retweeted

Our Nature Medicine paper is out: menopause isn't a slow slope. Across 300M+ lab tests from 1M+ women, many body systems jump at the final menstrual period. Men show no such jump. 1/4
nature.com/articles/s41591-0…

Herbert B Schiller retweeted
🧪🧭 What if we could ask a model which experiment gives us the cells we want?
Our new preprint, LabCompass, takes a step in this direction through generative inverse design. For me, this is one of the most exciting directions for the field.
Together with many others, we have been working on predicting how cells respond to perturbations. How can we use these models to design experiments that achieve a desired biological outcome?
🎛️ This inverse problem is difficult. Combinations and doses create spaces that cannot be exhaustively screened, and each experiment produces a distribution of cell states. Predictive models are also imperfect, particularly in unexplored regions where we want to discover something new.
LabCompass couples a generative model of experimental designs with a forward model of cellular responses. The desired phenotype guides generation in continuous design space, while a learned prior favors plausible designs. Selected candidates are tested experimentally, and the measurements inform the next round.
💡 The method is not tied to a particular virtual cell model. It can work with different differentiable forward models and cellular readouts, and the same trained models can address different phenotypic objectives.
🩸 We demonstrated this in primary human blood stem and progenitor cells. Across the study, we profiled 78 million cells and experimentally validated conditions enriching megakaryocytic, erythroid, monocytic and early lymphoid populations.
One result I particularly like: distinct culture recipes produced similar target enrichments. Several solutions to the same biological objective give us alternatives to investigate and develop further.
🔬 The opportunity extends beyond blood and cell culture. We also applied LabCompass to single-cell transcriptomic data from viral infection. I’m excited to explore its potential for other perturbation systems, drug combinations, differentiation and organoids.
This raises a question for virtual cell models: alongside prediction accuracy, how effectively can they guide experiments toward desired biological outcomes?
If this connects to a problem you are working on, I’d love to hear from you. We’re keen to see how LabCompass transfers to new systems and happy to explore ideas together.
A wonderful collaboration with Bertie Göttgens and Nicola Wilson at the Cambridge Stem Cell Institute. Huge credit to joint first authors Licyel Paulas-Condori, Alessandro Palma, Lorenzo Consoli and Juan Antonio Rubio-Lara, and the whole team across both labs!
📄 Preprint: biorxiv.org/content/10.64898…
💻 Code: github.com/theislab/LabCompa…
#InverseDesign #VirtualCell #SingleCell
Herbert B Schiller retweeted

A universal predictive model of the cell would dramatically accelerate science, allowing biologists to perform experiments digitally. Today we’re announcing a major partnership with the DOE and NIH. The goal of this partnership is to generate the data that will be needed to build an accurate model of the cell with artificial intelligence.
Isomorphic, Google DeepMind, and Meta are joining us as founding partners in the Virtual Biology Initiative. This is the beginning of a large scale coordinated effort to map cellular biology to power the development of digital models of life. Other leading scientific institutions and consortia including the Allen Institute, Broad Institute, Gladstone Institutes, the Human Cell Atlas, the Human Protein Atlas, the Wellcome Sanger Institute, as well as NVIDIA, are working together as part of this international scientific project.
Creating a predictive model of the cell is one of the most important challenges for the next decade of science. The insights that come from this could unlock a far greater understanding of disease, and open new paths for cures.
We invite the worldwide scientific community and other funders to join us in this effort.
Herbert B Schiller retweeted

The "Single-cell foundation models don't work for perturbation prediction" narrative was a measurement problem.
Our new paper is out in @NatureBiotech : "Deep Learning Perturbation Models Can Outperform Baselines on Calibrated Metrics"
Last year, several papers concluded that deep learning perturbation models couldn't beat simple baselines, a finding that cast doubt on the entire Virtual Cell direction.
We asked a different question: can the metrics used in those comparisons reliably tell a good prediction from a bad one?
Often, they can't.
Common metrics like MSE and control-referenced Pearson Δ frequently rank uninformative baselines above positive controls. With calibrated alternatives (eg, WMSE, weighted R²Δ, NIR), deep learning models do outperform mean, control, and linear baselines.
The data matters too. Norman19 is approximately 96% additive, and models see less than 1% of possible gene combinations during training. The ceiling for beating an additive baseline is nearly zero, and the training signal for non-additive interactions is almost absent. Some dataset rankings aren't model rankings, but just noise!
To address this, we developed the Dynamic Range Fraction (DRF): a measure of metric calibration. Before trusting a model ranking, verify that your benchmark can detect a useful prediction at all.
The models aren't shiny toys. The field just needed better rulers.
Paper: nature.com/articles/s41587-0…
Code: github.com/shiftbioscience/P…
Huge congratulations to the first authors @Henrymiller2012 and Gabriel Mejia, and the team of Shift Bio!


Herbert B Schiller retweeted

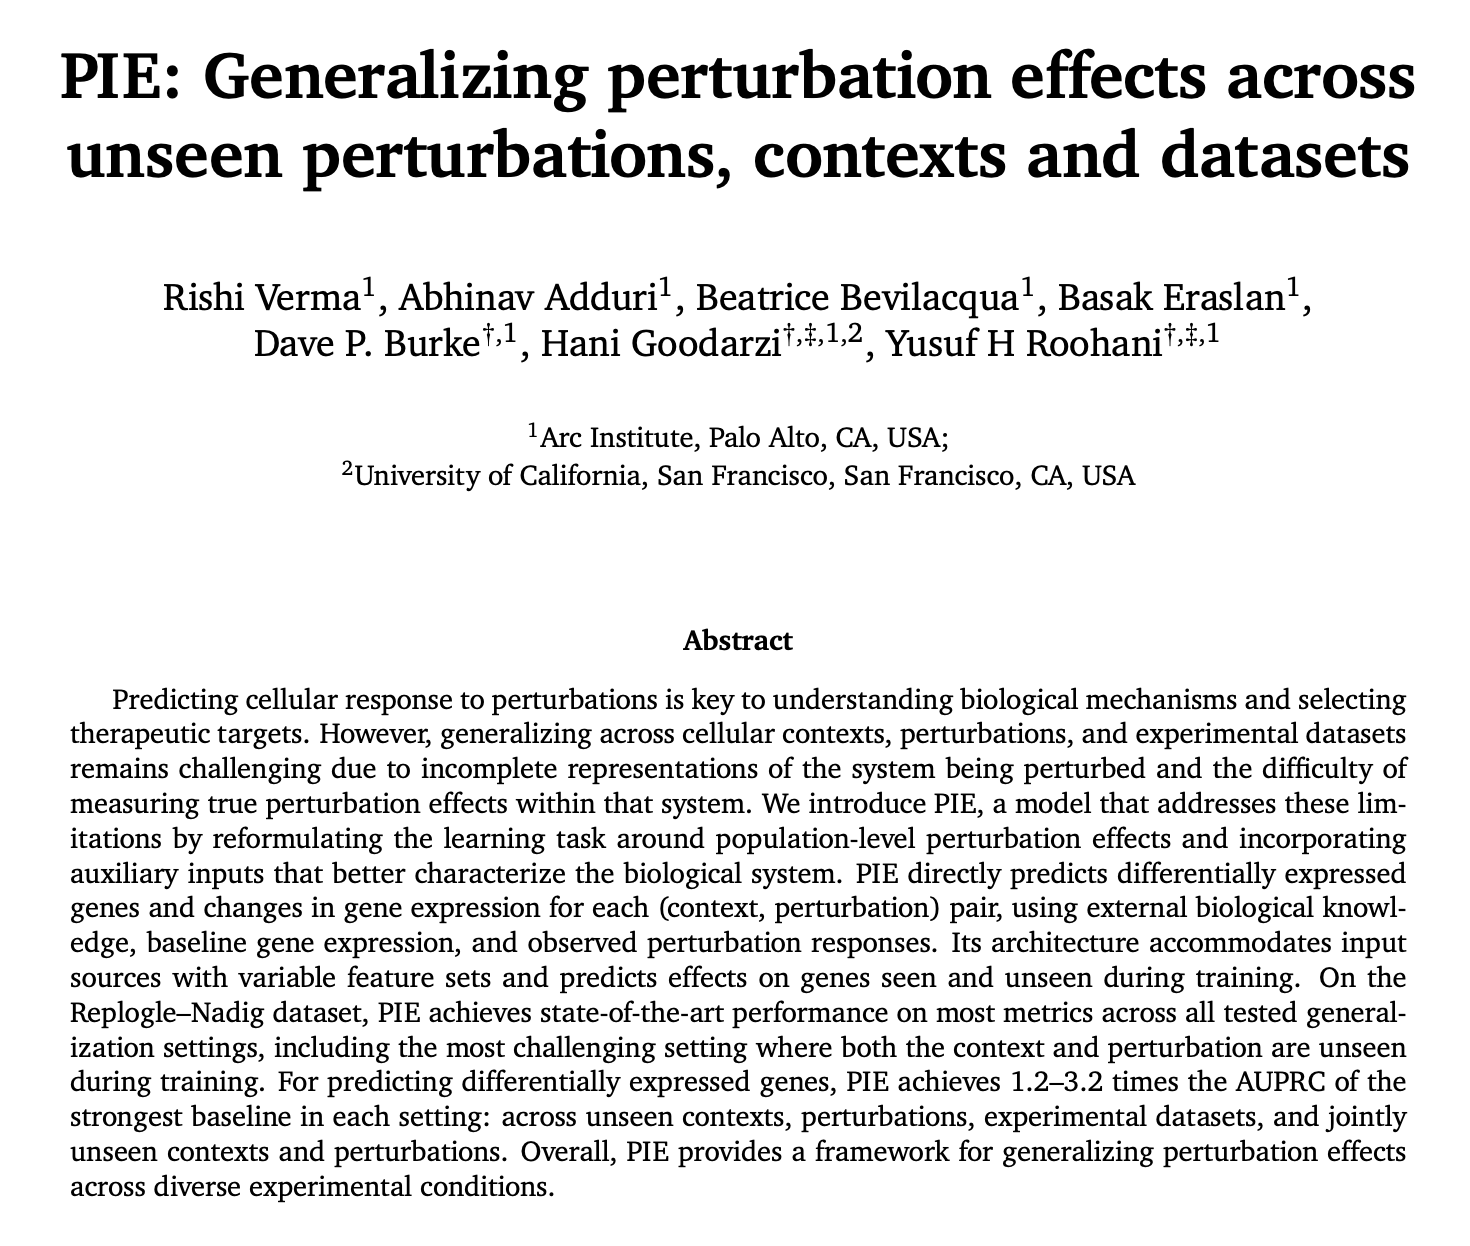
Most perturbation models learn only from experiments. Our new model, PIE, also draws on decades of curated biological knowledge to predict which genes respond to a perturbation, even in biological contexts and for perturbations it has never seen.
Herbert B Schiller retweeted

✨ Honored to step into the role of Vice Co-Chair of the Human Cell Atlas ✨ Working together with our new co-chairs Chloé Villani and Muzz Haniffa, alongside my fellow Vice Co-Chair Shyam Prabhakar.
I can’t imagine a better next leadership team for the @humancellatlas. Beyond their strong track record, it’s a pleasure to work with such thoughtful and collaborative colleagues. This is a particularly meaningful moment for me, having been part of the HCA journey for almost a decade. I have had the privilege of co-chairing the HCA Technology Working Group and Industry Partnership Program, and more recently serving on the HCA 2.0 Task Force, helping shape the vision and strategy for this next phase.
As we move towards HCA 2.0, we are defining the future vision and roadmap for the next generation of the Human Cell Atlas #HCANext10. In my new role, I will specifically focus on leading the HCA technology roadmap, working closely with our technology community as well as biotech and pharma partners to integrate the latest single-cell and spatial technologies into the HCA roadmap. I’m very grateful to the HCA community for the trust. Excited for the next chapter of the Human Cell Atlas and for what we can build together.
@sangerinstitute @broadinstitute @ASTARsg @cnag_eu

Herbert B Schiller retweeted

FDA confirmed aging will be on its regulatory science agenda. ARPA-H has $144M building the endpoint framework. #ARDD2026 at Harvard was where that plan took shape. geneonline.com/ardd-2026-can…

Herbert B Schiller retweeted
Day 2 of #ARDD2026: Novartis Biomedical Research President Fiona Marshall on aging as the common driver across all major therapeutic areas — not a niche, a framework. agingpharma.org/program2026

Herbert B Schiller retweeted

Summary of exec panel at ARDD
Fiona Marshall: Novartis cares about aging mechanisms (DARE group) but diseases not lifespan.
Ariel Feldstein: Pfizer wants to treat multimorbidity axes - CVD, neuro.
Stephane Bancel: Take more vaccines 🙃
Elcin Ergun: GenAI most important new thing in pharma (strong disagree, not the bottleneck)
Christoph Weber disagrees: We're gonna have so many molecules, trials is the challenge.
Some mention of Chinese efficiency in trials and hospitals. Too many lawyers in US.
Core challenges:
Prevention trials take too long. The FDA panel comments are relevant here...
When you don't have obvious endpoint like obesity, you really need strong endpoints.
Feldstein wants more deep phenotyping from trials, to make biomarkers. More resistance from hospitals to working with them, and less US support for research.
Marshall emphasizes lot of data out in the world, UK is rich.
My take:
Getting there on pharma engagement. If we get the medicines that treat multimorbidity we'll live longer, whether lifespan is the goal or not.

Highly positive panel on longevity trials at ARDD:
Lowell Zeta (chief of staff) says longevity is a priority for the current FDA.
There's now a point person for longevity trial design: Justin Penzenstadler (reviewer on GLP1s).
Steven Kozlowski (chief scientist) working on guidance and tech specs, to be released first half of next year.
Justin recommends the field forma precompetitive consortium for which biomarkers, how to include in trials. And to talk to regulators regularly.

Herbert B Schiller retweeted

🎉 We warmly congratulate @MedUni_Wien and AKH Wien on opening two groundbreaking research facilities: the Center for Translational Medicine and the Eric Kandel Institute – Center for Precision Medicine.
Exciting times ahead for translational research in #Vienna!
Herbert B Schiller retweeted

ARPA-H is now running clinical trial reform? Is it Christmas already? 🚀
Congrats! @BrackLab @DrAliciaJackson @MarkHamalainen

Herbert B Schiller retweeted

Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
Readers added context they thought people might want to know
The 48% figure and "video Turing test" claim are from Tavus's own study of 54 one-minute calls, not independently verified or using a standard protocol. Griffin-Lite leads NVIDIA's VideoFDB benchmark on their public leaderboard.
cellcog.ai/blog/tavus-gri…
research.nvidia.com/labs/amri/proj…
tech-ish.com/2026/10/02/tav…
Herbert B Schiller retweeted

Excited to share ArchMap, now out in @NatureGenet 🧬
The Human Cell Atlas is building a reference map of every cell in the human body, much as the Human Genome Project gave us a reference for DNA. The real power of a reference is that every new dataset can be read against it, to see what's familiar and what's new.
ArchMap makes that possible for everyone. It's a free, no-code platform where any lab can map its single-cell data onto Human Cell Atlas references, all in the browser.
Built on scArches, ArchMap combines reference mapping, cell-type annotation, uncertainty estimates and collaborative exploration in a single workflow. What excites me most is seeing where new data departs from the reference. In a pulmonary fibrosis example, annotation uncertainty followed by gene-expression analysis points directly to disease-associated cell states.
Huge thanks to Chelsea Bright, Ronald Skorobogat, @MDLuecken , @fabian_theis
Try it: archmap.bio/#/
Paper: doi.org/10.1038/s41588-026-0…
#HumanCellAtlas #SingleCell