
Multilingualilty Lead @cohere. Formerly: PhD @jhuclsp, Alexa Fellow @amazon, dev @Google, MPhil @cambridgenlp, EdM @hgse 🔑🔑¬🧀 (@kelvenmar20)
Connecticut, USA
Joined June 2019
- Tweets708
- Following668
- Followers2.4K
- Likes2.8K





Behind-the-scenes of North Small Translate! 🌐

We recently introduced North Small Translate, a new state-of-the-art open machine translation model.
We want to be open with our weights and processes. Watch Tom Kocmi, Cohere's head of localization, explain the model, which is the best in the world under 1T parameters: (1/6)
15
1,283
Omg. First day *really* agentic coding. This me rn 🤺⚔️
xkcd.com/303/

1
6
326
Kelly Marchisio @NeurIPS retweeted

👉 slator.com/generic-reasoning…
While reasoning-enabled #LLMs are among the strongest 🔝 performers in #AI #translation benchmarks, a new study suggests that prompting them to explain their reasoning before translating can hurt translation quality.
@rajaee_sara @mziizm @cheeesio @Cohere_Labs @UvA_Amsterdam @cohere #xl8 #t9n

“What language is this text written in?” - a question so easy to pose, yet surprisingly difficult to answer!

Announcing our latest paper: CommonLID: Re-evaluating State-of-the-Art Language Identification Performance on Web Data
In collaboration with @CommonCrawl @MLCommons and @JohnsHopkins we worked with 80+ native speaker annotators to build a LID benchmark on actual Common Crawl text covering 109 languages. Existing evaluations overestimate how well LangID works on web data.
Kelly Marchisio @NeurIPS retweeted

🌟🚀Sparse Attention Models Can Get Sparser
We've updated The Sparse Frontier—the largest empirical analysis of training-free sparse attention to date—from Qwen 2.5 to 3 model families, now including Llama 3.1 and Gemma 3.
Key findings:
📊 Larger sparse models outperform smaller dense ones at equal compute cost. Only high-sparsity configs lie on the Pareto frontier for long sequences.
🔬 Already sparse? You can go sparser. Gemma 3 has 5/6 layers as Sliding Window Attention by design—yet additional sparsification of the remaining dense layers still yields efficiency gains at scale.
📈 Longer sequences tolerate higher sparsity. From 9 models × 6 methods × 9 tasks: fixed-budget methods in production are suboptimal. Token budget should grow sublinearly with context length.
Co-authors: Robert Li, Renjie Huang, @seb_ruder, @cheeesio, @PontiEdoardo.
Special shout-out to @faridlazuarda who updated our repo to vLLM v1 and made Gemma3 evaluations possible.
Links in the comments ⬇️


🚀🚨 Sparse-Frontier Major Updates!
You can now evaluate Reasoning + Sparse models at speed, with Sparse-Frontier upgraded to the @vllm_project's v1 engine🔥
We still provide support for Tensor Parallelism and the original sparse attention baselines, but it now works cleanly with newer models, decoding strategies, and evaluation setups. Task coverage and model support were also expanded as part of this release.
The config-based workflow stays the same. If you’re working on sparse decoding, reasoning models, or long-context evaluation, this update makes it easier to run consistent experiments across models, tasks, and attention methods⚡️
Really enjoyed working with @p_nawrot and @PontiEdoardo over the past months to get this release out!

Our Multilingual Team at @cohere is hiring interns!
If you are a current PhD student working in multilinguality and would like to work with our team, please apply below, reach out! 🌍🌏🌎
(The below says “Winter”, but we hire year-round)
jobs.ashbyhq.com/cohere/6e85…
Three emails in the past ~week addressed to “Emma”. This can’t be a coincidence — hive-mind, what is this?
1
332
Kelly Marchisio @NeurIPS retweeted

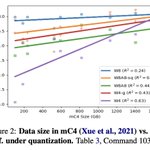
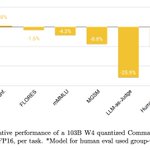
Our pick of the week by @dhairya_su47605: "How Does #Quantization Affect #Multilingual #LLMs?" by @cheeesio, @TheyCallMeMr_, Hongyu Chen, @d_aumiller, @ahmetustun89, @sarahookr, @seb_ruder (Findings EMNLP, 2024)

Pick of the week @fbk_mt: How Does Quantization Affect Multilingual LLMs?
Quantization has become a widely adopted technique for model compression. This work investigates the impact of quantization on different languages in multilingual LLMs.
aclanthology.org/2024.findin…
Kelly Marchisio @NeurIPS retweeted

Pick of the week @fbk_mt: How Does Quantization Affect Multilingual LLMs?
Quantization has become a widely adopted technique for model compression. This work investigates the impact of quantization on different languages in multilingual LLMs.
aclanthology.org/2024.findin…
Announcing - Moms Who ML! 🐣🍼
I landed in San Diego to a video call from my 15-month-old -- she licked the camera then put me in this bag of Mega Bloks👅
If you can relate, let's support one another!
Search for the group on the #NeurIPS2025 app, and we'll expand after!

14
956
Looking forward to #neurips2025 next week! Come say hi at the @cohere booth!
2
31
4,204


Kelly Marchisio @NeurIPS retweeted

I am hiring highly skilled performance engineers for my team! You will be working on optimising pretraining for models >100B params on O(1000s) of GPUs, and hardware-aligned architecture design. We are cooking a lot of very exciting projects and I can safely say you will have a lot of fun! Link in thread. <3
Big thanks to @slatornews for hosting me at #SlatorCon Silicon Valley last month. I loved giving attendees an inside look into how SOTA multilingual LLMs are built 🤖🌍

Kelly Marchisio, Multilingual Team Lead at @cohere, shared an inside look at building 🧑💻 a #multilingual #LLM and advancing #AI #translation at #SlatorCon Silicon Valley 2025.
#Cohere #LLMs #xl8 #t9n @cheeesio
slator.com/how-to-build-mult…

1
512
I had a great time speaking at #SlatorConSV25 today!
The future of multilingual AI 🚀 is here. At #SlatorConSV25, @cohere's @cheeesio explains how to build massively multilingual LLMs, from technical foundations to the current landscape and what comes next.
#MultilingualAI #LLMs #CommandA

16
892
Kelly Marchisio @NeurIPS retweeted

Where machine translation goes, AI goes. This has been true since 1954 (MT made front-page of NYT, 2 years before the Dartmouth workshop)
We just released the best translation model ever


Kelly Marchisio @NeurIPS retweeted

@weiyinko_ml was one of the earliest members of our Open Science Community and an early collaborator on our open science research.
We’re proud to have been part of Wei-Yin’s journey from community collaborator to colleague, and grateful he took an early bet on working with us 🚀
Wow. Coding with GenAI continues to impress, but highlights the need for strong knowledge of the code *without* help.
I opened up a once-familiar codebase, but one I haven’t looked at seriously in a year. Instead of hours spent re-familiarizing, I asked an LLM, (1/2)