
Multilingualilty Lead @cohere. Formerly: PhD @jhuclsp, Alexa Fellow @amazon, dev @Google, MPhil @cambridgenlp, EdM @hgse 🔑🔑¬🧀 (@kelvenmar20)
Connecticut, USA
Joined June 2019
- Tweets708
- Following668
- Followers2.4K
- Likes2.8K





Kelly Marchisio @NeurIPS retweeted

👉 slator.com/generic-reasoning…
While reasoning-enabled #LLMs are among the strongest 🔝 performers in #AI #translation benchmarks, a new study suggests that prompting them to explain their reasoning before translating can hurt translation quality.
@rajaee_sara @mziizm @cheeesio @Cohere_Labs @UvA_Amsterdam @cohere #xl8 #t9n

Kelly Marchisio @NeurIPS retweeted

🌟🚀Sparse Attention Models Can Get Sparser
We've updated The Sparse Frontier—the largest empirical analysis of training-free sparse attention to date—from Qwen 2.5 to 3 model families, now including Llama 3.1 and Gemma 3.
Key findings:
📊 Larger sparse models outperform smaller dense ones at equal compute cost. Only high-sparsity configs lie on the Pareto frontier for long sequences.
🔬 Already sparse? You can go sparser. Gemma 3 has 5/6 layers as Sliding Window Attention by design—yet additional sparsification of the remaining dense layers still yields efficiency gains at scale.
📈 Longer sequences tolerate higher sparsity. From 9 models × 6 methods × 9 tasks: fixed-budget methods in production are suboptimal. Token budget should grow sublinearly with context length.
Co-authors: Robert Li, Renjie Huang, @seb_ruder, @cheeesio, @PontiEdoardo.
Special shout-out to @faridlazuarda who updated our repo to vLLM v1 and made Gemma3 evaluations possible.
Links in the comments ⬇️


🚀🚨 Sparse-Frontier Major Updates!
You can now evaluate Reasoning + Sparse models at speed, with Sparse-Frontier upgraded to the @vllm_project's v1 engine🔥
We still provide support for Tensor Parallelism and the original sparse attention baselines, but it now works cleanly with newer models, decoding strategies, and evaluation setups. Task coverage and model support were also expanded as part of this release.
The config-based workflow stays the same. If you’re working on sparse decoding, reasoning models, or long-context evaluation, this update makes it easier to run consistent experiments across models, tasks, and attention methods⚡️
Really enjoyed working with @p_nawrot and @PontiEdoardo over the past months to get this release out!

Kelly Marchisio @NeurIPS retweeted

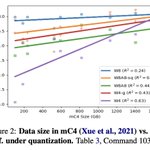
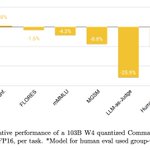
Our pick of the week by @dhairya_su47605: "How Does #Quantization Affect #Multilingual #LLMs?" by @cheeesio, @TheyCallMeMr_, Hongyu Chen, @d_aumiller, @ahmetustun89, @sarahookr, @seb_ruder (Findings EMNLP, 2024)

Pick of the week @fbk_mt: How Does Quantization Affect Multilingual LLMs?
Quantization has become a widely adopted technique for model compression. This work investigates the impact of quantization on different languages in multilingual LLMs.
aclanthology.org/2024.findin…
Kelly Marchisio @NeurIPS retweeted

Pick of the week @fbk_mt: How Does Quantization Affect Multilingual LLMs?
Quantization has become a widely adopted technique for model compression. This work investigates the impact of quantization on different languages in multilingual LLMs.
aclanthology.org/2024.findin…


Kelly Marchisio @NeurIPS retweeted

I am hiring highly skilled performance engineers for my team! You will be working on optimising pretraining for models >100B params on O(1000s) of GPUs, and hardware-aligned architecture design. We are cooking a lot of very exciting projects and I can safely say you will have a lot of fun! Link in thread. <3
Kelly Marchisio @NeurIPS retweeted

Where machine translation goes, AI goes. This has been true since 1954 (MT made front-page of NYT, 2 years before the Dartmouth workshop)
We just released the best translation model ever


Kelly Marchisio @NeurIPS retweeted

@weiyinko_ml was one of the earliest members of our Open Science Community and an early collaborator on our open science research.
We’re proud to have been part of Wei-Yin’s journey from community collaborator to colleague, and grateful he took an early bet on working with us 🚀
Kelly Marchisio @NeurIPS retweeted
Excited to announce the call for papers for the Multilingual Representation Learning workshop #EMNLP2025 sigtyp.github.io/ws2025-mrl.…
with @_dataman_ @linguist_cat Jiayi Wang @fdschmidt @tylerachang @hila_gonen
and amazing speakers: Alice Oh, Kelly Marchisio, & Pontus Stenetorp


Kelly Marchisio @NeurIPS retweeted

We're looking for a new member for the multilingual team with a focus on data engineering! Please apply at the link below:

The Multilingual Team at @cohere is hiring!
If this sounds like you, please apply:
- strong coding skills and a keen eye for detail
- experience working with the challenges & joys of multilingual data
Help us bring AI to the world! 🌏🌍🌎
jobs.ashbyhq.com/cohere/a87b…
Kelly Marchisio @NeurIPS retweeted
Make Command speak better & in more languages
The Multilingual Team at @cohere is hiring!
If this sounds like you, please apply:
- strong coding skills and a keen eye for detail
- experience working with the challenges & joys of multilingual data
Help us bring AI to the world! 🌏🌍🌎
jobs.ashbyhq.com/cohere/a87b…
Kelly Marchisio @NeurIPS retweeted

🚀 By *learning* to compress the KV cache in Transformer LLMs, we can generate more tokens for the same compute budget.
This unlocks *inference-time hyper-scaling*
For the same runtime or memory load, we can boost LLM accuracy by pushing reasoning even further!

Kelly Marchisio @NeurIPS retweeted
Here are key recommendations to make AI safer & more equitable for everyone:
🌐 Incentivize the creation of open-access multilingual datasets
🪟 Encourage transparency in model language coverage
🔬 Prioritise resources towards multilingual research

Kelly Marchisio @NeurIPS retweeted
Over 7000 languages are spoken worldwide 🌐, but AI safety efforts focus on only a fraction of them.
Our latest paper draws on our multi-year efforts with the wider research community to explore why this matters and how we can bridge the AI language gap.

Kelly Marchisio @NeurIPS retweeted
Our ML Efficiency group is looking forward to welcoming @p_nawrot next week on May 28th, for a session on "The Sparse Frontier: Sparse Attention Trade-offs in Transformer LLMs"
Learn more: cohere.com/events/Cohere-Lab…

Kelly Marchisio @NeurIPS retweeted

The Sparse Frontier
Efficient sparse attention methods are key to scale LLMs to long contexts. We conduct the largest-scale empirical analysis that answers:
1. 🤏🔍 Are small dense models or large sparse models better?
2. ♾️What is the maximum permissible sparsity per task?
3. 🥇Is there a single best sparse attention method?
4. 📈 Are there generalizable scaling laws for sparse attention?



Kelly Marchisio @NeurIPS retweeted

The Sparse Frontier: Sparse Attention Trade-offs in Transformer LLMs
New benchmark from Cohere compares training-free sparse attention across:
- 7B → 72B models
- 16K → 128K tokens
- up to 95% sparsity
Findings:
- larger, sparser models outperform smaller dense ones on long sequences (isoFLOPS frontier)
- decoding handles higher sparsity—big models survive 20× compression
- no single method dominates—performance depends on task and inference phase
- introduces scaling laws which predict sparse performance from model size, sequence length, and compression ratio
𝑠𝑚𝑎𝑟𝑡 𝑠𝑝𝑎𝑟𝑠𝑖𝑡𝑦 𝑠𝑐𝑎𝑙𝑒𝑠
𝑑𝑢𝑚𝑏 𝑡𝑜𝑘𝑒𝑛𝑠 𝑑𝑜𝑛’𝑡

Kelly Marchisio @NeurIPS retweeted

The Sparse Frontier
Explores the efficiency-accuracy trade-offs of sparse attention in Transformer LLMs.
Findings:
- Efficiency trade-off: For very long sequences, big models with high, sparse attention outperform smaller, dense ones.
- Phase sensitivity: Decoding can tolerate greater sparsity, especially in larger models, than prefilling while still keeping accuracy.
- No one-size-fits-all: Sparsification strategies vary by task and phase; even modest sparsity can hurt at least one benchmark.
- Generalization: Newly derived scaling laws for sparse attention back up these trends beyond the tested settings.

Kelly Marchisio @NeurIPS retweeted

I'm excited to the tech report for our @Cohere @CohereForAI Command A and Command R7B models. We highlight our novel approach to model training including the use of self-refinement algorithms and model merging techniques at scale. Command A is an efficient, agent-optimised multilingual model offering best-in-class capabilities. Read more below! ⬇️
