
Quantization and low-precision training for LLMs @Cornell_Bowers @togethercompute
SF
Joined May 2019
- Tweets43
- Following2.9K
- Followers243
- Likes1.4K




Vincent Counathe retweeted

Introducing NyoomFloat12, a hardware-friendly lossless 12-bit quant from BF16 (accepted to #neurips2026)!
In BF16 LLMs four of the bits that are the same for 99.7% of the weights. So you can compress BF16 -> 12-bit with minimal overhead.
Check out @__sylvie_l__'s thread! 1/

Lossless weight compression has saved LLMs GPU memory, but not time. Decoding costs more than it saves.
NyoomFloat12 (NF12) is a lossless 12-bit BF16 format with decode cheap enough to speed up inference. Qwen3-32B: 1.23× faster token generation, up to 2.54× rollout throughput🧵

ALT Three panels. (a) Per-bit entropy of BF16 weights in Llama-3.2-1B: exponent bits E7–E4 near zero, every other bit near 1. (b) The high bytes of two BF16 weights packed into one NF12 meta byte. (c) Rollout throughput against concurrency on Qwen3-32B: NF12 peaks at 787 tok/s, DFloat11 at 357, BF16 at 310.


Vincent Counathe retweeted

Tinker's new StableReinforce objective is Reinforce + Score Centering. Here's how I reverse-engineered it 🧵

Off-policy RL is difficult; runs can suddenly collapse because of async RL staleness or numerical mismatch.
StableReinforce is a new method on Tinker that keeps your RL runs stable, even when learning drifts from sampling.
tinker-docs.thinkingmachines…
Really nice findings by Hayden

Rumor has it frontier labs are using looped LMs to scale quality without scaling parameters. But KV-cache memory still grows with every loop. Is that necessary?
No! Our method BeNice! unlocks near-lossless sharing of the final KV-cache across loops: more depth, same KV memory.
This lossless KV-sharing isn’t guaranteed out of the box with looped models. 👀👇for our method BeNice! to teach your model that sharing is caring!

Vincent Counathe retweeted
If you're working on camera-controllable video models (recammaster, gen3c, etc.), I believe you'll be extremely interested in trying out our neurips spotlight (1 out of 33) benchmark!

Excited to share our #NeurIPS2026 E&D 🏆 Spotlight!
We all agree that memory is essential for modeling a persistent 4D world.
But: 🙋 Can 4D Foundation Models Remember?
Introducing 🔥 PersistBench: a benchmark for testing visual memory in camera-controllable video models / 4D reconstruction models / video-to-360° models.
One key challenge in evaluating visual memory is obtaining real-world ground truth for what happens to an object after it leaves the camera’s view.
In PersistBench, we introduce a simple way to sidestep this challenge. 🤫
🌐 Project Page: guangzhaohe.com/persistbench…
🏆 Leaderboard: huggingface.co/spaces/therea…
🐙 GitHub: github.com/guangzhaohe/Persi…
🤗 Dataset: huggingface.co/datasets/ther…
See how well your models do and submit to our leaderboard today!
🧵 [1/n]
Vincent Counathe retweeted
Why is RL so sensitive to training-inference mismatch (TIM)?
With each training step, the trainer is pulled toward the sampler, resulting in accumulating drift.
We exploit this intuition to devise a novel correction method to stabilize RL under TIM, called Score Centering.
Vincent Counathe retweeted

Coolest QAT work I have seen this year.
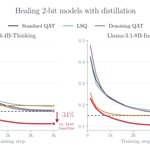
Traditional QAT suffers from a mismatch between the high-precision weights being updated and their low-bit reconstructions used to compute gradients. QUASAR tackles this issue with a simple modification to the weight reconstruction map, achieving lower training loss at 2–4 bits without adding any inference overhead.
A neat idea! Curious to see how well it scales to larger LLMs.

While QAT helps improve model quality at 2-4 bits, it has a structural optimization problem. Indeed, at every step, the high-precision latent weights receive the gradient updates, but the loss and gradients are computed on their low-bit reconstructions, i.e. the weights the model will use at inference.
This mismatch results in suboptimal training dynamics and a higher loss floor. The main existing QAT methods (learning the scales alongside model parameters, soft-to-hard rounding, or better initialization) do not directly address this mismatch.
With QUASAR, we introduce a simple and computationally cheap way to address the mismatch. QUASAR consistently achieves lower loss than all QAT baselines and adds no inference overhead. Also, it can be combined with most other QAT methods, since it only changes the weight reconstruction map in the fwd pass.
Vincent Counathe retweeted

⌘C ⌘V: Introducing Copy-Paste Language Models!
CPLMs learn to copy tokens better, improving downstream accuracy, CoT, long-context performance, and memory-efficiency for RAG at <3% overhead
PS: they (partially) mitigate the LM head bottleneck
Paper: arxiv.org/abs/2610.19247

Vincent Counathe retweeted

While exploring diffusion language models (DLMs), we kept asking ourselves: given speculative decoding, a lossless acceleration technique, why do we still need DLMs? 🤔 Our latest work, ORL, tries to answer this question: AR optimizes intelligence 👆, speculative decoding optimizes speed 👉, and DLMs optimize the Pareto frontier of speed and intelligence 🚀. Through co-design across the algorithms, the training and inference engine, and the kernels, ORL pushes out a new Pareto frontier of intelligence and speed. Similar performance, much faster than speculative decoding. You say lossy spec? ORL-DLM is better too! 😎
🌐 Project + live demos: introspective-diffusion.gith…
Vincent Counathe retweeted

great work on demystifying the dark arts of quantization aware training!
While QAT helps improve model quality at 2-4 bits, it has a structural optimization problem. Indeed, at every step, the high-precision latent weights receive the gradient updates, but the loss and gradients are computed on their low-bit reconstructions, i.e. the weights the model will use at inference.
This mismatch results in suboptimal training dynamics and a higher loss floor. The main existing QAT methods (learning the scales alongside model parameters, soft-to-hard rounding, or better initialization) do not directly address this mismatch.
With QUASAR, we introduce a simple and computationally cheap way to address the mismatch. QUASAR consistently achieves lower loss than all QAT baselines and adds no inference overhead. Also, it can be combined with most other QAT methods, since it only changes the weight reconstruction map in the fwd pass.
4-bit checkpoints trained with QUASAR for Qwen3.5-4B, Qwen3.8-27B, Gemma 4 E4B and 12B, and Muse-Glimmer-30B:
Qwen: huggingface.co/collections/Q…
Gemma: huggingface.co/collections/Q…
Muse: huggingface.co/collections/Q…

