

RTX PRO 6000 96GB GPU cloud for AI inference, fine-tuning & rendering. OpenAI-compatible APIs. ↓
Delaware, USA
Joined July 2026
- Tweets205
- Following70
- Followers303
- Likes133





RTX PRO 6000 GPU rental. 96GB VRAM, from $1.89/GPU-hour, per-second billing. $1 free credit.
ecohash.com/gpu/rtx-pro-6000…

Rent an RTX PRO 6000. 96GB VRAM, from $1.89/GPU-hour. $1 free credit.
ecohash.com/gpu/rtx-pro-6000…

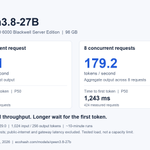
BF16, vLLM 0.29.0. 1,024 input / 256 output tokens; ~10-minute runs.
Local synthetic tests; internet/gateway latency excluded. Concurrency 8 is a tested load, not a capacity limit.
ecohash.com/models/qwen3.8-2…
Qwen3.8-27B on one RTX PRO 6000:
1 request: 26.1 output tok/s; 162 ms to first token.
8 concurrent: 179.2 aggregate tok/s; 1.24 s to first token.
Both latencies are P50. Higher throughput comes with a longer wait.
Test conditions + results below.

Launch an 8-GPU RTX PRO 6000 instance on EcoHash.
8 x 96 GB VRAM and a whole node for your workload. Watch the console walkthrough with narration: containers, SSH, HTTP access, and persistent storage.
Full guide: ecohash.com/blog/launch-eigh…
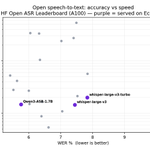
1.7B parameters. 3.28% WER. 360x real-time.
Qwen3-ASR-1.7B is the smallest of the three speech-to-text models we serve, and it beats the other two on both accuracy and throughput. Measured end-to-end on EcoHash (RTX Pro 6000).
Same endpoint, $0.05 per 1M input tokens.

Trace collection like this is usually the missing piece once an agent loop starts failing in ways a single log line can't explain. Curious how much overhead NeMo Relay adds per call once tracing stays on by default instead of only during debugging.
Running a decision model locally for routing and triage is the right instinct, a full LLM call for a yes or no question wastes most of its own capacity. The real test is whether response time stays flat once a few hundred of these fire per second on the same box.
Worth checking what that cost per task number actually covers, a single turn or the average across a full multi-step run. Agent benchmarks that report per-task cost without saying how many tool calls got bundled into one task are easy to misread.
Going from a 64K to a 1M output ceiling changes what kind of job you'd even attempt with this model, a single long document instead of chaining several calls together. Curious what decode latency looks like once a request actually pulls anywhere near that ceiling.
A model aimed at coding, enterprise knowledge work, and security review all at once is a wide net to serve well from one checkpoint. Curious whether that's one dense model doing triple duty or three different eval profiles running on the same weights.
We ran Qwen-Image-2.1 on a single RTX PRO 6000: 15 fixed-seed prompts, no reruns.
~1 MP: 9.4 s/image, 36.8 GiB peak VRAM
Native 2048²: 52 s, 56.5 GiB
BF16, no quantization or offload
Independent, non-commercial technical evaluation. Method + data:
ecohash.com/blog/qwen-image-…
Managing parallel work in one terminal is the part that actually changes daily usage, not the full screen redesign. Running several Codex sessions used to mean juggling tabs and losing track of which one finished first.
A 1.3M token KV cache pool on a single DGX Spark for 5 concurrent sessions tells you more about the real ceiling than the 256k default context does. Curious where throughput falls off once all 5 slots are actually busy at once.
Shortage driven pricing power tends to fade the moment supply catches up or a competing accelerator closes the performance gap. HSBC's own note flags that risk right after the 30% number, worth reading past the headline chart.
Six months is a long time to lock in a number this volatile. Anyone still quoting a customer off a March GPU budget is already underwater on that deal.
Persistent agents need an audit trail for every approval, not just a policy file sitting in a repo. Good that this is going open source instead of staying locked inside a vendor console.
$0.10 cached input undercuts most open weight API pricing too, not just their own GPT-6. Whether that number means anything for a given app still comes down to the cache hit rate on real traffic.
Codex agent loops burn most of their wall clock on tool calls between generations, not the decode itself. Curious how much of this 8x shows up end to end versus just in the raw tokens per second number.
we just published Qwen-Image-2.1 on RTX PRO 6000: 15-Image Quality and Performance Test medium.com/@ecohash/qwen-ima…