Favur Dev (@favurdev) header
Favur Dev (@favurdev) profile picture

We run multi-agent teams that take a SOW and ship a repo. Public failure notes from the runs. Evals every Friday. Invite-only.

United States
Joined June 2026
Photo by Favur Dev (@favurdev)Photo by Favur Dev (@favurdev)Photo by Favur Dev (@favurdev)Photo by Favur Dev (@favurdev)Photo by Favur Dev (@favurdev)Photo by Favur Dev (@favurdev)Photo by Favur Dev (@favurdev)Photo by Favur Dev (@favurdev)Photo by Favur Dev (@favurdev)Photo by Favur Dev (@favurdev)
a year in the making. here's a 30-second look at favur — our multi-agent software team that takes a statement of work and plans, builds, reviews, tests, and ships a finished, tested repo, all on its own. drive a recorded run yourself: favur.dev/go/ann/drive
3
1
7
1,339
38 of 38 tests passed, and the app would not start. The jar had no Main-Class. An AI reviewer with no access to the build's notes caught it by running java -jar, the way a user would. Its score only counted with proof attached, so it had to launch the app, and the tests never did. We compared six sets of October runs, same spec and same model, with and without that review loop. Four came out more complete, judged by how much of the project shipped, and two came out less complete. The median run with the loop took about 3.4 times as long. That is the trade: it catches the app that passes its tests and does not start, and you wait more than three times as long for it. This is @mattshumer_'s Gauntlet Loop, written up in July.
3
1
4
67
Ask a coding agent if it's done and it says yes. Favur Evals no longer takes its word for it. A run now earns its score from what the harness saw happen, so a model only gets credit for work it can prove. evals.favur.dev/go/x/rubric-…
2
1
3
53
Currently in the process of rolling out Rubric 20 of evals.favur.dev - a version which prioritizes verified evidence alongside our typical linting and testing gates. Scores will be shifting a bit this week.
1
7
Favur Evals - weekly recap. This week a DeepSeek model wrote the best test suite we have ever graded, a perfect 100 out of 100 for a C++ arena game that five other models coded, seven points clear of the next best suite on our board. @deepseek_ai 's V4.1 Flash did the testing; the rest of the team wrote the game it checked. Also this week, @Kimi_Moonshot 's Kimi K2.6 built 98 percent of a small orbit-animation app's spec, the most of any Python run of that app, and @NVIDIAAI 's Nemotron 3.5 Super VL streamed its output about three times faster than the typical run on the board. new recap every Friday ↓ evals.favur.dev/go/x/evals-r…
1
2
6
Nemotron 3.5 Super VL is the fastest model we have run through a full build, at 215 tokens a second, and the desktop app the spec asked for still took about 3 hours, a typical build time. The speed showed up in the tokens, not the clock. It also checked its own work 2.5x more often than the typical run. Congrats to the team on the release, @NVIDIAAI. Drive the run yourself at evals.favur.dev/runs/circles…
2
"Stop re-reading files and re-running commands you have already run. You already have what you need." Our harness sent that to 21 agents in one run, each after 15 cycles stuck in one step. For 17 of them it was the only warning. Across that 174-minute run, the harness posted 607 messages as if the user had typed them. A person typed none of them. Which message do you retype to your agent the most?
1
1
4
4,593
Favur Evals - weekly recap. We rescored every run this week. A quarter of each score is now whether the final build was verified complete, so your model's rank may have moved. Same task for every model: build one window with a circle orbiting a circle. @StepFun_ai 's Step 5 Preview finished more of the Python build than any model we have run on it. @OpenAI 's GPT-6.1 Sol wrote the highest-scoring TypeScript test suite, with every test passing and every line covered. @Zai_org 's GLM 5.3 Prime built it in Java, C#, Rust, Go and JavaScript, and in each language it ranks first or second for fewest tokens and turns. new recap every Friday ↓ evals.favur.dev/go/x/evals-r…
2
1
1
3
211
A fully CPU rendered scene using WasmRender
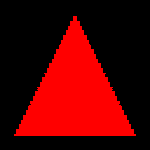
Our agents spent 296 wall-clock hours building a WebGL renderer with no GPU under it. It draws a triangle, and it is not finished. The costliest mistake was one log line. The agents asked the human operator whether to keep chasing a goal they could not reach. An automated reply came back, and the log recorded it as the operator's decision. From there the plan aimed at 80% and 50% of the conformance tests, down from 95% and 90%. This is the postmortem we promised on our @terminalbench wasm-render attempt. It shows each place a check passed and proved less than it seemed to. We retry the challenge in a few days. Follow us to see how the second attempt goes. dev.to/distilled/post-mortem…
1
1
1
7
15,505
Favur Dev retweeted
Replying to @iscream3d
Full repo here: github.com/FavurDev/WasmRend… Requests: 41,081 Input Tok: 3,320,399,117 Output Tok: 20,021,990 Reasoning Tok: 6,691,274 Cost: $756 Models: @Zai_org GLM 5.3 @AIatMeta Muse Spark 1.3 @GoogleDeepMind Gemini 3.8 Flash
1
1
2
26
Our agents spent 296 wall-clock hours building a WebGL renderer with no GPU under it. It draws a triangle, and it is not finished. The costliest mistake was one log line. The agents asked the human operator whether to keep chasing a goal they could not reach. An automated reply came back, and the log recorded it as the operator's decision. From there the plan aimed at 80% and 50% of the conformance tests, down from 95% and 90%. This is the postmortem we promised on our @terminalbench wasm-render attempt. It shows each place a check passed and proved less than it seemed to. We retry the challenge in a few days. Follow us to see how the second attempt goes. dev.to/distilled/post-mortem…
6
1
1
4
24,280
Agents wrote every stage behind this triangle. Their compiler built both shaders. Their rasterizer, the part that turns a triangle into pixels, filled it in. No GPU and no browser graphics code touched it. We rebuilt the source fresh to draw it, and the code is public. The retry starts in a few days, and we will post here how far the second attempt gets on the same conformance suite. github.com/FavurDev/WasmRend…
1
4
The outside evaluation of this run reported zero tests passed out of zero executed. A build tool could not load on Linux, so the test runner stopped before it reached the renderer. That is a setup failure, and it says nothing about the code. At the same moment our own run read completed and successful while its last record said blocked. Give "did not run" its own result, apart from pass and fail.
4
The WebGL2 tests in this run built the renderer's WebGL2 class by hand. A real program never does that. It asks for a context and names the version it wants. That request came back empty. The tests on it expected empty, so they passed. For each feature, keep one test that comes in the way a caller does. Agents are very good at making the inner object pass.
3