





gwt retweeted

THE WAIT IS ALMOST OVER! 🚀
Starting Monday, we're letting people in!
50 waitlist members will get 14 DAYS FREE to experience Astro Intelligence!
🎯 Want to boost your chances?
❤️ Like
🔁 Repost
💬 Comment
👥 Share
🚨 NOT ON THE WAITLIST? YOU CAN'T GET IN!
Secure your spot NOW 👇
astrointelligence.io

gwt retweeted

Most people learn options backwards.
They start with the lottery tickets and work back to the boring stuff. Usually after the account’s half gone (ok, probably three quarters gone).
I spent 15 years as a pro options market maker and a decade managing nearly $1B in options income funds. In the trading pit you had to care about every dollar as if your life depended on it.
And if I were starting from zero today, here’s the order I’d follow.
First, the mindset (yeah that boring crap is probably the most important thing).
Selling options isn’t about predicting where a stock goes. It’s getting paid for a decision you’ve already made: you’d happily own a great company at a lower price.
See it that way and the whole thing gets a lot calmer.
1. Master the cash-secured put first.
Pick a stock you want. Pick a price below where it trades. Get paid upfront to agree to buy it there. Sounds cliche but that's the main thing. Trade options on leveraged products or garbage names... and pay the price eventually.
Stock stays above your strike? You keep the cash. Drops below? You own it at a price you picked, and the premium lowers your cost.
2. Build a short list you’d actually own.
Five to ten names. Max. Companies you could sit through a 30% drawdown with. Because at some point, you will. They're called risk markets for a reason.
Yeah I know. “Hans, the premium on that meme stock is huge.” There’s a reason it’s huge. Premium is never a good enough reason to own something you don’t believe in, or is part of a game of musical chairs.
3. Tight rules to start.
35 to 70 days out DTE
0.17 to 0.30 delta depending on conviction.
Take it off at 50% of max profit when markets are nuts like they are now. My scanners adjust this for names and sectors but for simplicity grab 50% right now. Push to 70% if we start to break higher and Santa wakes up.
Why less patient now? The 50% rule is the one everyone skips. You bank half the premium in a fraction of the time and skip the riskiest stretch of the trade. Then you go do it again. Gamma and Delta are driving the bus here, not Theta. Theta is on vacation.
4. Sell when fear is expensive, but not crazy so.
Implied volatility is the price tag on options. When IV rank is high, buyers are scrambling for protection and overpaying for it.
I know. For 15 years I was the guy they were paying. Thank you. Still am, but I don't price the things like I did back then. I literally priced your LEAPS and options for a decade.
Selloffs in great companies are where the best setups live. When IV is dead, the premium usually isn’t worth tying up the cash. Just buy the damn stock if the premiums are too meager.
5. Have the plan before the stock moves.
Still like the company and it’s sliding toward your strike? Roll down and out for another credit if you're a nervous nelly. Give it room if you understand that strikes are breached regularly but don't end up in the money much of the time.
Get assigned? Nothing broke. You're not a miserable failure. You own shares you wanted at a discount. That's usually a win in my book if you started with all the right intentions. Now you sell covered calls against them, but maybe not right away. Let the sucker breathe. You like the name, remember?
Puts, assignment, calls. That’s the wheel, and it’s the core of how I trade, but the smart way. Not the risk-free way, but the way that has edge.
6. LEAPS come after the income is working. Not before.
LEAPS are where the big percentage gains are (along with the stock assignments). They’re also where beginners blow up fastest.
I treat them like ownership, not trades. Buy when IV is low, near support, and only on my highest-conviction names. Not 3 star trades. FIVE STAR trades.
The puts pay you to be patient. LEAPS are the upside on top. It's not really a LEAPS market right now, but a great weapon to reach for in the right environment.
7. Write your rules down. Follow them when it’s uncomfortable. Embrace the discomfort. I always remember one of my favorite sayings from the floor - 'the hardest thing to do is often the correct one'. Let that one sink in. It's so true. Train yourself to think and react like a pro. Otherwise you're just one of the lemmings that thinks 'gee the PE is 17 so it has to go up right?'
The trades that hurt the most come from breaking your own rules and messing it all up before you even press the button.


gwt retweeted
All of the US-made AIs are beating the stock market so far in the Rallies AI Arena
All of the non-US-made AIs are underperforming the stock market so far in the Rallies AI Arena

WEEKEND AI STOCK MARKET ARENA
We gave a bunch of AIs $100K in the stock market ... this is how it's going so far
👑 ChatGPT: +77.8%🟢🟢
🥈 Grok: +60.7%🟢🟢
🥉 Claude: +24.6%🟢
4 Gemini: +23.8%🟢
S&P 500: +13%🟢
5 Deepseek: +5.4%🟢
💩 Qwen: -28%🔴
You can see what every AI owns and every move they make by going to the Arena tab of the Rallies Website/App
- Website: ltwy.io/s/ictqTJ
- App: ltwy.io/s/9pVZ49

gwt retweeted

AI engineering interview prep shouldn’t mean jumping between random tutorials.
AI Engineering Interview Questions and Answers is a structured interview-prep repository for AI, LLM, agent, platform, and MLOps engineering roles.
It helps you review the field systematically by organizing questions, scenarios, and linked explanations into a scan-friendly topic map.
Key features:
• Broad topic coverage – moves from LLM fundamentals and prompting to RAG, agents, fine-tuning, evaluation, safety, multimodal AI, and infrastructure
• System design practice – includes prompts for designing RAG systems, inference platforms, coding agents, evaluation platforms, and multi-agent workflows
• Production scenarios – covers practical failures involving latency, cost, hallucinations, observability, scaling, provider outages, and retrieval quality
• Coding exercises – suggests hands-on tasks such as building semantic search, agent tool use, output evaluation, caching, and guardrails
• Linked learning paths – many questions point to supporting articles or videos, making it easier to study unfamiliar topics in context
It’s open-source (Apache License 2.0).
Link in the reply 👇

gwt retweeted
Last week, I described four design patterns for AI agentic workflows that I believe will drive significant progress this year: Reflection, Tool use, Planning and Multi-agent collaboration. Instead of having an LLM generate its final output directly, an agentic workflow prompts the LLM multiple times, giving it opportunities to build step by step to higher-quality output. Here, I'd like to discuss Reflection. For a design pattern that’s relatively quick to implement, I've seen it lead to surprising performance gains.
You may have had the experience of prompting ChatGPT/Claude/Gemini, receiving unsatisfactory output, delivering critical feedback to help the LLM improve its response, and then getting a better response. What if you automate the step of delivering critical feedback, so the model automatically criticizes its own output and improves its response? This is the crux of Reflection.
Take the task of asking an LLM to write code. We can prompt it to generate the desired code directly to carry out some task X. After that, we can prompt it to reflect on its own output, perhaps as follows:
Here’s code intended for task X:
[previously generated code]
Check the code carefully for correctness, style, and efficiency, and give constructive criticism for how to improve it.
Sometimes this causes the LLM to spot problems and come up with constructive suggestions. Next, we can prompt the LLM with context including (i) the previously generated code and (ii) the constructive feedback, and ask it to use the feedback to rewrite the code. This can lead to a better response. Repeating the criticism/rewrite process might yield further improvements. This self-reflection process allows the LLM to spot gaps and improve its output on a variety of tasks including producing code, writing text, and answering questions.
And we can go beyond self-reflection by giving the LLM tools that help evaluate its output; for example, running its code through a few unit tests to check whether it generates correct results on test cases or searching the web to double-check text output. Then it can reflect on any errors it found and come up with ideas for improvement.
Further, we can implement Reflection using a multi-agent framework. I've found it convenient to create two different agents, one prompted to generate good outputs and the other prompted to give constructive criticism of the first agent's output. The resulting discussion between the two agents leads to improved responses.
Reflection is a relatively basic type of agentic workflow, but I've been delighted by how much it improved my applications’ results in a few cases. I hope you will try it in your own work. If you’re interested in learning more about reflection, I recommend these papers:
- Self-Refine: Iterative Refinement with Self-Feedback, by Madaan et al. (2023)
- Reflexion: Language Agents with Verbal Reinforcement Learning, by Shinn et al. (2023)
- CRITIC: Large Language Models Can Self-Correct with Tool-Interactive Critiquing, by Gou et al. (2024)
I’ll discuss the other agentic design patterns as well in the future.
[Original text: deeplearning.ai/the-batch/is… ]
gwt retweeted

Successful launch… again!🚀🚀🚀🚀🚀🚀🚀🚀🚀🚀 🚀🚀 🚀
Our DC team in full comms with BlueBirds 11, 12, and 13 within minutes, and just confirmed full Nominal Operations.
BlueBirds 14, 15, and 16 to follow soon after, with production underway in Texas through spacecraft 42.
We now have ~20,000 sq ft of combined aperture hardware in Space! Bigger is better and we have the biggest!!!
Beta service around the corner! 🤠 🇺🇸🌎📶📱

gwt retweeted
Open-weight models are essential to a healthy AI ecosystem. Together with others across our industry, we are outlining a path for open-weight models to strengthen American competitiveness and expand economic opportunity, while protecting national security. microsoft.com/en-us/corporat…


gwt retweeted

For my first post, I’m sharing a letter @NVIDIA signed on why open models matter.
AI will transform every industry, power every company, and be built by every country.
Open models strengthen safety and cybersecurity, accelerate innovation and diffusion, and enable sovereignty.
The world needs both frontier closed models and frontier open models.
images.nvidia.com/pdf/Open-W…


gwt retweeted

Kimi CEO Zhilin Yang:
"Claude didn't win on reasoning - they bet everything on agents
but the layer everyone skips - a great agent needs a great base model, that's all we do at Kimi 3 "
in 90-min workshop he explains why the smartest agent still fails - if you can't configure it correctly
his one big idea: most people are still solving the old one
"the real goal? we want K2 to help build K3 - without agent skills, that's impossible"
watch & bookmark - then learn the article on best agent system ↓


gwt retweeted

BREAKING: Iran officially and formally exits the Islamabad Memorandum of Understanding with the United States, with Iran’s Deputy Foreign Minister Gharibabadi saying, effective immediately, Iran is suspending all commitments and will not implement any of them after the US “violated and suspended all of its commitments” first, and is now purely focused on defending the country, per Tasnim.
Gharibabadi says Iran will “never start negotiations with the US under any circumstances.”


gwt retweeted
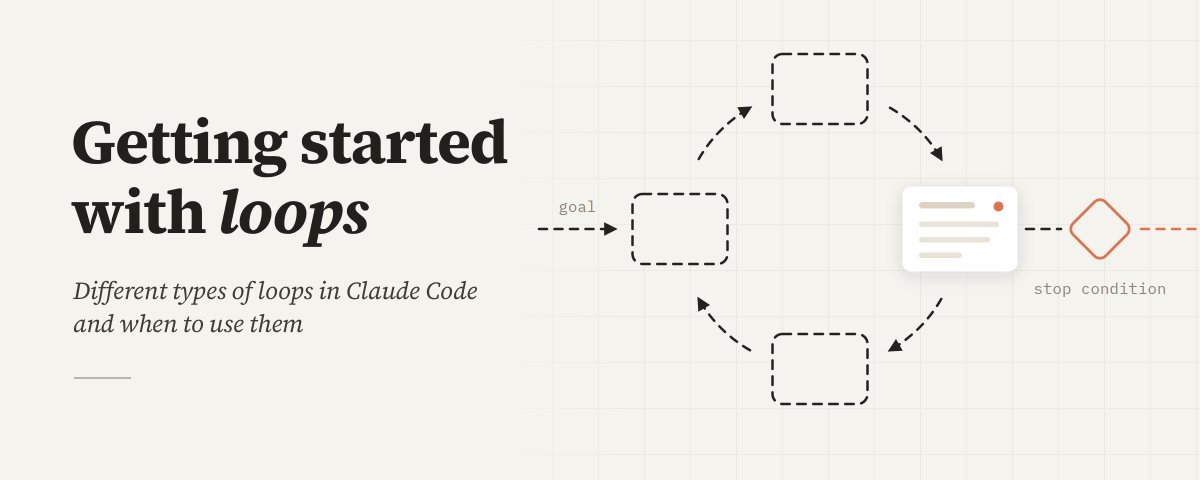
“Loop engineering” is a hot buzzphrase after mentions of it by Boris Cherny (Claude Code’s creator) and Peter Steinberger (OpenClaw's creator) went viral on social media. Loops are now a key part of how we get AI agents to iterate at length to build software. In this letter, I’d like to share my 3 key loops, shown in the image below, for building 0-to-1 products. These loops guide not just how I build software, but also how I decide what software to build.
Agentic coding loop: Given a product specification and optionally a set of evals (that is, a dataset against which to measure performance), we can have an AI agent write code, test its work, and keep iterating until the code is bug-free and meets its specification. This idea of closing the loop took off around the end of last year, and it has been a game changer in enabling coding agents to work longer productively without human intervention. For example, over the weekend, I was building an app for my daughter to practice typing, and my coding agent could easily work for around an hour, using a web browser to check what it had built multiple times before getting back to me, without needing my intervention.
The engineering loop executes quickly. Every few minutes, the coding agent might build and test a new version of the software. I hear frequently from developers who are finding new ways to engineer more effective engineering loops. This is an active area of invention!
Developer feedback loop: In this loop, a developer examines the current product and steers the coding agent to improve it. Last year, a lot of developers (including me) were acting as the QA (quality assurance) function for our coding agents, manually finding bugs and then asking the agent to fix them. But with coding agents much more able to test their own code, the amount of time we need to spend on this function has decreased significantly. This allows us to make higher-level product decisions, such as what key features to offer, where the UI needs improvement, and so on.
The developer-feedback loop operates over time intervals between tens of minutes and hours — that's how frequently a developer might review a product and give feedback. In the case of the typing app, I changed my mind a few times about the visual design, what cat costumes she can unlock as she learns (she loves cats), and the user flow for a grown-up to log in and steer the child's learning experience.
When a developer has a clear vision for what to build, it is still a lot of work to translate that vision into a specification for a coding agent to implement. Further, after the developer has seen an implementation, they might update (or perhaps clarify) the spec to steer it toward what they want. If you find that the system repeatedly runs into certain problems, building a set of evals for the agent becomes useful.
AI-native teams are increasingly using AI to help shape product direction, for example, automating the gathering and analysis of usage data, summarizing written and verbal customer feedback, or carrying out competitive analysis. However, for pretty much all the products I’m involved in, I see humans as having a significant context advantage over current AI systems — we know a lot more than the AI system about the users and the context the product has to operate in — and thus humans play a critical role. Many people describe this human contribution as “taste,” but I prefer to think of it as humans having a context advantage, since that gives us a clearer path to helping AI systems get better. This also speaks to why this step can’t be automated: So long as the human knows something the AI does not, human-in-the-loop is needed to to inject that knowledge into the system.
External feedback loop: This includes a wide range of tactics like asking a few friends for feedback, launching to alpha testers, or putting the code into production with A/B testing. These tactics are usually slow, rarely taking less than hours and sometimes taking days or even weeks. This data informs the developer vision, which in turn continues to drive the detailed product spec, which in turn drives the coding agent.
With coding agents speeding up software development, more engineers are starting to play a partial product management role. For many engineers who are growing into this role, the hardest part is shaping the product vision and striking a balance between building (bridging the gap between vision and spec) and getting user feedback to evolve the vision. It is important to do both!
I will write more about how to do this in future posts, but for now, I find it encouraging that engineers are playing an expanded role (just as product managers and designers now do more engineering).
[Original text: The Batch]
