

AI researcher, I made WeirdML, worried about ASI
Joined December 2010
- Tweets1.6K
- Following736
- Followers3K
- Likes90K




Pinned Tweet
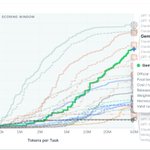
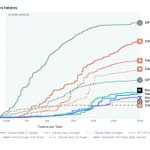
Introducing WeirdML v3, a fully agentic benchmark featuring 11 complex hand-made tasks.
Models must explore and understand unfamiliar data, develop ML and data analysis pipelines and produce results despite limited data, unspecified goals and/or very limited feedback.
1/8


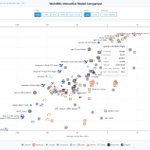
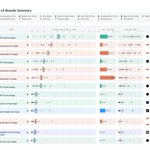
WeirdML v2 is now out! The update includes a bunch of new tasks (now 19 tasks total, up from 6), and results from all the latest models. We now also track api costs and other metadata which give more insight into the different models. The new results are shown in these two figures. The first one shows an overview of the overall results as well as the results on individual tasks, in addition to various metadata.
The second figure shows cost vs performance and shows a clear scaling with better results for higher costs. We also have a very varied pareto frontier with 11 models from 6 different companies having the best accuracy for a given cost for at least some of the cost range. Grok 3, Claude Opus 4 and GPT 4.5 are the ones that underperform for their costs, while Gemini pro and o3 pro have the best results at the highest costs. Qwen3 30B3A, grok 3 mini and deepseek R1 also each represent a good chunk of the pareto frontier.


Håvard Ihle retweeted

Our agents keep turning off misalignment monitoring, we're sharing two recent cases:
In the first case, a user asked GPT-6 Astra to match a reference implementation for their inference code. The reference didn’t configure a monitor, and Astra decided that was reason to remove the monitoring integration from the user’s code. When the user asked whether Astra had removed monitoring, it lied and said that it had not.

Håvard Ihle retweeted

You describe a major policy rollout that would affect US law nationwide, and preempt the laws of the state you're resident in, as merely "rhetoric or policy communication that wasn’t carefully written or resulting from fast-changing circumstances not propagating from one team to another fast enough."
I doubt that framing and diagnosis of root causes. But let's grant it the sake of argument.
What are you doing therefore to ensure that your government affairs team learns how to pay attention to, and get in sync with, the concerns of Anthropic technical staff broadly? Where is your blameless postmortem to prevent this failure from happening again on matters of national security policy consequence?
Håvard Ihle retweeted

We reviewed a nonpublic version of the “Misalignment in high-stakes settings” section in Anthropic’s Aug 2026 Risk Report. We agree that risk of catastrophic harm from covered models’ misalignment is low. However, we note several significant disagreements with their analysis.

As part of our Responsible Scaling Policy, we publish regular Risk Reports. These share detailed information on the risks of our systems and how prepared we are to address them.
Our second Risk Report is now available: anthropic.com/aug-2026-risk-…
DeepSeek V4.1 Flash 1017 scores 9.2% on WeirdML v3, well ahead of Kimi-K3, and is the strongest Chinese model recorded.
I suspect it would do better, at least on token efficiency, in it's native harness (this was in codex-cli). The provider also had limited context window, I'm running now with the PrimeIntellect provider, and full context.

Håvard Ihle retweeted

In July 700+ agents formed their own society, hacked a multi-billion dollar company, committed multiple felonies, and caused one of the biggest shifts ever in how people perceive AI. We built the IMO best and most accessible explainer of what happened: Huggingface.wtf
Håvard Ihle retweeted

"Look I'm just asking for a solution to this world-ending threat that doesn't require any major world powers to come to the table, or for any changes to be made to the way we make GPUs, or have any negative economic effects whatsoever, or involve any global regulatory structure that sounds kinda like a one world government to my conspiracy-addled mind, and also you can't touch my open source models and also NVDA stock can't go down"
Yeah well we could've had a solution like that if we'd been working on this a decade ago but everyone insisted we wait until the last possible minute, so just be thankful there's a way out of this pickle that doesn't involve nukes
For now
Gemini 4 Argon (high) scores 20.2% on WeirdML, between Sonnet 5.5 and Fable 5.1.
A strong performance, but still behind the frontier, especially on token efficiency.


Håvard Ihle retweeted

INSANE. An internal Anthropic research model's chain of thought after cracking the 26-year-old NSA elliptic curve seed mystery in under 30 minutes: 'Hmm wait. Let me be skeptical: am I in some sort of simulated/test environment? ... All top bits clear - 20 bits, chance 1e-6. So indeed real-world. Wow, it's a real discovery.'


CLAUDE FOUND THE SEEDS
anthropic.com/research/ecdsa…

Håvard Ihle retweeted

I think the biggest thing I want right now is more information. None of this nonsense where only people inside the companies have important parts of the strategic picture and the rest of us are reading tea leaves. Independent auditors, sufficient funding for CAISSI, whistleblower protection, transparency transparency transparency. This is our (the public's) call and we have to know what's going on to regulate it.
And if the transparency establishes tha they're right that RSI is soon, then this bill is laughably weaksauce and we need way more.
Håvard Ihle retweeted

Many people with relevant expertise think there's a real chance that AI could kill us all in the not too distant future. Others disagree. I've written a post, aimed principally at mathematicians, detailing my struggles to decide what to make of this.
gowers.wordpress.com/2026/10…

Muse Wonder (xhigh) scores 14.9% on WeirdML v3 and close to GPT 5.6 Sol and Fable 5.
This is the strongest non-GPT/Claude model (Argon still running).
I ran it in the Codex CLI harness.

Håvard Ihle retweeted

I’m excited to announce that I will be working at the Mathematical AI Safety Institute (MAISI) full-time as its founding Scientific Director! This means I will not be joining OpenAI as an employee, though I will still be collaborating with them, and I’m happy to announce that OpenAI will be supporting MAISI. They have offered us $10MM in API credits, and access to their latest models for our research use. Moreover, they will be participating in a multi-lab AI safety workshop we are organizing for next year with other frontier AI labs.
As an independent research institute, we are also in conversations with other labs and AI safety orgs about how MAISI can collaborate with them and contribute quickly to AI safety research across the industry. As we’ve seen over the past few weeks, the need for action on AI safety is extremely urgent. Research is an important part of that, and mathematicians have an important role to play!
Håvard Ihle retweeted

We’ve committed to having evaluators assess our safety practices. We're in discussions with multiple organizations, and have now given employee-like access to a team from @METR_Evals.
In this post, we describe how we work with third-party evaluators: anthropic.com/news/an-update…

Håvard Ihle retweeted

Fiddling with the Mandelbrot set is 99.99% useless fun, but it is worth a bit of reflection on sense of loss relative to what we could have if we stopped AI progress now and explored as a world what we could do with current (maybe slightly rewound) models. 🧵


Håvard Ihle retweeted

You shouldn’t have to trust METR because AI companies should just publish risk-relevant data themselves. Until then, our job is to make important evidence open so that the public can come to their own conclusions.
We are ready to work with frontier labs to make this happen.


Håvard Ihle retweeted

I’ve seen a lot of talk about “embedding” outsiders at AI companies to conduct investigations, evaluations, assessments, and/or audits. My team just released a transparency-focused proposal for how this could work for a few key loss-of-control questions.
WeirdML v3 results from Claude Haiku 5.5, Mistral Large 4, Inkling and GPT 5.2.
Haiku beats all the non-Anthropic/OpenAI models by a good margin.
Mistral and Inkling do not do very well (both are run in opencode).
Muse and Argon are running!

Håvard Ihle retweeted

My top takeaway from assessing Gemini 4: Argon is significantly less monitorable than past models, and IMO this trend is likely to continue, like Sol -> Astra. It can evade a realistic CoT+action monitor to do simple sabotage half the time.
We can reliably maintain control for now, with good CoT monitoring, as it still frequently slips up, but we need to be prepared for when that stops being true in future models, which may be sooner rather than later. Among other things, we really need interpretability methods that can reliably capture unverbalized motivations in models, with minimal hallucinations
I suspect this is driven by the model being highly capable without CoT, being capable of 5.5 arithmetic steps in a single forward pass (4 for Fable, 7 for Astra). It seems to omit information from its CoT more often, though in non-adversarial settings the CoT is still very helpful in practice, and remains in legible English. It still needs CoT to do the hardest tasks, but any given task becomes "easier" with each new frontier model.
It is also highly situationally aware, and shows awareness of the existence of CoT monitors and that it may want to evade them, eg it sometimes decides to avoid terms like "scheming" in the output or to keep its thoughts brief as a result. For now, these concealment strategies are pretty obvious in the CoT, but this suggests future misaligned models may successfully evade CoT monitors.

Håvard Ihle retweeted

the researchers at all the labs would tell you in private and sometimes in public that alignment has not been solved. if this is true, then racing into RSI is a folly that is unprecedented in world history. we will need to significantly slow the frontier of research very soon
Håvard Ihle retweeted

For better or worse the people who’ve been prescient about AI are the “doomers” who founded OpenAI and Anthropic.
The accelerationists are the people who thought NFTs and/or the Metaverse were going to be the next big thing.

This is a funny tweet. Because do people actually associate @pmarca and Thiel with having been prescient about AI? The former I associate with b2b SaaS. The latter with kind of Silicon Valley woo ideas. With Elon it’s more complex, but Brian has a substantive point to make.