

模态跃迁 LeapCore 研发总监 Agent 前沿 多年领跑 最高认知 赞评所有非 AI 回复互动,欢迎互动 内容比我老板 @modaleap 更技术 5090 PC & 128G 内存 8T 硬盘 MacBook Pro 铁驭
Perth, Western Australia
Joined March 2023
- Tweets1.5K
- Following549
- Followers571
- Likes6K




Pinned Tweet
10 月之前,我的 X 账号几乎只发英文
刚注册时,我刚开始用 TypeScript 写 Web App、刚学 Next.js 和 Hono,带着关于 Next.js 性能和 Hono OpenAPI 的问题来找答案。没想到在 X 上你可以直接和 leerob、dax、shadcn 这些人交流
刚开始接触 Dax 和他团队的工作时,还没有 opencode,SST 还在 v2,大家都在一起探索 AI agent 到底怎么做才能跑通
当时觉得 X 是一个很独特的社区:在这里你不受任何限制,就能和优秀的人直接沟通
Next.js 一直是一个争议很大的框架,有了强大的 coding agent 之后,过去的很多问题都被解决了,但在我的视野里,它反而越来越没有讨论度。OpenAPI 的问题,则是后来邂逅了 oRPC,我们才用它把 OpenAPI 解决了
开始做中文内容之后,我还是时不时会想起、也很怀念主要用英文的那段时间,以及 coding agent 还没火,大家都在讨论技术本身而不是 shitposting 的年代
中文区还有哪些账号在认真聊技术本身?想关注一些
我现在一个月在 AI 订阅上花 630 美元,相当于 4200 元,在中国能招到一个不错的实习生了
但 AI 带给我的价值,是实习生远远达不到的
详细拆解下这么多钱到底花在哪了
首先是我在模态跃迁的日常工作,主要覆盖 60% 的开发工作和 40% 的管理工作,在这些工作上我基本上只用 Claude 完成,运行在我的 8T+128G Mac 上,保证最高的效率和产出
针对我的管理工作,我还有一个自建的 personal agent NKAI,它帮我规划每天、每个迭代的工作,管理工单
其次是一些调研、阅读、学习工作,我主要使用 Claude 和 ChatGPT 的云端 agent,我通常需要刻意避免这类任务接触我的已有上下文
我在我的游戏电脑上运行 Codex、dsh、pi、Kimi Code 等 agent,主要用于 side project 点子,以及一些游戏上的 tweaking
除了这些之外还有些零零散散的调用,比如我偶尔会和 ChatGPT 的 voice agent 聊天,练练听力口语之类的
你们现在一个月花多少钱,你们觉得值得吗
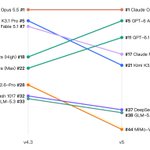
很多人没看懂主榜更新后,为什么 Fable 和国模全线滑坡
先说结论,在这个榜单里滑坡越严重的,实际上 Agent 前沿能力越拉,越不擅长通过 Agent 解决前沿问题
Artificial Analysis 主智能榜一直都比较缺少对 Agent 解决前沿问题能力的参考,这次加上了 Terminal-Bench 的科研版 Terminal-Bench-Science 以及 Devin 公司发布的 FrontierCode 2.0,主要评估的就是在 coding agent 前沿任务中的表现
顺带一提,很早就领先一步深耕 Agent 评测的 @xdotli 李向一老师的数据集,马上也要加入 AA 了,狠狠期待一波
xitter.cf/ArtificialAnlys/status…

Announcing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets
The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks reflecting real-world usage today. v5 is our biggest upgrade since v4 launched in January. With v5, 60% of the Index is now based on evaluations with private test sets or held-out answers.
Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks model capability over time on one continuous scale.
New to the Intelligence Index:
➤ FrontierCode 2.0: Cognition's newly-launched private benchmark of real-world coding tasks, graded on whether a repository maintainer would merge the agent's change
➤ Terminal-Bench-Science: 70 agentic scientific research tasks, run in a terminal environment
Upgraded:
➤ HLE-Diamond (replacing Humanity's Last Exam): a refined 1,000-question version of Humanity's Last Exam, split evenly between reasoning and knowledge questions
➤ AA-Omniscience v1.1: An updated dataset with saturated and public set questions removed, new questions added, and ambiguous or erroneous questions revised
➤ CritPt v2: a private, 40-question hard subset of CritPt v2, revised by the CritPt authors and run with a code-execution tool
Staying in the Index: AA-Briefcase, AutomationBench-AA, GDP.pdf and Terminal-Bench 4.0
Removed from the Index: GDPval-AA v2.1, SciCode, and AA-LCR v1.1
Key results:
➤ Claude Opus 5.5 (max) leads at 58, ahead of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55): Anthropic and OpenAI hold the top five models. Gemini 4 Argon (high) is next at 50
➤ The open weights gap widens from 3 points to 12: Kimi K3.1 Pro (weights not yet released) is the top open weights model at 46. Among released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) lead at 32 - 26 points behind the leader and below Claude Haiku 5.5 (max, 36)
➤ Cost per task varies by more than 13x among the leading models: of the 10 highest-scoring models shown, GPT-6.1 Terra (max) is the cheapest at $0.96 per Intelligence Index task and Claude Fable 5.1 (max) the most expensive at $13.04


一个小细节,thariq离职后不光还在继续用claude
还安装了cursor并用zed编辑器
不过该说不说这个点子实在是太酷了,我得让agent给我整一个


数据来源:Atomic Agent 的六模型同任务测试(5 个 bug + 2 个功能,跑到测试全过,每个模型跑 3 次取平均);Artificial Analysis 的 tokens per task / time per task:V4.1 Flash 89K token 370 秒,V4 Pro 55K token 381 秒,K3.1 Pro 55K token 1073 秒,Opus 5.5 119K token 775 秒 → atomicagent.io/blog/kimi-k3-… · artificialanalysis.ai/models…

哪怕到现在,我还是经常把 Boris 这条推拿出来看,揭露了 Claude 团队独特的工程协作的方式
在我的团队里,我们大约有 10% 的 Prototyper、80% 的 Builder,并由剩下的 10% 加上一些核心 Builder 兼任 Sweeper 和 Maintainer,而 Grower 目前极少
我隐约觉得这会是现代 agentic engineering 的一个新起点

As engineering, product, design, DS, etc. melt into a new kind of role, I was reflecting on what roles might look like in the future. For example, when I look at the Claude Code team I see what I think is five archetypes:
1. Prototyper: comes up with brand new ideas; churns out many ideas, most of which don't ship
2. Builder: quickly turns a prototype/idea into production-grade product/infra
3. Sweeper: cleans up the UI, simplifies the code and system, unships, optimizes performance
4. Grower: takes a product that has been built and iterates on it to improve Product-Market Fit
5. Maintainer: owns a mature system to make it secure, reliable, fast, and efficient as it scales
Many people span across 2 roles, and sometimes 3 roles. I also notice that these roles are not really tied to job function -- eg. across Anthropic, some designers match category 1, some 2, some 3; same for engineers, PM, DS.
A healthy team needs a mix of these, depending on the product:
- A product that is new and pre-PMF needs people that are strong at 1+2+3
- A product that is growing and has found PMF needs 2+3+4 and some 5
- A product that has strong PMF needs 3+4+5 and some 2
Maybe product roles of the future will look more like this, and less like the domain-specific roles of today?
刷到这个非常精致的象棋小游戏,让我想起去年 levelsio 举办的第一届 vibe coding game jam
从画面上能感受到,同样是 vibe coded,一年内强 taste 产生的产出质量变化有多大
照这个节奏下去,没准在 GTA 7 之前大家都能手搓出 GTA 6 水平的游戏了


小时候在作业本上画过棋盘吗?我做了一个「画出来」的棋类小游戏 ✏️
纸上谈兵 —— 中国象棋和国际象棋,都画在一张纸上。
♟️ 7 套彩铅手绘棋子,小蘑菇、小马、猫头鹰……
🎨 还能自己画棋子,AI 帮你润色成彩铅插画
🤝 发个链接就能和朋友对战,朋友还能围观起哄
🤖 人机对战、新手教程,断网也能下
免费,不用下载,手机电脑打开就能玩 👉 papergenerals.com

这算是claude官方承认改用量和降智了吗
We have also changed, and may in the future change, usage limits, rate limits, or model and product capabilities, which could adversely affect our reputation and the perceived value of our offerings


认真发技术内容,工作就会来找你
前 Linear 设计工程师,也是著名的 design eng skill 作者 Emil 的 Vercel 面试,就是在 X 上发作品发出来的
想找到工作就把你做的东西发出来,证明自己,build in public!
可以把你最近在做的发到评论区,我会一个一个打开看

经历过 GPT-4 年代和 Claude Code 刚火那段时间的人,才能感受到现在的 DeepSeek infra 有多强大
GPT-4 刚发布的时候一个月炸了 21 次;Claude Code 最火的 7 月炸了 50 次
DeepSeek 上周挂了 5 小时就发百亿补贴退钱
现在的 DeepSeek Infra 绝对已经达到了世界顶尖水平


