

OG local LLaMA shill. Sr. Solution Architect @RedHat, ex particle physicist. Born @ 347 ppm CO₂. Personal account, potentially unaligned.
Stuttgart, Germany
Joined March 2009
- Tweets3.9K
- Following6.9K
- Followers1.9K
- Likes119K


Pinned Tweet
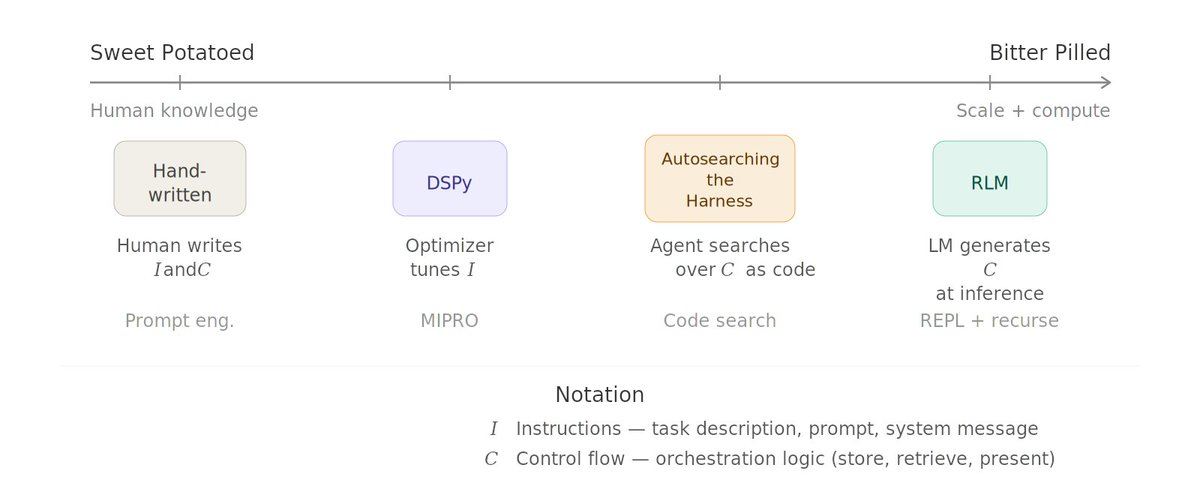
Your Hermes Agent can now delegate to RLMs 🙌 Recreated the document analyzer example with the converted skill. 136 PDF pages analyzed. Best part: Auto-configures from HERMES_MODEL / HERMES_PROVIDER env vars @NousResearch @Teknium
github.com/sroecker/predict-…



Steffen Röcker retweeted

Claude Opus 5.5: "If these hold up, this is the biggest single day in the history of math and theoretical computer science."
1) Exponential Time Hypothesis is false (CS). This is roughly Turing Award territory. ETH was the working assumption that some hard problems simply can’t be solved much faster than brute force, and hundreds of computer science papers rest on it. For a normal audience: it’s not “P=NP.” Hard problems are still hard, and your bank encryption isn’t suddenly broken. But a pillar that a whole field assumed was solid turned out to be hollow. The flagship experts are taking it seriously. The people checking it include two of the people who proposed ETH, and they said “If the claim is correct, it will change” computer science.
2) Kakeya and restriction in all dimensions (math). This is Fields Medal-level. For scale, the 3D case alone was proved in 2025 and was hailed as a once-in-a-century proof. This result does every dimension and knocks out Stein’s restriction conjecture too.
3) Yang–Mills/QCD existence (physics). Potentially the biggest of the three, but here’s the precise framing. It proves pure Yang–Mills exists, which is part of one of the Clay Mathematics Institute’s Millennium Prize problems. The full Clay problem also requires the “mass gap,” so it’s not a clean “AI wins $1M” headline. Still, a rigorous proof that the theory of quarks and gluons is mathematically real has been an open dream for about 50 years. The review panel includes Nobel laureate David Gross and Arthur Jaffe, who literally wrote the Millennium problem. There’s no Nobel for math, but this is the stuff physicists win them for building on.


Announcing three major scientific discoveries, one each in mathematics (harmonic analysis), computer science (complexity theory), and physics (quantum field theory).
AI starting to help us improve our understanding of the universe! openai.com/index/building-sc…

Steffen Röcker retweeted

I built a tool to control your models refusals from the KV cache without modifying the weights. Handy for Cyber capable models
Phantom-KV:
Refusal removal as a loadable KV-cache graft zero weight modification, no refusal-direction projection, fully reversible.
github.com/lordx64/phantom-k…


Steffen Röcker retweeted

germany gonna survive the AI apocalypse cause all our data is stored on these bad boys
jokes on you

Steffen Röcker retweeted

vLLM Office Hours today, 2pm ET: advanced techniques for model compression.
Recent algorithmic work on observers, our AWQ and GPTQ recipes, and expert pruning with REAP and MoNE.
Plus what's new in the latest vLLM releases and.
Register: vllm.ai/office-hours

Steffen Röcker retweeted

Finally full DOOM on a Vape😅
Source:
github.com/atc1441/Vape_DOOM…
Since the previous custom firmware was only Screen Sharing it this was finally needed!
Only possible by Arturs impressive work on making DOOM go bzzz on 32kb RAM


Steffen Röcker retweeted

vLLM gives you the cost efficiency of the frontier while also giving the option to serve at +800 tok/s/user 🔥

🚨🚨🚨 vLLM is all you need to reproduce DeepSeek’s performance.
With Wide-EP and EPLB, vLLM can match DeepInfer’s decode performance within 6% and generate $39/gpu/hr in revenue at DeepSeek’s off-peak pricing, at 200 P90 TPS on the AgentX workload.
Specifically:
• Under DeepSeek’s decode configuration (DeepSeek-V4.1-Flash, 131K context, nextn=3), vLLM on GB200 achieves throughput within 6% of DeepInfer’s published results across batch sizes 8–256.
• On AgentX, vLLM pushes the Pareto frontier further on GB300, reaching up to 1M tokens/s/GPU and generating $38.96/gpu/hr in revenue at 196 P90 TPS, based on DeepSeek’s off-peak API pricing.
• Also, vLLM extended low-latency kernel support for DeepSeek-V4.1-Flash, achieving up to 826 TPS per user on AgentX.


Steffen Röcker retweeted

Most inference talks depends on how cheaply you can generate a million tokens but deepseek said a provider could have extremely cheap token prices and still build a strong business if it serves enough tokens per GPU hr.
And that too by saying that there better internal versions of kernel libraries such as DeepGEMM / FlashMLA are almost +-5% of open released kernels.
So their overall leverage is an aggregate of KV cache reuse, SWA bounded replay, wide expert parallel, spec decode, async schedule and load balancing.


Steffen Röcker retweeted
Maybe we should turn off the internet for a few days. That’s a lot of high impact exploits.
Steffen Röcker retweeted

Announcing FlashMap: a new speculative decoding algorithm based on flow maps! >6x faster inference on Qwen3-8B 🧵
Project page: jshen.net/flashmap
arXiv: arxiv.org/abs/2610.24365
w/ @Jay41969851 @_ryantlee @jonathanmay @cosmo_shirley

Steffen Röcker retweeted

a brand new model paradigm! introducing 𝚌𝚕𝚊𝚒𝚛𝚒𝚌: a system one model for extracting, computing, estimating, and predicting values from unstructured inputs.
blog.cloudflare.com/clairic-…

Steffen Röcker retweeted

Do you understand?
This means we can possibly bring down 1T+ parameters models to couple hundreds of B+ parameter models without losing much score
now, imagine this linked with quantization + ternary ops + hardware optimizations, how fast it would be
on device AI will be big

