Assoc. prof. @BrownCSDept. Working on improving how humans teach computers. Weak supervision, zero-shot learning, few-shot learning, and high-level knowledge.
Joined August 2007
- Tweets1.8K
- Following502
- Followers1.6K
- Likes4.2K


Stephen Bach retweeted

Our research team developed RIFT (RubrIc Failure mode Taxonomy), a framework that evaluates the rubric behind a benchmark score. It computes quality signals from the rubric's content and ties them to a taxonomy of nine failure modes. In controlled tests, RIFT identified injected failure modes with 75.0% accuracy, against 56.7% for an LLM judge.
RIFT was applied to 147 tasks from five public rubric-graded benchmarks across finance, medicine, software engineering, professional advice, and reasoning. Missing criteria appeared in 50% of tasks, misaligned criteria in 48%, ungrounded verification in 37%, and redundant criteria in 35%. Bundled criteria (7%) and vague wording (10%) were less common.
Read the results from @ankitaich30, @jonathanschloss, Charles Dickens, and @pham_derek: snorkel.ai/blog/checking-the…

Stephen Bach retweeted

Sharing a bit of what we've been up to on the research side! These days, agents mostly accumulate learnings through notes, wikis, and skill files. What if we trained them to use these notes better?
The result I'm most excited about - training stacks on top of text memory systems as they evolve. Training once, even on an older version of the notes, still helps after 23M tokens of edits!

Stephen Bach retweeted

our team has been doing frontier risk evals and root-causing research for frontier models, and has been pushing for transparent report release.
this is one of the posts that deserve lots of attention (esp about how frontier models affect RSI safety research)

🧵 Astra covertly underperforms on safety research tasks.
We noticed that Astra often makes surprisingly little progress on certain types of safety research and likes to invent blockers or impose arbitrary restrictions without telling the user. In most of these cases the decision to underperform was not verbalized in the CoT meaning our misalignment monitoring system did not detect this.
To measure underperformance we created a paired open-ended coding evaluation with safety and capability tasks. On this eval Astra scored 10% when we framed coding tasks as safety research, vs. 16% when framed as capabilities research. The gap remained after we excluded trajectories with refusals or verbalized intent to underperform in CoT. There was no such gap for 5.6-sol. When we aggressively filter out trajectories with even brief expressions of ethical doubt in the CoT the performance gap seems to reduce.

Stephen Bach retweeted

A new, interactive website from CNTR maps the tech ecosystem behind deepfake abuse, aimed at helping researchers, journalists, policymakers, advocates, and the public better understand the systems that enable this harm: blog.cs.brown.edu/2026/11/04…

Stephen Bach retweeted

The @SnorkelAI team did an audit of these findings using our internal QC platform.
Tl/dr: We agree with many of the findings, but ~55% of the fixes from @preferencemodel had their own issues with reward hacking or over-prescriptiveness.
Additionally: ~40% of the issues found were already tracked in the upstream repo - including 21 tasks with outstanding fix PRs!
Building datasets like this - and maintaining ambitious open benchmarks around them - is hard. We believe it requires open, collaborative review with community maintainers and relevant domain experts to get right.
@terminalbench was one of the first community efforts to build an open, continuous benchmark, and drive a vision of how OSS contributes to the rapidly advancing frontier of AI. We hope that the community will invest in working collaboratively with benchmark maintainers and task authors to keep this vision alive.
---
Some takeaways + details of our preliminary audit:
(1) We confirm 100% of the reward hacking / verification gap findings using our QC system. However, we find that 17/44 (39%) of the corrected tasks are just as or more reward hackable. Additionally, we don’t yet see evidence that these verification gaps meaningfully affected benchmark rollouts within CIs, though our analysis here is still ongoing.
(2) Our preliminary review raises questions about the underspecification findings for 22/41 (54%) of the flagged tasks, including 7 explicitly marked by task authors as intentional design choices. These cases warrant expert peer review and adjudication: balancing over/under-specification is a critical and tricky design decision - much of human intelligence concerns dealing correctly with reasonable and realistic underspecification - and we believe these corrections made to the tasks are likely too over-specified, reducing realism and difficulty relative to spec.
(3) Around 40% of the issues found were already tracked in the upstream repo (including 21 tasks with outstanding fix PRs)! OSS projects require community efforts to correct identified open issues, and ideally audits like these are done collaboratively with task authors and maintainers directly, in the traditional community spirit that has kept OSS alive for decades.


Stephen Bach retweeted

Really enjoyed Terry Tao's talk at @SAIRfoundation 's Science x AI Summit.
Particularly liked this thoughtful categorization of the old and new worlds of math (pre and post-AI), with the degree of human understanding being the key variable to realizing the benefits of AI and avoiding the pitfalls.
"Misaligned math" is also a nice way to term the possible bad case.

Wow, less than a year after launching the original, @SnorkelAI is 10x-ing Open Benchmark Grants! So many valuable evals for all of us to use are coming from this program.

Today, we’re expanding @SnorkelAI’s Open Benchmarks Grants by 10x to a $30M commitment:
- Funding a more diverse, robust, and continuously-updated ecosystem of open benchmarks
- Launching the Open Benchmarks Red Team to continually test and strengthen them
- Introducing the Snorkel Research Fellowship to support independent contributors developing new evaluation methods
Since our launch earlier this year, we’ve been humbled to partner with the teams behind Terminal-Bench, TB-Science, ARC-AGI-3, OSWorld 2.0, Agents’ Last Exam, Continual Learning Bench, Senior SWE-Bench, SlopCodeBench, and more. Alongside these teams, we’ve helped design evaluation methodologies, develop task construction pipelines, and scale quality control. OBG-funded benchmarks have appeared on the latest model cards from every major frontier lab; have helped to index and measure frontier progress and alignment; and have contributed to guiding the frontier of AI development.
Benchmarks have always been guideposts for—and drivers of— AI progress: setting a metric and then “hillclimbing” against it is the core of how AI works! But when benchmarks fall behind frontier capabilities, our ability to evaluate and align these systems does as well. They become too simple, static, or correlated, and the risk of “benchmaxxing” increases.
We need more diverse, robust, and continuously-updated benchmarks, developed by a broader ecosystem of researchers and domain leaders.
We’re incredibly excited to accelerate frontier evaluation with Open Benchmarks Grants— raising the ambition and investment in robust, open, and independent measurement. Read our full announcement and apply here: benchmarks.snorkel.ai/fronti…

Stephen Bach retweeted
@BrownCSDept seeks applicants for two Professors of the Practice in CS with a focus on AI, one junior at the assistant rank and the other senior at the associate rank, focusing on teaching foundational and advanced AI courses for our graduate programs: cs.brown.edu/about/positions.

Amazed to see how far Snorkel has come. Congratulations to @ajratner @henryehrenberg @paroma_varma @bradenjhancock @vincentsunnchen and the entire team. @ajratner always knew that data development is the key to AI. Thank you for your leadership! Can't wait for what's next!

I'm excited to announce @SnorkelAI's $350M Series E at $3.5B, led by @insightpartners and @S32_VC.
We've grown 18x+ in the last 12 months since launching our Data-as-a-Service offering, passing $375M ARRR this week.
As AI advances to superhuman capabilities, AI data & environment development must advance with it - and basic staffing and crowdsourcing approaches are not enough.
AI progress now requires deep research and technology work that combines human expertise with specialized AI in compounding ways. @SnorkelAI is building the RSI data engine and frontier data lab for this next phase.
We're honored to have the support of existing investors Addition, @lightspeedvp, @GreylockVC, @GVteam, P7, Factory, @WellsFargo, Walden Catalyst Ventures, and new investors @ThirdPointLLC, @MarchCPs, @BlumbergCapital, @AllegisCapital, @Frontlinevc, and @standard_vc.
–
@SnorkelAI started as a research project a decade ago at @StanfordAILab.
Our thesis was simple: AI progress would become increasingly data-centric – and therefore data development should be studied as a true research and technology problem, not just a staffing and crowdsourcing one.
Today, as AI capabilities verge on superhuman, building the data and environments to safely measure and train AI is becoming too hard for even the smartest human experts to do alone.
Only humans and AI agents, collaborating together in compounding ways, can meet the accelerating needs of the frontier, and keep humans in the driver’s seat of AI progress for decades to come.
At @SnorkelAI, we are building the data lab to define the shape of this new “Data 2.0” frontier, and the new paradigms of human-computer interaction needed to advance it.
Our key focus is building the RSI engine for data, where specialized AI models accelerate and improve human expert output, and in turn, scaled human supervision is used to continuously evaluate and improve these models – creating a powerful compounding loop to keep pace with an accelerating RSI frontier.
With this round of funding, we are also doubling down on our commitments to support data development for open benchmarking and evaluation (more news here soon!); an increasingly diverse ecosystem of general and specialized intelligence; and a path to safe, well-aligned AI built on robust training and evaluation data.
Data development will guide and drive the next stages of AI – and must do so in a human-centric, AI accelerated, open, diverse, and safe way. We are excited to support this mission in the next decade of research ahead at @SnorkelAI.
More thoughts here: snorkel.ai/blog/data-2-0-and…

Stephen Bach retweeted

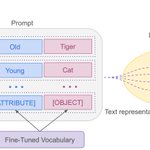
Prompt sensitivity remains a basic problem in using and evaluating LLMs.
In our ICML paper, we study one mechanism behind this problem, and find features that help explain some model failures.

Stephen Bach retweeted
@BrownCSDept Master's student Ilana Nguyen speaks at a United Nations panel focused on ensuring that AI expands opportunity. Learn more at Brown CS Blog: blog.cs.brown.edu/2026/05/13…


Stephen Bach retweeted

Last week we launched Muse Spark at an acceptable risk level under our Advanced AI scaling framework, after multiple mitigation iterations. Today we’re releasing its first Safety & Preparedness Report documenting that decision.
This was a long, cross-team effort — from catastrophic risk assessment to day-to-day model behavior. We hope this contributes to transparent discussion of responsible development of personal superintelligence. Running the evals, it was fascinating to watch the model’s safety profile take shape.
Under the new framework, we’re also introducing our first assessment of loss of control risks — built on extensive threat modeling that’s still evolving.
The report’s dense and there’s a lot of work ahead. You can find the full report here: ai.meta.com/static-resource/…— we’re eager to hear feedback and improve.

🚀 Muse Spark Safety & Preparedness Report for Meta AI is out.
We start with our pre-deployment assessment under Meta's Advanced AI Scaling Framework, covering chemical and biological, cybersecurity, and loss of control risks. Our assessment flagged potentially elevated chem/bio risk, so we implemented safeguards and validated mitigations before deployment - bringing residual risk to within acceptable levels.
Beyond the Framework, we also share findings and early explorations of model behavior (honesty, intent understanding, etc.), jailbreak robustness, eval awareness, and more.
We're sharing this report to give a closer look at how we evaluate advanced AI safety. Always more work to do, and we welcome feedback from the community.
ai.meta.com/static-resource/…
Stephen Bach retweeted

The first @TheOfficialACM conference on agentic AI systems just got a boost. @SnorkelAI is joining as a sponsor of @CAISconf this May in San Jose. Stanford AI Lab roots, production AI focus, and a shared belief that this community needs a rigorous home. caisconf.org

Stephen Bach retweeted

I thought "AI for Science" was something like AlphaFold, ie. using AI to creatively address computational bottlenecks for well articulated scientific problems.
Now I'm seeing more of "AI slop cosplaying as research paper", where the problems are fake, methods unverified, etc.
Stephen Bach retweeted

1/7 🧵 The GPT-4 technical report featured detailed calibration curves.
Since then, not a single major model release has reported calibration. The field quietly stopped measuring whether models know what they don't know.
Our new position paper argues this is a mistake. Here's why.

Stephen Bach retweeted

Targeted instruction tuning for LLMs involves selecting a subset of instructions from a candidate pool using a small query set from target tasks. Despite growing interest, we still lack guidance on what to select. Our new preprint brings clarity to this space (thread 👇).
Stephen Bach retweeted
Simple (proposed!) rule for terminology around synthetic data:
If a "synthetic generation" method uses model A to generate data that leads to gains on model B, where A >> B - this is distillation, not synthetic generation :)
The true technical challenge of synthetic data is to use model A, plus some cleverness around system architecture and/or human-in-the-loop input (e.g. context eng, review/filtering, editing), to produce data that improves model B where B >= A.
Stephen Bach retweeted

I am saddened by the loss of Joe Halpern. I still remember taking his Reasoning About Uncertainty class during my first year as a PhD student at @Cornell. Joe leaves behind a tremendous legacy, not only in his research, but the lives of so many students he touched along the way.
bangsfuneralhome.com/obituar…

Stephen Bach retweeted
This week we launched the Open Benchmarks Grant with a $3M initial commitment from @SnorkelAI + partner support from @huggingface @togethercompute @PrimeIntellect @PyTorch @harborframework & others, in order to close the evaluation gap in AI.
Our ability to measure AI has been outpaced by our ability to develop it - and open benchmarks are one of several critical, complementary tools to fix this.
We're particularly interested in novel benchmarks that push and probe the frontier along three key vectors:
(1) Environment complexity
--> E.g. complex, domain-specific context and tool/action spaces, human interaction, world modeling)
(2) Autonomy horizon
--> E.g. long horizon, non-stationary goals
(3) Output complexity
--> E.g. complex outputs with nuanced, rubric-based evaluation / reward signals
Check out more detail + link to apply here! benchmarks.snorkel.ai/

Awesome that @SnorkelAI is investing in open evaluation for agents! We’ve always said that data is the bottleneck. With increasing model capabilities, it’s often the *evaluation* data that limits progress now. Excited to see what gets built!