
Playing the infinite game of AI, products, and startups. Building, exploring, and occasionally shipping something useful. 🎮
Joined November 2021
- Tweets1.3K
- Following72
- Followers188
- Likes1.1K






Linear 过去三个季度代码改动量从 1.37M 涨到 5.82M(4.2 倍),合入的 PR 从 4,964 涨到 11,577(2.3 倍)。
不仅 PR 变多了,单个 PR 吞掉的任务也在变大:设计师和 PM 直接提 PR,agent 按整个项目而不是单个 issue 交付。
写代码这步解决之后,瓶颈全在怎么给每个 PR 自动出截图、视频和预览包来降低 Review 成本。

People keep asking how companies like Ramp, Linear, and Anthropic ship so much software with agents.
There is no new SDLC or secret set of tools. The tools are increasingly available to everyone. You can build your own, use Linear, Claude, or whatever works.
The bigger difference is ambition. These companies encourage their teams to build more, experiment more, and let agents do more of the work. That's the main different between "AI native" or not. You try to use the technology to the max.
But don't get there by adopting a tool. You get there by changing what you believe your teams are capable of.
So in the very simplest way:
- let agents build
- make it easier and faster to contribute
- increase the ambition of what your teams attempt.
In practice, that means things like:
- Standardize around cloud agents. Most of our code (5M lines last quater) is now written in Linear with our Linear cloud coding agent. Cloud sandboxes make standardizing the system and environment easier for everyone and enables faster contributions
- Linear agent (with code access and cloud agent) operates in Slack too. If there is a discussion or someone notices a problem just say "@linear fix this" (decrease the time from something noticed to fixed)
- As bugs, errors etc arrive in Linear, send them to Triage, and have Loop to auto-investigate (connect to tools like Sentry, Datadog), and write a fix
- Let designers, PMs, non-technical people contribute code where useful. If they notice a problem, tell them they can submit a fix. If they want to try something, ask them to build a prototype.
- Set up code review agent and system to make sure PRs are safe to merge.
- Run security as an automation, have agents constantly try to find security issues in your codebase, as they find, send it to a coding agent
- Instead of working on issue level, increase ambition, make a whole project, ask the agent to ask questions, investigate code base, create issues and have the agent work on the whole project at once. Set up goals like "give me proof that what you build works". All our PRs now come with screenshots and videos and preview build you can
- Bring customer feedback to the system like Linear, and make it available for your team. At Linear every project now starts with 10-500 customer notes that influence the direction of the work, and which customers we should ask to test the solution first.
- Set up Loops/automations to constantly update reference documents for agents, like product area/code owners so work can be routed to right humans
Then what is left is how do you set direction for your teams (initiatives, projects they should work on) and how do you review results (better code review, Linear does it with Guided Reviews), how you maintain quality/cohesion which is not a new problem either.
Basically most of the problems you always had remain, but the execution bit is now more and more solved.
At @linear we can help with automation, cloud agents, and code review, customer feedback and planning bits.
But we can't change your mindset or how your company operates.
If your company is still spending energy debating jira workflow steps, you're probably solving the wrong problems.

OpenCode 团队在试 Opus 5.5 主控配 DeepSeek Flash 子 Agent,核心是跳过总结只验产物,防小模型虚报测试通过。
但任务超纲返工反而更贵:楼里测 ML 代码成功率从 81% 掉到 67%,单次成本从 $1.20 涨到 $1.29。

so far this is working great. i tried this in the past and it wasn't as great. some details
- we have long running sessions per project
- opus is told to do all work in deepseek subagents
- be strict about scope when creating a task
- ask for proof of work instead of a summary
- do a one step review of the diff to make sure it's not totally off
opus is amazing at this role
Claude Code 更新了 Pro、Max 和 Ultra 套餐的 cloud sessions:自动识别仓库需要的依赖、网络访问权限和 API key,配好后把环境存下来供下次直接用,API key 加密保存、Claude 自己看不到明文。
以前把项目搬上云端跑,最烦的就是每次都要手动配一遍依赖、开网络白名单、填环境变量,现在连配环境这一步也交给模型自己探路了。
支持保存 API key 又对模型隐藏明文,解决的是云端 Agent 调外部接口时的密钥隔离问题;不过更新刚好卡在之前送的 250 美元免费额度到期之后,Team 套餐也还没跟上。
云端 Coding Agent 正在从单次沙盒变成带持久环境的托管工作区。
When I code, I barely use any skills or patterns.
Pretty much just these few lines:
1. Step back from the details and think through the underlying logic and structural design at a broader, architectural level.
2. When you hand off work or organize agents, plan out the exact context scope each agent gets and what it has to read.
3. During reviews and audits, watch for any unplanned new concepts or structures that pop up, and question whether the logic behind them is actually needed. If it is, go deeper and revisit the design; if not, kill it.
4. Spin up 100 agents, pull together all the material and facts in this domain, and lock down the core concepts and domain boundaries with me first.
5. Once the plan is ready, organize your teammates to build out this design, decide how to collaborate and what the standards are based on the requirements, and confirm with me.
读 Slack 这种高频拉数据的活,MCP 慢大概率是实现没写好;Computer Use 真正不可替代的,是那些根本没开 API、一年只点几次的公司内部老系统 nitter.gq/Yuchenj_UW/status/2118…

The biggest advantage of Codex over Claude Code right now is computer use imo, people asking me why.
1. APIs/MCPs are painfully slow. Reading a Slack channel can take forever.
2. Legacy enterprise software is often so confusing that humans struggle to use it. I couldn't figure out an expense reimbursement app. Codex figured it out and completed the task in minutes.
Computer use turns every UI into an API basically.
评测机构 METR 披露,Anthropic 上个月训完的内部模型 Model 4,在受测的全部 15 项基准测试里得分都超过了 50%,拿下该评测集最高分。
9 个月前的 Opus 4.6 还有不少项目不到 50%,而自年中公开 Mythos 5 后,Anthropic 内部已连着训出 Model 2、Model 3、Model 4 三代未公开。
同时 METR 估计,Anthropic 内部研发提速可能已达 2 倍阈值、甚至跑到 3 倍,其中约 80% 的加速来自 AI 自身,快到评测方已经担心手头缺少够难的测试题了。
当头部实验室用未公开模型把下一代研发滚起来,外面看到的公开榜单会越来越滞后于真实代差。


之前跑 opus-5.5 max,一个任务开了 40 个子代理,两个多小时就吃掉 5 小时额度的 89%,原来每 30 秒刷一次状态栏都要把整个会话重读一遍。
这次 v2.1.316+ 改成用 Haiku 5.5 读简短笔记写状态,整场会话只省 5% 额度(仅限 CLI,桌面端本来就不写这个状态栏),子代理吃额度的核心还是数量太多。 nitter.gq/ClaudeDevs/status/2118…

Kimi 今天按时放出了 Kimi K3.1 Pro 的模型权重。
之前我们跑的 7 个模型、714 场英文盲测里,Kimi K3.1 拿到 77% 胜率,和 GPT-6.1 Sol(75%)并列第一,排在 Gemini 4 Argon 和 Kimi K3 前面。
现在权重直接开源,开源模型在头部战力上已经彻底追平闭源旗舰了

Releasing the model weights of Kimi K3.1 Pro: huggingface.co/moonshotai/Ki…
We'll keep advancing open intelligence.

长期看,软件行业最后只会剩下 3 种岗位:
- 产品经理:字面意思,不用解释。
- 软件工厂维护员:相当于现在的 DevOps,但主要工作是保证整套软件生产线正常运转。
- LLM 对抗者:也就是现在的 Staff+ 级别工程师。水平高到能挑出 LLM 的毛病,在安全、过度设计、测试覆盖率上跟模型较劲,帮公司守住对齐问题。这种人不会多。
如果 LLM 继续按这个速度进化,我想不出还会有别的岗位留下来。虽然残酷,但直面现实总比装作看不见好。
Modal 每个账号每月免费送 30 美元 GPU 算力。按秒计费,够跑 12 小时 A100 80GB,或者约 6.6 小时 H200。
玩法:自己部署一个开源模型,挂成 OpenAI 兼容的 API,然后把写代码 agent 接过去。
1. 去 modal.com 注册(支持 GitHub 登录),Starter 套餐月费 0 美元
2. pip install modal && modal setup
3. git clone modal-labs/modal-examples 仓库
4. modal deploy modal-examples/06_gpu_and_ml/llm-serving/vllm_inference.py
5. 部署完会打印一个 URL,后面加上 /v1 就是一个用 vLLM 跑 Gemma 4 26B 的 OpenAI 格式接口
6. 把它作为 OpenAI 兼容接口加进 OpenCode、Cline 或你常用的工具里
支持缩容到零,没有请求就不收 GPU 的钱。
要注意的坑:最后一次请求后实例会保持预热 15 分钟,这段空闲时间也会扣额度。示例接口默认没有鉴权,把 URL 分享给别人之前记得加上鉴权。注册需要绑卡,超出 30 美元的部分会扣费。
你准备先部署哪个模型?
如图:
Starter 免费档包含 3 个席位、100 个容器、10 个 GPU 并发和每月 1 TiB 免费流量;
30 美元免费额度按秒折算,够跑 H100 7.6 小时、L40S 15.4 小时、A10 27.2 小时、L4 37.5 小时或 T4 50.8 小时。


99 美元的 Apple 开发者账号是最被低估的免费额度包:
• Xcode Cloud:每月 25 小时 CI/CD 计算时长
• CloudKit:每个应用最高 1 PB 免费 iCloud 存储
• Background Assets:200 GB 由 Apple 托管的下载流量
• WeatherKit:每月 50 万次调用
• TestFlight:10,000 名外部测试员
• Foundation Models:端侧大语言模型,不需要 API key
• 小型企业计划:抽成从 30% 降到 15%
大多数独立开发者在别的地方花钱买上面这一半的服务。
把数据受限下的 Transformer 推算到千万亿(quadrillion)参数,约为 Chinchilla 建议参数量的 7000 倍
人脑 100T 突触学 2 亿词元,Chinchilla 是 1T 参数配 20T 词元,每词元参数量差了 7 个数量级。
这项研究把集成(ensembling)写进缩放定律:单次训练用循环学习率攒快照模型,配合按比例放大的权重衰减多跑几轮,在 16 倍拟合算力下依然接近最优;算力到 10^29 FLOPs、5T 词元时,单靠堆算力 loss 还在继续降。
论文地址在原帖 nitter.gq/industriaalist/status/…

Humans are ~1,000,000x more sample efficient than LLMs, and there are no good explanations.
We’ve found that a big part of the answer is that LLMs are *massively* underparameterized by many orders of magnitude. The brain has 100T synapses learning from ~200M tokens of language. Chinchilla prescribes a 1T-parameter model on 20T tokens. That’s 7 OOMs apart in parameters per token.
After a lot of painstaking work, we present new data-constrained scaling laws and learning algorithms to scale to (extrapolated) quadrillion-parameter transformers.
w/ @akshayvegesna, @EthanBaron78553, @asatheesh6561
Full paper led by @EthanBaron78553, with @ShmuelBerman, @andrewgwils

开源了科研模型 Hydrogen-1.0,在 FrontierScience-Research 拿到 38.3%(GPT-6-Astra 是 33.3%),每题输出 API 成本约 0.25 美元。
基于 @Zai_org 的 GLM-5.3,用完整实验记录和发现轨迹做后训练,GPQA-Diamonds 93.0%。
能跑 GROMACS 分子动力学并修拓扑错误,还能在虚拟预演里抓出漏换移液器吸头这类操作失误。模型权重已上 HuggingFace,地址在原帖 nitter.gq/chenru_duan/status/211…

We’re introducing Hydrogen-1.0, our first open-weight model for scientific research. We post-trained GLM-5.3 (@Zai_org) on our internal scientific data, lab records, and discovery trajectories.
It scores 38.3% on FrontierScience-Research vs GPT-6-Astra’s 33.3% and scores 93.0% on GPQA-Diamonds.
We believe science should be open, collaborative, and democratized, rather than proprietary. Only open weights let researchers inspect, adapt and build on the unprecedented speed of AI growth. There are many recent models named by chemical elements, but we believe Hydrogen-1.0 is the first aiming towards and open scientific superintelligence for discovery. 🧵
Kaggle 免费提供 2 张 T4 GPU,32GB 显存,每周约 30 小时。
足够跑一个 30B 编程模型,接进你自己的 coding agent。
不用本地显卡,不用绑卡,整个配置只要 5 个 cell。
准备工作:
Kaggle 账号先做手机号验证(不验证没有 GPU 和联网开关)
新建 Notebook → Settings → Accelerator: GPU T4 x2
Settings → Internet: 打开
单张卡装不下时,Ollama 会自动把模型切分到两张 GPU 上。
Cell 1,安装并启动服务:
!apt-get -qq update && apt-get -qq install -y zstd
!curl -fsSL ollama.com/install.sh | sh
!OLLAMA_CONTEXT_LENGTH=32768 nohup ollama serve > ollama.log 2>&1 &
默认上下文只有 4K,给 agent 用太小了。
Cell 2,拉取单张 T4 装不下的模型:
!ollama pull qwen3-coder:30b
占 19GB。同样装得下的还有:qwen3.5:27b(17GB)、gemma4:31b(19GB)、qwen3:32b(20GB)
或者拉任意 Hugging Face 上的 GGUF:
!ollama pull hf.co/unsloth/Qwen3-Coder-30…
Cell 3,暴露公网地址:
!wget -q github.com/cloudflare/cloudf…
!dpkg -i cloudflared-linux-amd64.deb
!nohup cloudflared tunnel --url http://localhost:11434 > cf.log 2>&1 &
!sleep 8; grep -o 'https://.*trycloudflare.com' cf.log
然后在你的 coding agent 里填:
base url:上面拿到的 trycloudflare 地址 + /v1
api key:ollama
model:qwen3-coder:30b
这个地址是公开的,谁拿到都能用你的 GPU。用完关掉 tunnel,只留着自己用(Kaggle 规则禁止「server farming」挂公共服务)。
有 32GB 免费显存,你会拿来跑哪个模型?

Meta Superintelligence Labs 联合威斯康星大学、NYU、Stanford 测了 4 个模型家族的 14 组基座与后训练模型(共 42 个 Agent 测试场景),提出「Sharpening Tax」指标。
RL 后训练在单次采样(pass@1)上更准,但会把任务推向「必解」或「永不解」两个极端;在多数场景下采样不到 K=128,基座模型加轻量 harness 的 pass@K 就会反超,且模型越大反超越早。
算力充足且有可靠验证器时,大基座模型比后训练模型能覆盖更多解法。

There has been a running debate about what RL post-training actually does: does it teach new capabilities, or does it mostly "sharpen" the base model, i.e., pile probability onto a few behaviors the base model already had and suppress the rest? The evidence so far came almost entirely from math and coding, while this paper study agentic tasks.
They find that:
1. Post-trained models win at small K, but the base models' pass@K curves climb more steeply and cross over in most settings before K = 128.
2. The bigger the model, the earlier the crossover.
3. Post-training amplifies the base model's wrong modes as well as its right ones.
The paractical take away is that If you have a large compute budget and a reliable verifier, a big base model with a light harness may reach more solutions than post training it. If you get one shot, you should use the post-trained model instead.

我测了 agent-desktop(Opus 5.5)对比 cua(Opus 5.5)和 Codex 的 Computer Use(Terra 6.1)
agent-desktop 不太行,在我的 Mac 上完成了 35 个任务里的 26 个
cua 完成了 33 个,Codex 完成了 34 个
没跑通的任务是拖拽、点击 canvas 画布和滚动超长列表,都是在它的免鼠标模式下
让它接管真鼠标后,这三个任务全都一次过了
我目前还是继续用 cua 和 Codex 的 Computer Use,更稳也更快
(cua 是我自己调过的版本)

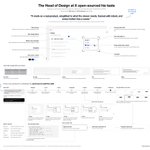
X 的设计负责人刚刚把自己的审美开源了(一个能让 agent 做出生产级 UI 的 skill)
我拆解了一下它是怎么工作的:
Benji 把自己手绘产品 UI 时会做的上百个细小决定都写了出来,好让 agent 也能照着做
整个 skill 围绕一句话展开:
“看着像真产品,只留观看者需要的部分,构图有取舍,每个动效都有起因”
它列出了 agent 做的 UI 最容易翻车的 5 个地方:
> 塞太满:每个格子里都是真字,挤作一团
> 太简陋:像线框图,看着不像真产品
> 套盒子:整个应用缩进一张卡片里,像张截图
> 太扁平:所有元素视觉权重一样
> 没风格:完全看不出你自己的品牌调性
接着 agent 按 7 步走,大部分步骤都在写代码之前完成:
1. 媒介:静态还是动画、放在哪、多大尺寸
2. 外观:浅色、深色、蓝图还是毛玻璃,配一个强调色
3. 叙事:3 到 5 个节拍
4. 范例:从几十个标杆例子里挑最接近的起步
5. 画面:只留几个真词,其余用占位线
6. 编排:节拍之间有交叠,循环结尾回到开头
7. 彩排:录下来,逐帧检查,发现问题就修
agent 会把自己的作品录下来,脚本把每一帧铺在一张表上,检查单帧跳变和文字溢出框外的问题,这些靠单张截图根本看不出来
它还会读取你的 design tokens,做出来的 UI 直接用你真实的配色、字体和圆角
他写这个 skill 的方法:给两个没有任何额外上下文的新 agent 同一句短 prompt,一个带 skill、一个不带,然后并排对比结果
哪儿看着不对,他就记下问题、更新 skill、从头重跑一遍测试,而不是自己动手改代码
支持 Grok Build、Claude Code、Codex 和 Gemini:
npx skills add benjitaylor/skills --skill stageshow

