





Pinned Tweet
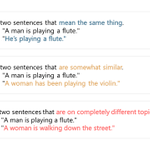
🎉 New paper 🎉 Introducing the Toolformer, a language model that teaches itself to use various tools in a self-supervised way. This significantly improves zero-shot performance and enables it to outperform much larger models. 🧰
🔗 Link: arxiv.org/abs/2302.04761
Timo Schick retweeted

one thing i've learned after doing language modeling research for ten years is that if you want your contribution to catch on it has to be *very* simple.
researchers are brought up through the paper writing process and it makes some think that you need to have novelty but novelty is basically the enemy of actual advancement.
you need to strive to have as *little* novelty as possible. every bit of additional novelty:
1. makes your contribution harder to explain
2. makes it harder to understand
3. makes it harder to implement
4. makes it harder to experiment with and verify
5. makes your contribution literally worse
i really do think that more complex things in machine learning just end up working worse. and then when you consider points 1-4, it just all piles up and makes complexity a silly endeavor.
keep it simple. it seems wrong at first, i think some people think that simpler things are stupider, but when you gain experience you notice that the simplest things are usually the smartest, best, and hardest to design and build, but they're so worth it.


Timo Schick retweeted

MAI is a really cool team of kind, highly motivated and skilled people.
Our team worked with them in the final stretch of this model contributing some of our swe 🧙♀️
proud of our Froggy team 🐸 and expect further cool updates from us...


Timo Schick retweeted

MAI-Thinking-1 is out!
Excited to share what we are building and how climbing from scratch (no distillation) actually works: simple recipes, rigorous science, self-distillation, patience, and great infra.
Check out our tech report has the full story of our RL climbs.
microsoft.ai/wp-content/uplo…


Super excited to announce seven new world-class MAI models today. They represent what we consider a new era in AI designed to keep you in control and on the frontier.
First is our text foundation model, MAI-Thinking-1, exceptionally strong on reasoning and SWE tasks.
- It’s a 35B active parameter MoE with a 256K context window. Independent human raters on Surge prefer it for overall quality in blind side-by-sides versus Sonnet 4.6, and it’s achieved 97% on AIME 2025, the key measure of its general-purpose reasoning abilities.
- It's at 53% on SWE Bench Pro, placing it right alongside Opus 4.6 on one of the toughest coding benchmarks.
- And since we co-designed our models with our own silicon, MAI-Thinking-1 is optimized on our MAIA 200 chip. Benchmarking head-to-head against the GB200, we see 30% better performance per dollar as well as a 1.4x performance-per-watt gain when running our MAI models on the MAIA 200 end-to-end.
Next is MAI-Image-2.5 and its Flash variant. Two super strong models now at #2 on the leaderboards, surpassing the score of Nano Banana 2 on image editing.
Last for now is MAI-Code-1-Flash, our new inference efficient coding model, especially tuned for VS Code and GitHub Copilot CLI.
- Code-1-Flash achieves 51% on SWE Bench Pro, despite having just 5B parameters, putting it closer to Haiku in size but cheaper in cost.
All of this is the foundation for Microsoft Frontier Tuning. It lets you customize our models to create custom, company-specific agents that only you control. You can make our model, your model. Your data. Your agents. Your moat.
Early adopters are already seeing a difference. When we tuned our models for McKinsey’s tasks, MAI delivered the highest win rate, outperforming GPT-5.5 on quality, while being 10x lower on cost.
Also really excited to be collaborating with the amazing team at Mayo Clinic to jointly train a new frontier AI model for healthcare.
Our announcements today mark another milestone on the road to humanist superintelligence. You can learn more and about our other new models in our latest blog: microsoft.ai/news/building-a…

Timo Schick retweeted

Excited to share as many details on what we @MicrosoftAI have been working on. Building a LLM from scratch is an awesome journey with pain and suffering battling unknowns but also many cool moments to see it (somehow) works out every stage! microsoft.ai/wp-content/uplo…

Timo Schick retweeted
What a ride to work with you on coding RL. Insanely fun

I feel incredibly honored to have contributed to this work alongside the most talented and hardworking team I’ve ever worked with. @MicrosoftAI
Building and climbing an LLM from scratch was full of unknowns, but there are also many magical moments when things finally worked.
Excited to share what we learned and give back to the community! microsoft.ai/wp-content/uplo…

Timo Schick retweeted

Climbing with no distillation, like the Big Boys do, has been super fun! Read the tech report for a taste of our ̶s̶u̶f̶f̶e̶r̶i̶n̶g̶ journey

Super excited to announce seven new world-class MAI models today. They represent what we consider a new era in AI designed to keep you in control and on the frontier.
First is our text foundation model, MAI-Thinking-1, exceptionally strong on reasoning and SWE tasks.
- It’s a 35B active parameter MoE with a 256K context window. Independent human raters on Surge prefer it for overall quality in blind side-by-sides versus Sonnet 4.6, and it’s achieved 97% on AIME 2025, the key measure of its general-purpose reasoning abilities.
- It's at 53% on SWE Bench Pro, placing it right alongside Opus 4.6 on one of the toughest coding benchmarks.
- And since we co-designed our models with our own silicon, MAI-Thinking-1 is optimized on our MAIA 200 chip. Benchmarking head-to-head against the GB200, we see 30% better performance per dollar as well as a 1.4x performance-per-watt gain when running our MAI models on the MAIA 200 end-to-end.
Next is MAI-Image-2.5 and its Flash variant. Two super strong models now at #2 on the leaderboards, surpassing the score of Nano Banana 2 on image editing.
Last for now is MAI-Code-1-Flash, our new inference efficient coding model, especially tuned for VS Code and GitHub Copilot CLI.
- Code-1-Flash achieves 51% on SWE Bench Pro, despite having just 5B parameters, putting it closer to Haiku in size but cheaper in cost.
All of this is the foundation for Microsoft Frontier Tuning. It lets you customize our models to create custom, company-specific agents that only you control. You can make our model, your model. Your data. Your agents. Your moat.
Early adopters are already seeing a difference. When we tuned our models for McKinsey’s tasks, MAI delivered the highest win rate, outperforming GPT-5.5 on quality, while being 10x lower on cost.
Also really excited to be collaborating with the amazing team at Mayo Clinic to jointly train a new frontier AI model for healthcare.
Our announcements today mark another milestone on the road to humanist superintelligence. You can learn more and about our other new models in our latest blog: microsoft.ai/news/building-a…
Looking forward to my first non-virtual conference in almost 2 years. If you’re attending #ICML2024 and want to chat, drop me a message 😊
Timo Schick retweeted

🤖 Want an agent that can learn new tasks from only a handful of demonstrations and no weight updates?
🚀 Check out our new work on In-Context Learning for Sequential Decision-Making, where we show how we can use transformers to few-shot learn new Procgen and MiniHack tasks.
👋 If you want to learn more about it, come chat with us at the FMDM workshop @NeurIPSConf on Friday, December 15.
🙌 Kudos to @sharathraparthy who did an outstanding job leading this work, designing and running lots of experiments, and digging deep trying to understand the model’s behavior. 🧵👇

🚨 🚨 !!New Paper Alert!! 🚨 🚨
How can we train agents that learn new tasks (with different states, actions, dynamics and reward functions) from only a few demonstrations and no weight updates?
In-context learning to the rescue!
In our new paper, we show that by training transformers on large diverse datasets of sequences of demonstrations with certain properties, we can generalize to new Procgen or MiniHack tasks from only a few demonstrations and no weight updates!
Paper: arxiv.org/pdf/2312.03801.pdf
Work with these amazing collaborators @erichammy @_roberkirk @HenaffMikael @robertarail
1/13
Timo Schick retweeted

Excited to be giving an oral presentation at @NeurIPSConf on Toolformer: Language Models Can Teach Themselves to Use Tools [arxiv.org/abs/2302.04761]!
When: Wednesday at 10:15am
Where: Ballroom A-C (level 2)
neurips.cc/virtual/2023/oral…

Timo Schick retweeted

Inflection AI just announced Inflection-2, a HUGE new 175 billion parameter language model.
Capabilities exceed Google and Meta's top models and “is very close” to catching GPT-4.
The CEO also said the company’s next model will be 10x larger in six months.

Timo Schick retweeted
Thrilled to announce that Inflection-2 is now the 2nd best LLM in the world! 💚✨🎉
It will be powering Pi.ai very soon. And available to select API partners in time. Tech report linked...
Come run with us!
inflection.ai/inflection-2
Timo Schick retweeted

It has been nothing short of incredible to be a part of this team and celebrate every accomplishment! And we’re still *just* getting started 🏃🏽♀️🏃🏽♀️🏃🏽♀️

🎉 Introducing Inflection-2, the 2nd best LLM in the world!
Get ready to experience the future of AI with us.
bit.ly/3TaUpcD
Timo Schick retweeted

🎉 Introducing Inflection-2, the 2nd best LLM in the world!
Get ready to experience the future of AI with us.
bit.ly/3TaUpcD
Timo Schick retweeted
Utterly insane weekend. So sad. Wishing everyone involved the very best.
In the meantime, we finished training Inflection-2 last night! ✨
It's now the 2nd best LLM in the world... & we're scaling MUCH further. Details v soon.
Come run with us!
Timo Schick retweeted

🚨New Paper 🚨
Self-Alignment with Instruction Backtranslation
- New method auto-labels web text with instructions & curates high quality ones for FTing
- Our model Humpback 🐋 outperforms LIMA, Claude, Guanaco, davinci-003 & Falcon-Inst
arxiv.org/abs/2308.06259
(1/4)🧵

Timo Schick retweeted

Lost in the Middle: How Language Models Use Long Contexts
arxiv.org/abs/2307.03172
Exciting work exploring the effectiveness of long context, led by @nelsonfliu and with Kevin Lin, Ashwin Paranajape, John Hewitt, @percyliang @Fabio_Petroni @MicheleBevila20

Timo Schick retweeted
Excited to announce that we’ve raised $1.3B to build one of the largest clusters in the world and turbocharge the creation of Pi, your personal AI.
forbes.com/sites/alexkonrad/…
Timo Schick retweeted
We’re proud to announce Inflection-1, the best-in-class LLM developed at Inflection!
Inflection-1, which powers Pi.ai, outperforms GPT-3.5, Chinchilla, and LLaMA on a number of academic benchmarks.
More details in our technical memo: inflection.ai/inflection-1