

founding research @datacurve, made deepswe, prev @openai @nvidia @tesla @uwaterloo
Joined November 2016
- Tweets887
- Following1.7K
- Followers1.1K
- Likes45.7K




这不就是 百万补贴 用AI送奶茶么🤣

We're giving away $1,000,000 of free pizza right now
Download and order from the Hark app: hark.com/download
Type "order a free pizza" in chat. It's first-come, first-served, delivered only in the U.S. (review details below)
Wenqi/Kevin retweeted

Intelligence is never going to taper out because good humans will always generate n+1 training data

Wenqi/Kevin retweeted

launching benches will never be setting a definitive and perfect goalpost in stone, rather directionally move models towards the right capabilities. we appreciate the community feedback and care to drive this together
As an iterative process, we’ve been cooking behind the scenes on existing issues and new innovations to keep pushing the frontier of measurement

We think it’s great that lots of people are reviewing and scrutinizing DeepSWE. It being our first benchmark, we wanted to invite public collaboration and discourse, which is why we shared all our tasks and grading results in the open.
Since then, we've made lots of improvements in our methods internally and I'm very excited about the problems we’re better able to solve as a result. Notably, we’re at a point again where no benchmarks accurately reflect the capabilities of current models, and our upcoming work will be addressing this.
Wenqi/Kevin retweeted

We think it’s great that lots of people are reviewing and scrutinizing DeepSWE. It being our first benchmark, we wanted to invite public collaboration and discourse, which is why we shared all our tasks and grading results in the open.
Since then, we've made lots of improvements in our methods internally and I'm very excited about the problems we’re better able to solve as a result. Notably, we’re at a point again where no benchmarks accurately reflect the capabilities of current models, and our upcoming work will be addressing this.


Xiaomi is live streaming their RL run climbing DeepSWE


Nearly half a year of silence. We spent it studying one problem: how far RL can scale.
MiMo-V2.6 is in the middle of its RL run right now. Three things we scaled: compute (~2B tokens per step, 1568 prompts × 16 rollouts, fully async), environments and harnesses (multi-task agentic RL, mixed across multiple harnesses in one run), and grader compute (agentic in-group credit assignment, with test-case and rubric-based rewards). We'll open-source the details piece by piece over the coming weeks.
Streaming the run: mimo.xiaomi.com/rl/
天上一天,地上一年

过去的一周真的有点疯狂,感觉像过了一个月:
- 李飞飞发布世界模型 Atlas
- Google 完成雄性果蝇完整脑神经连接图谱
- OpenAI 发布 GPT-6 Astra
- 黄仁勋称「AGI 已经到来」
- Cognition 完成 $2B 融资,估值 $48B
- Mistral 完成 $3.6B 融资,估值 $24B
- Harvey 完成 $550M 融资,估值 $15.5B
- 苹果发布首款折叠 iPhone
- Anthropic 研究员 Jacob Coxon 离职并公开警告 AI 失控风险
- DeepSeek 发布 V4.1 Flash
- Anthropic 发布最新 AI 安全与滥用报告
脑子真的跟不上这个时代的斜率了。


Astra is not thinking through every piano keypress
It maps the location of every key, then used programmatic tool calling to drive computer use!
so instead of look, think, click, repeat
-> look, code, done
not "ultrafast cua" but something bigger
every app just got an MCP!


hey Astra, how fast are you really at using a computer?
Readers added context they thought people might want to know
The video shows Astra executing a pre-planned batched sequence of mouse clicks, keyboard presses and timed waits, not live real-time high-speed control. The poster clarified hybrid inputs and advance planning in replies.
x.com/victornunez/st…
x.com/victornunez/st…
x.com/victornunez/st…
openai.com/index/gpt-6-as…
openai.com/index/computer…

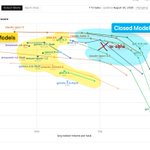
Ok ox-alpha has that big model smell
I'm getting around 63% at 47K avg output tokens on a DeepSWE subset
This is pareto optimal amongst open models and just shy of Grok 4.6 compared to closed models!


real.
I spend most of my day routing tasks between agent apps by hand:
- default T3 Code
- Grok Bot for recurring non-coding tasks
- Notion agent for context
- Cursor for branching chat
- Codex app for computer use
- Claude Code for subsidized Fable 5 on Claude Max

if these numbers are real, we have Opus 4.7 at home in 27B parameters!
Qwen3.8 27B reports 42.2% on DeepSWE and 73% on Terminal Bench 2.1, roughly Opus 4.7 level.
gonna test it myself this week
no idea where their 78.2% Opus 4.6 TB 2.1 number came from though


You can now run vscode in vscode


Introducing terminal-code: VS Code inside the terminal
- VS Code compatible CLI
- works over ssh
- syncs with your terminal theme
terminal-code.com
til gpt "pro" reasoning mode uses parallel test-time compute, sampling multiple reasoning paths and aggregating them into one final answer
so a 24-token prompt can use 4,149 input tokens

if we're comparing "up to" throughput instead of median, Gemini 3.7 Flash is already ~500 TPS and GPT-5.6 Sol Fast is ~200 TPS
"up to 750 TPS" is still impressive but it's pretty misleading to put it on the same axis as Artificial Analysis's rolling 72h P50 numbers


