

Science, Technology, and Metal enthusiast.
Earth
Joined January 2019
- Tweets648
- Following131
- Followers104
- Likes644


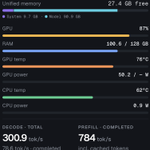


Apple M5 Max & TensorFold v1.2.4 still works best with TensorFold/Qwen3.8-27B-MLX-4bit, if you need 8bit use the 0.6.6 python engine.


TensorFold 1.2.4 is out. 🚀
Two of the measured wins in this release:
• DeepSeek-V4.1 restored a saved 319K-token conversation from NVMe in 1.2 to 1.4 seconds, versus 155 to 178 seconds, on two GB10s at CUDA TP=2 with replay prefill.
• Flash Next on M5 Ultra: two overlapping clients finished in 47 seconds instead of 127 in the MLX 4-bit parallel-serving test.
Also new: Gemma 4 E4B on CUDA, LFM3-1.7B text on Metal and Clef-Flash decisions on HIP. The HIP runtime now builds and loads on Windows too.
There are cold-loading improvements, tool-call fixes and clearer API errors.
One upgrade note: existing disk-cached prompt states need a fresh prefill after updating.
Thank you to everyone behind the code, testing and bug reports. The community puts an incredible amount of work into these releases.
@arminxnova @atasrb @Bizuayeu @BlivionIaG @codengod @defilan @devopsfortunato @unigilby @jayleaton @jishvenugopal @Wi11y010 @teleogen @lasse_ai @petruspennanen @dubsthedev @woolsey
And on GitHub: AbrahamCete, AdrianBinDC, BobClawblaw, ElderOrb, gordonhatusupy, goshi, jschmied, laidick, ppardus, shuuul and tolewis.
@petruspennanen @plotarmordev @volatilemarkts @MiaAI_lab
tensorfold.dev


Apple M5 Max & Qwen3.8-27B w/TensorFold 1.2.x, prefill ~900tps only with "TensorFold/Qwen3.8-27B-MLX-4bit", v0.6.6 - 1.1.9 work with Q6/8. Usual MLX cliff >64k, but @ashxhart may just fix it for Apple😀, tensorfold.dev/


TensorFold 1.1.5 Qwen3.8-Flash-Next-6bit-MTP on Apple M5Ultra80c256 working very nice, thanks @ashxhart ! Imagine there will be another speed boost from incoai/Qwen3.8-Flash-Next-DFlash2 when enabled (not yet supported)


TensorFold Zig engine 1.1.5 and Mac app Beta 10 are out 🙌
Beta 10 brings community-v2 benchmarks, Google sign-in fixes, updates that work through fake-IP proxies and model compatibility checks before loading. It bundles engine 1.1.4.
The standalone Zig engine is now at 1.1.5, with a lot of work from the community.
- Qwen3.8 Flash Next on GB10 with NVFP4: up to 28% faster prefill.
- Qwen3.8 Flash Next on M3 Ultra with MLX 4-bit MTP: 16% to 23% faster decode in the release tests.
- Follow-ups about the same 35k-token document: first token in 2.8s instead of 25.7s on GB10 with Flash Next FP4-Local.
- LM-5.3-Flash NVFP4 at TP=2 on two GB10s: 22% more tokens/s with two streams.
There's also Dory support on CUDA, more checkpoint formats, Drama 3 improvements, tool-call fixes and Windows CUDA build fixes.
Huge thanks to everyone contributing to the engine.
@Bizuayeu @plotarmordev @jerry543 @MiaAI_lab @agispof @softpoo @GumbiiDigital @bobclawblaw @jvr0x @ViC305 @rielstamand
And on GitHub: jschmied, BlivionIaG, harrisonfriia, drowzeys, Sapphire-Rapids and Boscoeuk.
Thanks for the reports too: @devopsfortunato, laidick, flashosophy and ss-cong.
To everyone testing, sharing access to hardware and supporting TensorFold, thank you. If I've missed anyone, I'm sorry.
@MiaAI_lab @plotarmordev @volatilemarkts @petruspennanen


Nvidia DGX Spark FE (gold box) owners with the Oct. 2026 rel, up to 2GB more usable RAM (117 to 119 free), with no monitor & Dynamic Display Reserved Memory, you need to change UEFI with KVM or SSH.docs.nvidia.com/dgx/dgx-spar…


TensorFold 1.1.0 on M5 Ultra 80c 256GB Qwen3.8-Flash-Next-MLX-6bit-MTP, awesome prefill speed 3962tps at 205k, decode 170tps - 209tps. Thanks @ashxhart


TensorFold 1.1.0 is live.
We fixed a lot of bugs, including Nemotron loading on M1-M4, Super VL tool calls, GLM long-chat caching, streaming delays and external-drive model scans, alongside new native CUDA models.
Thanks to AdrianBinDC, akol1, astro-15-alive, @bhcc2025, @Bizuayeu, BlivionIaG, BobClawblaw, @rielstamand, chaog992, cwschroeder, Deesha08, @u1tra_instinct, gilby, harrisonfriia, heitke, @jayleaton, @jishvenugopal, jkuepker, jregan-beasley-smc.
And thanks to jschmied, justincasey, @MiaAI_lab, Mirrdhyn, @MrV_777, @mweinbach, nmcbride, philip-pentatonic, @plotarmordev, @sethforprivacy, @woolsey, @petruspennanen, tovereast, tpischke, @ViC305, ZackSample; also @aojensen for work queued beyond 1.1.0.
@plotarmordev @volatilemarkts


It's taken nearly my entire life to see a worthy successor to the Lamborghini of the 80's, today Oct. 15th 2026 was the day every 1970 - 1980's kids dream car got upgraded to the 21st century, thanks @Tesla .


Absolutely inspirational, an amazing achievement by Tesla, welcome to next level engineering and style!

"Imitation is the sincerest form of flattery", sure looks a lot like a MacBook Pro. The Spark GB10 derivative inside is the real "Win" for Windows here. I guess Microsoft got sick of seeing developers all over Redmond, WA walking around with Apple logos. microsoft.com/en-us/surface/…

2026-10-05 llama.cpp 0.6.0-dev build 11431 Benchmark Apple M5 Ultra 36c/80c 256GB/4TB - Qwen3.8-27B-UD-Q8_K_L.gguf Qwen3.8-27B-DFlash2-GGUF
PP 4k - 205k: 1035 - 491 tps - Similar to 0.5.0
Decode C 1 - 4: 107.7 - 26 tps - Big improvement over 0.5.0


llama.cpp v0.6.0
github.com/ggml-org/llama.cp…

perhaps too quick on my previous post, llama.cpp 0.5.0 b11396 on 🍎M5 Ultra 80c Qwen3.8-27B Q8, still needs tuning IMHO (Metal libs too), but is workable with the right config. TensorFold kicks ass though, thanks @ashxhart and crew, and @MiaAI_lab (sparkDash adapted to macOS)


Brief exam of llama.cpp 0.5.0 on M5U 80c vs. M5Max 40c, it appears this engine has issues with Metal and is not scaling on M5U. TensorFold, oMLX, MLX-Serve and others are the best options for Mac in October 2026.

Profoundly important milestone and achievement for all Humankind, congratulations @SpaceX! There is nothing more important happening in world news today than this on 2026-09-28.

Running a local LLM on Apple M5?, skip llama.cpp 0.5.0 & give TensorFold a shot, aside from the lack of vision sidecar this is the one to run, though a Spark/Blackwell is still faster on prefill/pp. github.com/ashhart/TensorFol…


TensorFold Inference Engine is here 🚀
I spent six months making one weight read count for more than one token on Apple Silicon.
Draft tokens run through parallel lanes; the model verifies them together and keeps only what passes.
Qwen 3.8 27B MLX 4Bit - 120-124tks
Nemotron Lightning MLX 4Bit - 188-206tks
Qwen3.8 Flash Next MLX 4Bit - 88-92tks
CUDA Implementation is in Alpha showing strong gains.
The Repo is in the comments 👇🏼
