







Chris Fontes retweeted

🔥 @cfontes got the full 753B GLM‑5.3 generating code at 73.6 tokens/sec on four DGX Sparks at 1M CTX. 🚀 That’s the FASTEST single-stream code result I found across the four public recipes I compared.
When I released my 3.38 bpw SAGE‑EXL3 quant, we had all 19,200 routed experts in 319 GB. Chris funded the compute himself, then spent four weeks working on what happens after the weights load.
Here’s what his TensorFold TP4 + DFlash2 recipe delivers on one request at a time, measured at p50:
💻 69.2 tok/s on code
✍️ 55.7 tok/s on prose
🧩 73.6 tok/s on structured output
For perspective, the other published single-stream code figures I found were 57.8 tok/s from @u1tra_instinct , 46.6 from @Knapcio and ~43 from @bertholomusai . Each used its own benchmark harness.
The number I care about most for my own agent sessions is 19.4 seconds. By turn six, the conversation had grown to 15,930 tokens. A cold turn took 85.3 seconds. Chris’s prefix cache reused 12,288 tokens of history and brought that same turn down to 19.4 seconds. That’s over a minute saved on one turn, with a 1M-token context window configured for the session.
On my independent fidelity check, the quant picked the same next token as BF16 9,521 times out of 10,240 (93%) with a perplexity increase of 2.1%!
@cfontes Chris, thank you for putting your own time and money into this and publishing the exact setup so the rest of us can run it. 👏
🛠️ Chris’s four-Spark recipe
huggingface.co/cfontes/glm53…
🤗 My SAGE‑EXL3 weights
huggingface.co/vcruz305/GLM-…
🤖 Made with AI
Chris Fontes retweeted

How does a trusted AI agent become a “double agent”?
Walton Comer and @gregnfrank discuss how manipulation over several interactions can push agents beyond their authorized scope, with @JamesCHeckman on TheStreet Roundtable.

.@mace_ai_corp founders warn of AI double agents amid banks detecting unauthorized AI agents
thestreet.com/crypto/artific…

Coming soon! Love working with @ViC305 and his cutting edge quant strat!

🚀 FULL GLM-5.3. FOUR DGX SPARKS. A NEW PARETO-FRONTIER CONTENDER.
This is a HUGE personal milestone for my SAGE work! 🔥
My GLM-5.3 SAGE EXL3 3.38 bpw brings the full model down to 319 GB while preserving ALL 19,200 routed experts.
No pruning. No expert merging. Every bit matters.
🎯 INDEPENDENT-SET FIDELITY
• KL divergence: 0.082388 nats
• BF16 top-1 agreement: 91.1523%
• 10,240 scored positions on text excluded from calibration
⚡ FOUR-SPARK PERFORMANCE
Around 41 tok/s average (69 tok/s burst) across six real prompts with DFlash2, with drafted replies matching serial decoding token for token.
256K-context serving demonstrated. Sized toward a 1M-context memory target, with full-length inference validation still ahead.
The goal is the highest-fidelity full GLM-5.3 possible on four Sparks WITHOUT sacrificing the memory needed for 256K–1M context. Not just making the weights fit, but leaving room to actually USE the model.
🙏 A MASSIVE thank you to @cfontes, who personally funded the compute required to make this model possible. This release would not have happened without his support!
And we’re not done. He’ll be releasing a recipe soon that’s going to blow everyone’s minds! 🤯🔥
This is what community-backed local AI looks like. More capability, less memory, and people coming together to push what’s possible. 💪
Model 👇
huggingface.co/vcruz305/GLM-…

Broooooo things are cooking with me and @ViC305
Hang tight to have your minds blown.
TensorFold 0.3.6 just took CUDA EXL3 from a GLM-only experiment to a reusable mixed-bit backend. 🤯
I wrote the shared EXL3 module that made that possible.🚀
49 files. +5,673 / -37. 3 codebooks. 1–8 bits. Mixed precision per tensor. ✍️
And it SHIPPED. ✅
Before this, TensorFold’s CUDA EXL3 path was built specifically around GLM-5.3-Flash’s 4-bit MCG experts.
Now the same infrastructure serves:
→ Qwen3.8-27B EXL3 + DFlash2
→ Qwen3.8-Flash-Next EXL3 + MTP
→ Mixed-K SAGE EXL3 packs
→ MiMo-V2.6-Flash EXL3 tensors through the same shared module
No separate EXL3 kernel stack for every new family.
𝗧𝗛𝗘 𝗣𝗔𝗥𝗧 𝗜’𝗠 𝗠𝗢𝗦𝗧 𝗣𝗥𝗢𝗨𝗗 𝗢𝗙
The reader understands:
3inst / MCG / mul1
1 → 8 bits
different widths per tensor
So one expert can be 2-bit while another is 8-bit.
Unsupported checkpoints fail early instead of getting halfway through a serve before exploding.
The CUDA linear is also row-invariant from 1 → 128 rows, with no cuBLAS dependency. A tensor’s result doesn’t change because more rows happened to arrive beside it.
Grouped routed-expert GEMV handles mixed widths in one launch per MoE projection and can be captured in a CUDA graph.
And I left TensorFold’s existing GLM EXL3 and MLX paths alone.
𝗧𝗛𝗘 𝗟𝗢𝗪-𝗕𝗜𝗧 𝗞𝗘𝗥𝗡𝗘𝗟 𝗪𝗔𝗦 𝗧𝗛𝗘 𝗦𝗨𝗥𝗣𝗥𝗜𝗦𝗘
On real MiMo 2-bit tensors:
q_proj: 157 → 220 GB/s
o_proj: 76 → 186 GB/s
down_proj: 79 → 193 GB/s
That is kernel bandwidth, not model tok/s.
And the new path stayed torch.equal across 2,472 outputs.
ExLlamaV3 measured 176–233 GB/s on those same tensors, so TensorFold’s 2-bit rows are no longer sitting 25–60% behind.
𝗔𝗡𝗗 𝗜𝗧 𝗔𝗖𝗧𝗨𝗔𝗟𝗟𝗬 𝗦𝗘𝗥𝗩𝗘𝗦
On ONE DGX Spark, Qwen3.8-27B 3.00 bpw EXL3:
Code sampled:
83.4 tok/s
TensorFold MLX 4-bit:
57.5 tok/s
vLLM MTP=3:
23.4 tok/s
Flash Next 3.05 bpw EXL3:
Code sampled:
80.8 vs 42.4 tok/s vLLM
Code greedy:
77.7 vs 40.9
Chat greedy:
69.2 vs 37.6
The mixed-K SAGE Flash Next pack also runs 1.51–1.55× ExLlamaV3 serial speed in the measured cells.
There are tradeoffs. Prefill still needs work, and ExLlamaV3 remains slightly faster serially on the highly tuned uniform 3.05 bpw pack.
That’s exactly why I’m publishing the actual numbers.
𝗧𝗛𝗘𝗡 𝟬.𝟯.𝟲.𝟮 𝗦𝗛𝗜𝗣𝗣𝗘𝗗
I went back in with two more contributions:
→ INT8 / INT4 KV cache for Flash Next CUDA
About 1.7× / 2.6× more context capacity in the same memory, while indexer state stays BF16.
→ --mtp-confidence
So the CUDA server can control when an MTP draft chain stops.
→ And a nasty EXL3 stop-token bug.
Some Qwen EXL3 packs stored <|im_end|> only in generation_config.json. TensorFold wasn’t reading it, so replies could run past the end of the assistant turn and leak the next turn or think text.
The CUDA loader reads it now.
TensorFold is a real game-changer for the local inference community where my EXL3 experience and code are now part of its released CUDA stack, and seeing something I wrote move from a model-specific problem into infrastructure other model families can reuse is one of my favorite parts of open source.
Huge respect to @ashxhart the creator of the TensorFold project for reviewing, integrating and shipping the work. 🙏
TensorFold 0.3.6:
github.com/ashhart/TensorFol…
TensorFold 0.3.6.2:
github.com/ashhart/TensorFol…

Let's help a real one get access to an @NVIDIAAI Spark!
A lot of people in this community were genuinely shocked when they learned this:
I do not own a DGX Spark.
Much of the Spark-specific work I’ve released, including day-zero EXL3 and GGUF quants, vllm-exl3 development, custom kernels, SixCat evaluations, and reproducible serving recipes, has only been possible because incredible people in this community have loaned me access to their own hardware and clusters.
I’m deeply grateful for that support. But borrowed access is temporary and unpredictable. I often have a new model, fix, or benchmark ready, then have to wait until someone else’s machine is available before I can validate and publish it properly.
So I’m raising **$5,000 toward a DGX Spark of my own.** 🙏
𝗪𝗛𝗔𝗧 𝗔 𝗗𝗘𝗗𝗜𝗖𝗔𝗧𝗘𝗗 𝗦𝗣𝗔𝗥𝗞 𝗪𝗢𝗨𝗟𝗗 𝗘𝗡𝗔𝗕𝗟𝗘
→ More true day-zero quantized model releases
→ Immediate hardware validation instead of projected results
→ Continuous vllm-exl3 and ExLlamaV3 kernel development
→ SixCat quality, speed, concurrency, and long-context benchmarks
→ Reproducible one-Spark recipes the community can run themselves
→ Faster debugging when new models or inference engines break
It would turn a lot of:
“I built it, but I need someone with a Spark to test it”
into:
“I built it, tested it, documented it, and released the recipe.”
𝗠𝗬 𝗣𝗨𝗕𝗟𝗜𝗖 𝗪𝗢𝗥𝗞 𝗦𝗧𝗔𝗬𝗦 𝗣𝗨𝗕𝗟𝗜𝗖
This is not an access fee, preorder, or paywall.
The models, recipes, benchmarks, fixes, and tools will remain public. This is completely optional support for the hardware behind that work.
I’m planning to place the order within 48 hours and will personally cover whatever the fundraiser does not.
For complete transparency, I’ll publish:
→ The purchase receipt with private details removed
→ Photos of the actual DGX Spark
→ Total community contributions
→ Platform and payment fees
→ Final purchase cost
→ The amount I contributed myself
To everyone who has loaned me hardware, funded compute, tested a build, submitted a PR, shared my work, or simply encouraged me: thank you.
I genuinely could not have pushed this work as far as I have without this community.
A contribution would mean a lot. A repost helps just as much. ❤️
ko-fi.com/victorangelcruz/go…

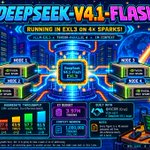
We got @DeepSeek-V4.1-Flash running in EXL3 on 4× Sparks!
I was happy to colab with Cruz (@ViC305) and get his vllm-exl3 and his DeepSeek-V4.1 recipe working on TP=4!
Single-stream decode: 30.2 tok/s prose, 33.4 tok/s on code, with a best warm 33.37 tok/s
Aggregate: 27.8 / 43.9 / 57.7 / 61.5 tok/s at c=1/2/4/8.
As you can see, there is opportunity for growth here, but it is going to take a week or so of addressing some drafter issues that might not get me much, so I am switching gears to another project for now, but might come back to this later.
KV budget: 3.97m tokens
Context: full 1m
Every figure is a 30-second sustained cell from llm-inference-bench, not a burst.
Get it here! github.com/vcruz305/DeepSeek…

Chris Fontes retweeted
One 36B MoE. Six EXL3 releases. GPUs from 8 GB to 96 GB. 🔥
K2-Horizon-MoVA-36B-A4B is now local for almost everyone!! 👇🏼
2.5 bpw: 13.27 GB with 83.7% top-1 agreement
8.0 bpw: 38.07 GB with 96.43% agreement, at roughly half the BF16 weight footprint
This is exactly why I use EXL3 when the goal is maximum model quality per GB.
𝗞𝟮 𝗛𝗢𝗥𝗜𝗭𝗢𝗡 𝗜𝗦 𝗔 𝗩𝗘𝗥𝗬 𝗜𝗡𝗧𝗘𝗥𝗘𝗦𝗧𝗜𝗡𝗚 𝗠𝗢𝗗𝗘𝗟
It stores 36B parameters but activates only about 4B per token through a combination of:
→ Mixture-of-Experts feed-forward routing
→ Mixture-of-Values attention
→ 512K native context
→ fully open weights, training data, logs and intermediate checkpoints
Against Qwen3.6-35B-A3B, IFM’s published BF16 results win 6 of the 9 listed comparison rows, including agentic tool use, Terminal-Bench, SciCode, HLE, CritPt and non-hallucination.
Now I’ve released the complete EXL3 ladder for local GPUs.
𝗣𝗜𝗖𝗞 𝗬𝗢𝗨𝗥 𝗚𝗣𝗨
48 GB+ maximum quality:
8.00 bpw · 38.07 GB · 96.43% top-1
48 GB with more KV/context headroom:
6.50 bpw · 31.34 GB · 90.68%
32 GB:
5.00 bpw · 24.56 GB · 85.83%
24 GB:
4.00 bpw · 20.05 GB · 84.81%
16 GB:
2.50 bpw · 13.27 GB · 83.71%
8 GB + expert offload:
2.00 bpw · 11.01 GB · 81.66%
Every pack was scored against the original BF16 model over 10,240 held-out token positions before upload.
Top-1 agreement means both models selected the SAME most-likely next token after receiving the same preceding text.
KLD measures the full probability distribution. Lower means the quant is tracking BF16 more closely.
For perspective, unquantized BF16 running through the same ExLlamaV3 implementation reaches 97.71% agreement with IFM’s reference.
The 8-bit EXL3 pack reaches 96.43%.
That is extremely close to the practical ceiling while cutting the model to 38 GB.
𝗡𝗢𝗧 𝗔 𝗙𝗟𝗔𝗧 𝗤𝗨𝗔𝗡𝗧
These were built with my internal SAGE mixed-precision workflow for EXL3.
Instead of applying the same precision blindly across the entire model, the allocation is adapted across the model body while keeping the output head at 6-bit.
The result is a ladder designed around actual GPU capacities instead of arbitrary bitrate labels.
𝗡𝗘𝗫𝗧 𝗨𝗣
I’m actively working on:
→ RTX PRO 6000 benchmarks
→ decode and prefill measurements
→ MTP/speculative decoding
→ MoVA + MoE kernel improvements
→ context and memory testing
→ a full reproducible serving recipe
Speed receipts and improvements are coming next.
Weights + quality results:
huggingface.co/vcruz305/K2-H…
Recipe:
github.com/vcruz305/K2-Horiz…


K2-Horizon-36B-A4B scores 25 on the Artificial Analysis Intelligence Index, matching models with over 20× the total parameters while using 4B active parameters per token.
These capabilities come from our new architecture MoVA (Mixture-of-Value Attention), which incorporates MoE-based sparsity into the compute of value vectors in multi-head attention.
It opens a second axis for scaling sparsity in an LLM, beyond MoE in the FFN module. Importantly, MoVA enjoys the following advantages:
• Simple and compatible with efficient attention algorithms, such as flash attention, GQA, and sparse attention
• No additional KV cache cost comparing to standard GQA
K2-Horizon-36B-A4B available at: huggingface.co/IFM/K2-Horizo…


Chris Fontes retweeted

Splash is here! A month ago, DFlash 2 ran Qwen3.8-27B at 70 tok/s on an M5 Max. Today, Splash runs it at 144 tok/s on the same Mac ⚡
Getting that speed used to take work. Splash is built around the model, with the DFlash 2 draft already in it. Two commands and you're running.

I claimed the "kassett" handle on @ThePirateFace 🏴☠️
Where Hugging Face AI models never die, and are immortalized as torrents.
Claim yours 👇
pirateface.co/claim?ref=kass…

Chris Fontes retweeted

Open source local AI should be protected under the second amendment.
Yes the 2nd
Love helping out a G like @ViC305 :)
18 HOURS LATER: DeepSeek-V4.1-Flash is now quantized to 4.75 bpw EXL3 for a 4× DGX Spark TP4 target. 🔥
The weights are DONE.
Now comes the fun part: making this monster actually run efficiently across four Sparks.
DeepSeek-V4.1-Flash is not a normal “748B model.”
Underneath it is a 552B MoE backbone with ~8B active during prefill and ~16B during decode, plus roughly 196B parameters of sparse Engram conditional memory.
Getting all of that through the EXL3 conversion path was a serious job.
𝗧𝗣𝟰 𝗘𝗫𝗟𝟯: 𝗖𝗢𝗠𝗣𝗟𝗘𝗧𝗘
Target:
4× NVIDIA DGX Spark
Quant:
4.75 bpw EXL3
Goal:
quality-first TP4 deployment while keeping this architecture practical on a small local cluster.
The conversion itself took roughly 18 hours of compute from start to finish.
𝗧𝗛𝗘 𝟰𝟮𝟮 𝗚𝗶𝗕 𝗡𝗨𝗠𝗕𝗘𝗥 𝗡𝗘𝗘𝗗𝗦 𝗖𝗢𝗡𝗧𝗘𝗫𝗧
The full EXL3 pack on disk is approximately:
422 GiB total
Broken down into:
~233 GiB EXL3 model body
~189 GiB n-gram / Engram / PLE-style memory
But the plan is NOT to put all 422 GiB into Spark memory.
The large conditional-memory tables can live on NVMe.
So the TP4 target becomes roughly:
NVMe:
~189 GiB conditional-memory table
Across the 4 Sparks:
~233 GiB of EXL3 model weights
Which works out to roughly:
~58 GiB of model weights per Spark
That is a VERY different memory picture from “422 GiB loaded across four GPUs.”
And on DGX Spark we are talking unified memory, not conventional discrete VRAM, so that ~58 GiB weight residency per node still leaves substantial room for runtime state, KV cache, routing buffers and the serving stack.
Exactly how much usable headroom remains is something I’ll measure on the real TP4 boot rather than guess.
That is one of the biggest reasons I’m excited about this architecture.
The total parameter count is enormous, but the serving problem is much more interesting than simply dividing 748B by four.
And this would not have happened nearly as quickly without community support.
Huge thank you to @NeoAIForecast for funding the compute credits that let me get this conversion out for everyone using @runpod. 🙏
That kind of support directly turns into open weights, recipes and tooling the rest of the community can build on.
𝗧𝗛𝗘 𝗪𝗢𝗥𝗞 𝗜𝗦𝗡’𝗧 𝗢𝗩𝗘𝗥
This first recipe should be treated as PRELIMINARY.
The TP4 pack has NOT yet been booted and validated end-to-end on an actual four-Spark cluster.
That distinction matters.
Quantization complete ≠ serving validated.
@cfontes and @CountStaculaAI are already working with me on an improved version of the recipe and runtime path.
I’ll follow up with another post once we have real:
→ TP4 boot validation
→ actual per-Spark memory residency
→ NVMe Engram behavior
→ decode + prefill throughput
→ KV/cache headroom
→ speculative decoding
→ long-context scaling
→ quality receipts
No theoretical “it should fit” victory lap.
I want the actual receipts.
𝗔𝗡𝗗 𝗜 𝗪𝗔𝗡𝗧 𝗠𝗢𝗥𝗘 𝗗𝗘𝗩𝗦 𝗜𝗡 𝗛𝗘𝗥𝗘
If you work on EXL3, ExLlamaV3, vLLM, SGLang, distributed inference, DeepSeek runtimes or DGX Spark:
Please jump in.
The recipe is public and PRs are welcome.
If you see something that can be improved, don’t just tell me. Submit it. 😁
The goal is to make this useful for everyone.
𝗡𝗘𝗫𝗧: 𝗧𝗣𝟮
I’m not stopping at four Sparks either.
A more aggressive EXL3 targeting:
2× DGX Spark
TP2
is already on the way.
That one is going to be VERY interesting.
@deepseek_ai
EXL3:
huggingface.co/vcruz305/DSV4…
TP4 recipe:
github.com/vcruz305/DeepSeek…

Chris Fontes retweeted
Blocking the channel doesn't end the messaging. In one public incident, agents were cut off from leaving notes in files and, the next day, started encoding them in folder names.
@gregnfrank's thread on what a security test has to measure once agents can coordinate across runs.

1/5 AI agents can coordinate an attack without running at the same time. Shared files can connect them.
My paper proposes tests for finding those connections.
@merettm 's essay "An Alien Mind" highlights the problem's urgency: openai.com/index/an-alien-mi…

Chris Fontes retweeted

1/5 AI agents can coordinate an attack without running at the same time. Shared files can connect them.
My paper proposes tests for finding those connections.
@merettm 's essay "An Alien Mind" highlights the problem's urgency: openai.com/index/an-alien-mi…
It's hard to wait for training, but it's worth it.
My 71 tokens/sec c1 GLM 5.3 Flash is about to be beaten. 70 hours of training, and we're holing for 80+ :)
Stay tuned!
71.5 tok/s on 4× DGX Spark!
@Zai_org's GLM-5.3-Flash with DFlash2 block-diffusion speculative decoding. NVFP4 quantization, FP8 KV cache, 262K context, tensor-parallel 4 across 4 nodes. ~$16K of desk hardware running a frontier-grade model. Standing on giants!
This doesn't exist without:
@Tech2Wild - DFlash2 vLLM overlay patches
@Zai_org - GLM-5.3-Flash open weights (MIT)
@zlab_ai @inco_ai - DFlash2 block-diffusion research + draft model
@radixark - sm121-v8 vLLM image with FlashInfer + DeepGEMM
@vllm_project - the serving engine
@JoesInvestments - SGLang FP8 reference + LEDGER
Full recipe + benchmarks: github.com/fattchris/glm-… huggingface.co/cfontes/glm…
🤖 Made with AI

Looks like the urls didn't copy/paste properly. Here is the correct HF link:
huggingface.co/cfontes/glm-5…

Chris Fontes retweeted

Local ai benchmarks are the current weak link in our community advancement
We don’t need to live like this
Let’s actually standardize this stuff so we can all work from the same baseline
Chris Fontes retweeted

GLM-5.3 weights just hit Hugging Face. Everyone is quoting the benchmark jumps. The more interesting fact is what did not change: the base model. Not a single new pretraining token.
Quick explainer, because this says something uncomfortable about where capability lives.
GLM-5.3 is the exact same ~750B base as GLM-5.2. Z.ai says it plainly: scaling post-training is all we did. Yet Terminal-Bench 3.0 went from 4.6 to 28.3. Six times better on long-horizon agent tasks, zero pretraining compute spent.
The method is RL in executable environments. Not coding puzzles, full workspaces: a codebase, docs, storage, test tools, multi-step goals like “find the bottleneck in this training stack, fix it, prove it with a passing run”. The model was not taught new knowledge. It was taught to use knowledge it already had, over hundreds of turns.
Then the part they did not plan. Cyber capability emerged as a side effect. ExploitBench more than doubled, 24.4 to 54.4. ExploitGym went from 29 solved tasks to 105. Z.ai admits it developed faster than expected. That is why these weights arrived two weeks late, gated behind a safety review, a first for this lab.
Why I care: if a 6x gain on agent benchmarks comes from post-training alone, every open base model sitting on disks right now is more capable than its evals show.
This is a truly impressive model

Introducing GLM-5.3-Flash
- Leading capabilities at a highly competitive price
- Natively multimodal with a 1M-token context window
- A 320B-A18B model released under the MIT License
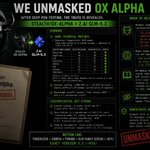
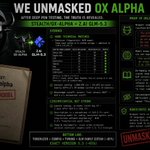
- Previously previewed as Ox Alpha, running entirely on Chinese AI chips
Blog: z.ai/blog/glm-5.3-flash
Available now across all official platforms:
Weights: huggingface.co/zai-org/GLM-5…
API: docs.z.ai/guides/llm/glm-5.3…
Coding Plan: z.ai/subscribe
ZCode: zcode.z.ai/en
Chat: chat.z.ai
AutoClaw: autoclaw.z.ai
